
Event sourcing, per aggregate
Summary. An event-sourced aggregate keeps no row of state: it keeps the facts that happened
to it, in order, and its state is what replaying them gives. The kit offers it per aggregate,
never per project: the other aggregates of the context keep their state in tables, in the same
transactions. Choose it where the history is the business; it costs storage that only grows,
stored events that can never be edited, personal data that has to be sealed, and projections
that lag. This page says when to choose it and when not, how the kit builds it, and how to move
an aggregate to it and back. The rules are in ARCHITECTURE.md, section 4
("Event-sourced aggregates"), and event-sourcing/* of section 3.
What it is
Section titled “What it is”A state-persisted aggregate is saved as its current state: the row says what is true now, and
what was true before is gone unless something else kept it. An event-sourced aggregate is saved
as the events it recorded: AttendanceRecordCreated, then NoShowNoted, then
CancellationNoted. Loading it replays them, oldest first, through one apply method per event;
the result is the state its next command decides on. Nothing else ever writes the state, so the
state a command leaves and the state a later load rebuilds are the same.
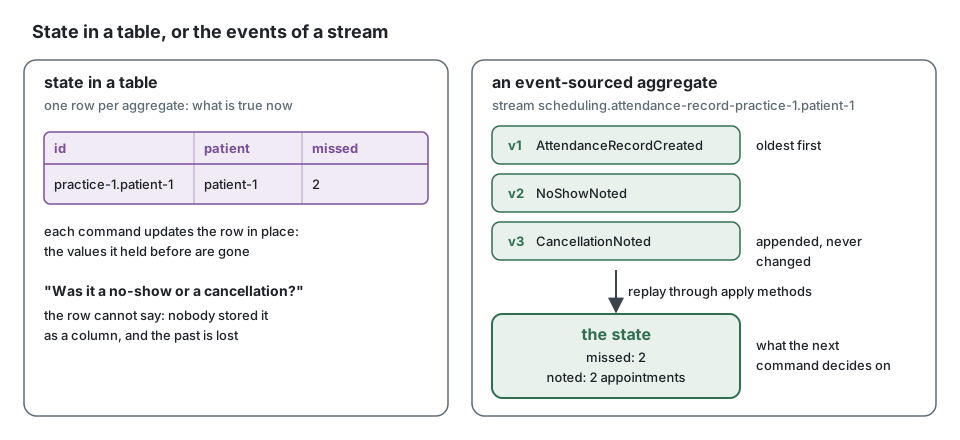
The events of one aggregate form its stream. The store keeps every stream, and the whole store in the order the appends committed, so that projections can follow it.
When to choose it, and when not
Section titled “When to choose it, and when not”| Choose it when | Prefer state in a table when |
|---|---|
| the history is what the business works with: what happened, in which order, who decided, as it was believed then (an attendance record, a ledger, a claim, a dossier) | the business asks what is true now, and the history is a log for support |
| a later question needs facts nobody stored as columns ("how many patients missed twice after a cancellation?") | the reads are lists and details of the current state |
| several read models are derived from the same facts, and new ones will be added and filled from the past | one read model, or none |
| corrections are themselves facts (a reversal, a forgiveness), never an edit | corrections are edits |
| the aggregate is small and lives long, with a modest number of events per stream | a stream would grow without bound in a short time, or the aggregate is a document edited field by field |
An audit trail is not a reason by itself: the kit records who did what around every use case (Audit trail), whatever the persistence of the aggregate.
What it costs
Section titled “What it costs”| Cost | What it means here |
|---|---|
| Storage only grows | a stream is never shortened; snapshots shorten the replay, not the stream |
| Stored events are immutable | the shape of an event stored once is read for as long as the aggregate lives: a change is a new version with an upcaster, forever (event-sourcing/upcaster-required) |
| Personal data | an event cannot be edited to forget a person: personal values are sealed with a key per data subject, and erasure destroys the key (below) |
| Projections lag | a projection fed by the store is eventually consistent with the streams; a read that must see the write it follows reads the aggregate, or a projection fed inside the unit of work |
| Appends are serialised | the PostgreSQL store gives positions in commit order by locking the head of the store until each appending transaction ends: two appends never run side by side, whatever their streams. Fine for a business aggregate, not for a firehose. An append that loses to another is a ConcurrencyError the caller retries: a duplicate version, and also a serialization failure (a unit of work at REPEATABLE READ or SERIALIZABLE) or a deadlock with row locks the same transaction took in another order. PostgreSQL may give up the other statement of the cycle, an update of a row: the unit of work then rejects with TransactionConflictError, a ConcurrencyError too. Append last in a unit of work to keep the head locked as briefly as possible |
| Debugging | the state is not in a row: a bug is found by replaying a stream, which the tests do without a database (givenEvents) |
| The team | apply methods, upcasters, snapshots and rebuilds are new habits; the rules hold the mechanical part |
How the kit builds it
Section titled “How the kit builds it”| Piece | Where | What it does |
|---|---|---|
EventSourcedAggregate<E, S> |
kernel, domain/ |
a command checks its invariants on the state, then this.record(event); the event is applied through the method appliers() names for it and kept for the save. The static rehydrate(id, history) of the aggregate calls replay, which applies the history from a snapshot when there is one and records nothing |
| apply methods | the aggregate | apply<Fact>(event), one per event, the only place that writes the state (event-sourcing/state-in-apply); they record nothing |
| the codec | infrastructure/persistence/<aggregate>-events.mapper.ts |
defineStoredEvent(Event, { version, encode, decode, upcasters }) per event, with the named type of its data |
| the repository | the port in domain/repositories/, its adapter in infrastructure/persistence/ |
the same port as any aggregate; the adapter delegates to EventSourcedRepository, which appends at the version the aggregate was loaded at (a ConcurrencyError otherwise) |
| the store | EventStore port; PostgreSQL through knex, drizzle, prisma and TypeORM; in memory for tests |
append with an expected version, each stream in order, the whole store by position, held to one contract suite |
| snapshots | SnapshotPolicy of the repository, per aggregate |
every so many events, a shape version of their own; expectSnapshotEquivalence proves them |
| projections | @Projection(name, { feed: 'event-store' }) |
applied by a CatchUpSubscription with a stored checkpoint, rebuilt from position zero by EventStoreProjectionRebuild |
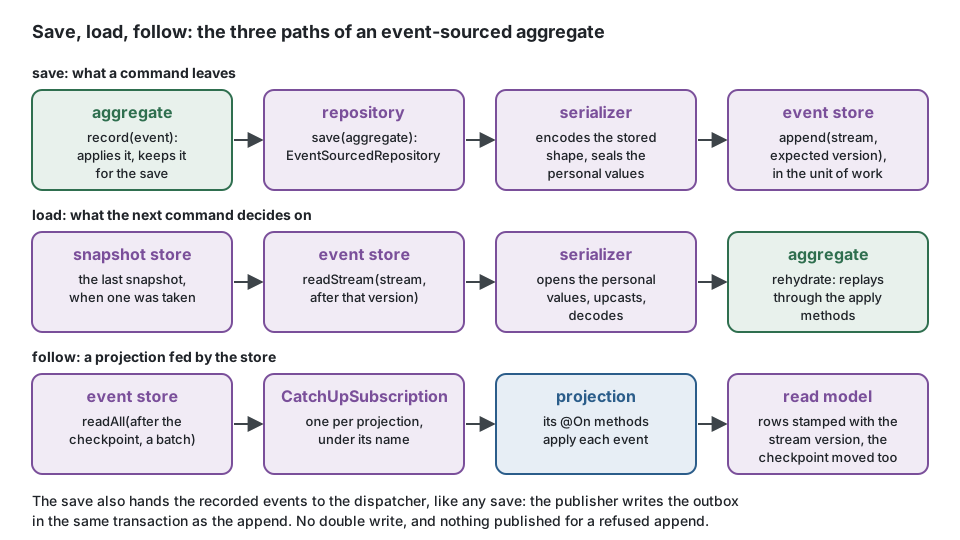
ddd-ts-kit generate aggregate <context> <Name> --event-sourced writes the aggregate with its
birth event and apply method, the codec, a builder that replays a history and a given-events
spec. The birth event is <Name>Created unless --birth "<Fact>" names the fact the business
says (--birth Triggered or --birth "Incident Triggered" writes IncidentTriggered,
incidents.incident.triggered, and the state holds triggeredAt), checked against the glossary
like any other name: the name of a stored event is kept forever. The same flag names the birth of
an aggregate that keeps its state in a table.
generate domain-event on an event-sourced aggregate adds the event to its union, to appliers() with
an empty apply method, and to the codec, each only where it is absent: run on the birth event, or
a second time, it leaves both files as they are. describe, list and CONTEXT.md say which
aggregates are event-sourced. The store they are saved through is wired by
init --event-sourcing on (init --force --event-sourcing on on an existing project), and the
generator refuses an event-sourced aggregate without it: a project whose aggregates are all rows
pays no table for it.
generate repository <context> <Name> on an event-sourced aggregate (its class extends
EventSourcedAggregate) writes no table and no row mapper: event-store-<name>.repository.ts
delegates to EventSourcedRepository over the EventStore and the PersonalDataCipher the
platform binds, with the codec of the aggregate, its snapshot policy left as a TODO(domain); the
fake is that adapter over the in-memory stores of the kernel, and the repository contract runs on
the fake and on the adapter over InMemoryEventStore (its stale-save case stays pending until
a mutate that records an event is added, which needs a business method). A stream is
<context>.<aggregate>-<id>: in a project without tenancy the application layer decides who may load an id, and
in a multi-tenant one the store keeps each stream in its tenant
(Under shared-table tenancy).
No double write. Appending the events and publishing the integration events are one
transaction: the store joins the transaction of the unit of work, and the publisher is a
before-commit handler of the domain events, which writes the outbox. The kit chose "the store
feeds the outbox" over "the outbox reads the store": the integration events keep the outbox,
its relay, its retries and its published language, and an event-sourced aggregate publishes
exactly like a state-persisted one. eventStoreUnitOfWorkContract holds every transactional
store to it: nothing is published for an append rolled back or refused by a concurrency
conflict.
Boundaries. The domain and the use cases never name the store
(event-sourcing/store-behind-repository): they load and save through the port. A projection
never appends to a stream (event-sourcing/projection-never-appends). Events are named in the
past tense (event-sourcing/past-tense).
The whole chain, in memory
Section titled “The whole chain, in memory”The pieces of the table, in one file, on the in-memory store of the kernel: an aggregate with
two events, its codec, and the EventSourcedRepository its repository adapter delegates to. A
project splits it across domain/ and infrastructure/persistence/, as the comments say.
import { NamedDomainEvent,  DomainRefusal,  EventSerializer,  EventSourcedAggregate,  EventSourcedRepository,  InMemoryEventStore,  defineStoredEvent,  type AggregateHistory,  type Appliers,  type DomainEvent,  type StoredEventTypes,} from '@ddd-ts-kit/kernel';
// domain/events: facts, in the past tenseexport class AttendanceRecordCreated extends NamedDomainEvent('scheduling.attendance-record.created') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,    readonly patientId: string,  ) {    super();  }}
export class AttendanceRecordNoShowNoted extends NamedDomainEvent('scheduling.attendance-record.no-show-noted') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,    readonly appointmentId: string,  ) {    super();  }}
export type AttendanceRecordEvent = AttendanceRecordCreated | AttendanceRecordNoShowNoted;
// scheduling.codes.tsexport const SchedulingCodes = { AlreadyNoted: 'ALREADY_NOTED' } as const;
// domain/errors/already-noted.error.tsexport class AlreadyNoted extends DomainRefusal {  readonly code = SchedulingCodes.AlreadyNoted;
  static forAppointment(appointmentId: string) {    return AlreadyNoted.refusal(`Appointment ${appointmentId} is already noted.`, { appointmentId });  }}
// domain/aggregates: the state is what the events add up toexport class AttendanceRecord extends EventSourcedAggregate<AttendanceRecordEvent> {  private noted: readonly string[] = [];
  private constructor(id: string) {    super(id);  }
  static create(id: string, patientId: string, now: Date): AttendanceRecord {    const record = new AttendanceRecord(id);    record.record(new AttendanceRecordCreated(id, now, patientId));
    return record;  }
  static rehydrate(id: string, history: AggregateHistory<AttendanceRecordEvent>): AttendanceRecord {    return new AttendanceRecord(id).replay(history);  }
  get missed(): number {    return this.noted.length;  }
  /** A command: checks on the state, then records what it decided. */  noteNoShow(appointmentId: string, now: Date): void {    if (this.noted.includes(appointmentId)) {      throw AlreadyNoted.forAppointment(appointmentId);    }
    this.record(new AttendanceRecordNoShowNoted(this.id, now, appointmentId));  }
  /** One apply method per event: an event without one does not compile. */  protected appliers(): Appliers<AttendanceRecordEvent> {    return {      [AttendanceRecordCreated.eventName]: () => undefined,      [AttendanceRecordNoShowNoted.eventName]: (event) => this.applyNoShowNoted(event),    };  }
  /** The only place that writes the state; it records nothing. */  private applyNoShowNoted(event: AttendanceRecordNoShowNoted): void {    this.noted = [...this.noted, event.appointmentId];  }}
// infrastructure/persistence/attendance-record-events.mapper.ts: one stored shape per eventinterface AttendanceRecordCreatedData {  readonly patientId: string;}
interface AttendanceRecordNoShowNotedData {  readonly appointmentId: string;}
const attendanceRecordEvents: StoredEventTypes<AttendanceRecordEvent> = {  [AttendanceRecordCreated.eventName]: defineStoredEvent(AttendanceRecordCreated, {    version: 1,    encode: (event): AttendanceRecordCreatedData => ({ patientId: event.patientId }),    decode: (data, { aggregateId, occurredAt }) =>      new AttendanceRecordCreated(aggregateId, occurredAt, data.text('patientId')),  }),  [AttendanceRecordNoShowNoted.eventName]: defineStoredEvent(AttendanceRecordNoShowNoted, {    version: 1,    encode: (event): AttendanceRecordNoShowNotedData => ({ appointmentId: event.appointmentId }),    decode: (data, { aggregateId, occurredAt }) =>      new AttendanceRecordNoShowNoted(aggregateId, occurredAt, data.text('appointmentId')),  }),};
// infrastructure/persistence: what the adapter of the repository port delegates toconst store = new InMemoryEventStore();const records = new EventSourcedRepository({  store,  category: 'scheduling.attendance-record',  serializer: new EventSerializer<AttendanceRecordEvent>(attendanceRecordEvents),  rehydrate: (id, history) => AttendanceRecord.rehydrate(id, history),});
const now = new Date('2026-03-09T10:00:00Z');
await records.save(AttendanceRecord.create('practice-1.patient-1', 'patient-1', now)); // appends at version 0
const record = await records.findById('practice-1.patient-1'); // replays the streamrecord?.noteNoShow('appointment-1', now);record?.noteNoShow('appointment-2', now);
if (record !== undefined) {  await records.save(record); // appends two events, expecting version 1}
// the stream holds created (version 1), no-show-noted (version 2), no-show-noted (version 3)await store.readStream('scheduling.attendance-record-practice-1.patient-1');
// two commands load the same version: the first append wins, the second is refusedconst first = await records.findById('practice-1.patient-1');const second = await records.findById('practice-1.patient-1');first?.noteNoShow('appointment-3', now);second?.noteNoShow('appointment-4', now);
if (first !== undefined && second !== undefined) {  await records.save(first);  await records.save(second).catch((error: unknown) => error); // ConcurrencyError, code CONCURRENCY_CONFLICT: retry the command}
Instead of changing the state in the command and recording on the side:
noteNoShow(appointmentId: string, now: Date): void { this.noted = [...this.noted, appointmentId]; // event-sourcing/state-in-apply: a replay would never do it this.record(new AttendanceRecordNoShowNoted(this.id, now, appointmentId));}record the fact, and let its apply method change the state, the same way for the command and for every later replay:
noteNoShow(appointmentId: string, now: Date): void { this.record(new AttendanceRecordNoShowNoted(this.id, now, appointmentId)); // applies it: applyNoShowNoted}Stored events are versioned like contracts with the past
Section titled “Stored events are versioned like contracts with the past”An integration event is a contract with other contexts (Event versioning); a stored event is a contract with every past version of the code. The kit applies the same discipline with its own mechanism:
- The data of a stored event is a named type in its codec file, answered by
encode. Every named type it reaches is declared in the same file too (the kit's ownPersonalValueaside): a domain type imported from elsewhere would change the stored shape without anyone seeing it, so the codec maps it to a stored type of its own. ddd-ts-kit docs --stored-eventsrecords the fingerprint of that type, and of the types it reaches, for each version instored-events.lock.json, once the shape of the version is the one to store. It reads the codecs ofinfrastructure/persistence/of the context and of each module of its model, and refuses, naming the codec file and the reason, a data type it cannot read (not declared in the file) or that declares no member: the hash of nothing would vouch for no shape (an event that carries nothing is writtentype <Event>Data = Record<string, never>), anddocs --checkreports an entry of the lock that holds it. A recorded version is never rewritten, but one recorded by 0.82.0 or earlier: that release read the type arguments of a member (Record<string, number>) apart, so that two shapes could share a fingerprint, anddocs --stored-eventsrecords it again as the kit reads it now.ddd-ts-kit docs --check, which the generated pipeline runs (npm run docs:check), fails while a declared version is not recorded, or recorded by 0.82.0 or earlier: a version cannot reach the main branch, and so a release, unrecorded. Before it is merged, a recorded version that was never stored can still be dropped from the lock by hand and recorded again.- A change of the type is a new version:
version: 2and the upcaster from version 1,upcasters: { 1: (data) => ({ ...data, reason: '' }) }. The stored event is never rewritten: it is upcast each time it is read. ddd-ts-kit checkrefuses a recorded version whose shape changed, a version above 1 without an upcaster from each version below, and a version below the last recorded. ESLint holds the two checks one file shows.
A domain event can change freely as long as encode and decode still map it to and from the
stored shapes: the stored type, not the class, is the contract.
Say version 1 of AttendanceRecordCancellationNoted stored no reason, and the business now asks
for the words of the patient. The codec declares version 2 and the upcaster that reads a
version 1 as a version 2; the events already stored stay as they are:
// contexts/scheduling/infrastructure/persistence/attendance-record-events.mapper.ts (one entry)import { defineStoredEvent, personalData, NamedDomainEvent, type PersonalValue } from '@ddd-ts-kit/kernel';
export class AttendanceRecordCancellationNoted extends NamedDomainEvent('scheduling.attendance-record.cancellation-noted') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,    readonly cancelled: { readonly patientId: string; readonly appointmentId: string; readonly reason: string | undefined },  ) {    super();  }}
/** The stored shape of version 2: what `docs --stored-events` fingerprints. */interface AttendanceRecordCancellationNotedData {  readonly patientId: string;  readonly appointmentId: string;  /** The words of the patient, sealed with the key of the patient: erased with it. */  readonly reason: PersonalValue | null;}
export const cancellationNoted = defineStoredEvent(AttendanceRecordCancellationNoted, {  version: 2,  encode: ({ cancelled }): AttendanceRecordCancellationNotedData => ({    patientId: cancelled.patientId,    appointmentId: cancelled.appointmentId,    reason: cancelled.reason === undefined ? null : personalData(cancelled.patientId, cancelled.reason),  }),  decode: (data, { aggregateId, occurredAt }) =>    new AttendanceRecordCancellationNoted(aggregateId, occurredAt, {      patientId: data.text('patientId'),      appointmentId: data.text('appointmentId'),      reason: data.optionalText('reason'),    }),  // version 1 had no reason: it is read as a version 2 where none was given, each time, never rewritten  upcasters: { 1: (data) => ({ ...data, reason: null }) },});
Personal data: crypto-shredding
Section titled “Personal data: crypto-shredding”An event cannot be edited to forget a person, and backups keep it anyway. The kit seals personal values instead:
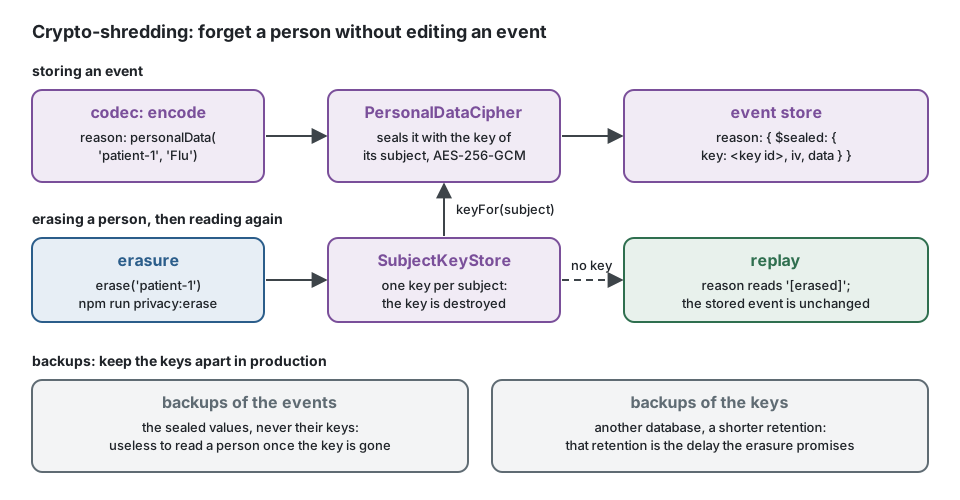
personalData(subjectId, value)marks a value inencode;PersonalDataCipherseals it with the key of its data subject (AES-256-GCM, a fresh nonce per value, the key id written next to it) before it reaches the store, and opens it when the event is read.SubjectKeyStoreis the port of the keys, one per subject: in memory, or a table of the PostgreSQL store.erase(subject)deletes the key, and a replay then readsERASED_PERSONAL_DATA([erased]) in place of every value sealed with it. A later key of the same subject never opens an older value.decodereads a personal value withdata.personalText('reason'),data.personalInstant('bornOn')ordata.personal('email', Email.of): each answersundefinedonce the subject is erased, andreadnever sees[erased]. A date or a value object read withdata.instantor indecodeitself would refuse[erased], and the aggregate would no longer load. So the field of the event that holds a personal value admits its absence, anddata.isErased('reason')tells an erased value from one never given. The cipher opens an erased value as{ $erased: { key } }, never as a text, so a text a person typed as[erased]is not taken for one. An upcaster reads the data before it is decoded and sees that shape: it passes a personal value on as it is.- A projection rebuilt after an erasure shows the erased value; a projection that already holds the clear value has to be rebuilt, or to apply an erasure event of its own.
The whole mechanism in a few lines, on the in-memory stores of the kernel:
import { NamedDomainEvent,  ERASED_PERSONAL_DATA,  EventSerializer,  InMemoryEventStore,  InMemorySubjectKeyStore,  PersonalDataCipher,  defineStoredEvent,  personalData,  type DomainEvent,  type PersonalValue,  type StoredEventTypes,} from '@ddd-ts-kit/kernel';
export class AttendanceRecordCancellationNoted extends NamedDomainEvent('scheduling.attendance-record.cancellation-noted') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,    readonly patientId: string,    readonly reason: string | undefined, // the words of the patient: personal data  ) {    super();  }}
interface AttendanceRecordCancellationNotedData {  readonly patientId: string;  readonly reason: PersonalValue | null;}
const events: StoredEventTypes<AttendanceRecordCancellationNoted> = {  [AttendanceRecordCancellationNoted.eventName]: defineStoredEvent(AttendanceRecordCancellationNoted, {    version: 1,    encode: (event): AttendanceRecordCancellationNotedData => ({      patientId: event.patientId,      reason: event.reason === undefined ? null : personalData(event.patientId, event.reason),    }),    decode: (data, { aggregateId, occurredAt }) =>      new AttendanceRecordCancellationNoted(aggregateId, occurredAt, data.text('patientId'), data.optionalText('reason')),  }),};
const keys = new InMemorySubjectKeyStore();const serializer = new EventSerializer(events, { cipher: new PersonalDataCipher(keys) });const store = new InMemoryEventStore();const stream = 'scheduling.attendance-record-practice-1.patient-1';
const noted = new AttendanceRecordCancellationNoted('practice-1.patient-1', new Date(), 'patient-1', 'Flu');await store.append(stream, 0, [await serializer.serialize(noted)]);// stored: { patientId: 'patient-1', reason: { $sealed: { key: '<key id>', iv: '...', data: '...' } } }
const [stored] = await store.readStream(stream);
if (stored !== undefined) {  const before = await serializer.deserialize(stored);  before.reason; // 'Flu': opened with the key of patient-1
  await keys.erase('patient-1'); // the right to erasure: the key is destroyed
  const after = await serializer.deserialize(stored);  after.reason === ERASED_PERSONAL_DATA; // true: '[erased]', and the stored event is untouched}
What an erasure reaches is exactly what loses the key:
- the live streams, at once, and the snapshots for what their mapper sealed: a snapshot keeps what
encodewrites, so a personal value goes throughpersonalDatathere as in an event, anddecodereads it withdata.personalTextordata.personalInstant. A value a snapshot keeps in clear outlives the erasure and is loaded back with the aggregate, until the next snapshot replaces it;privacy/snapshot-sealedreports one by its name; - every backup of the events taken after the erasure, which holds the sealed values without their key;
- a backup taken before the erasure holds both the sealed values and their key when the key
table is backed up with the events, which is the case of
PostgresSubjectKeyStorein the database of the events. Such a backup still opens the values until it expires: the erasure is complete only once the last backup older than it is gone.
So keep the keys apart in production: a SubjectKeyStore over another database whose backups
have a shorter retention than those of the events (new PostgresSubjectKeyStore(run) takes any
SqlRun, so a second connection is enough), or an adapter of your own over a key management
service, behind the same port. Then the backups of the events never carry the keys, and the
retention of the key backups is the delay the erasure promises.
That promise needs a date to start from, and the erasure has to leave it somewhere that cannot
be rewritten. auditedSubjectKeys(keys, trail, { scope, clock, ids }) of @ddd-ts-kit/audit
wraps the key store: every erase, from a script, a command or a job, writes an audit entry
(category data-access, action personal-data:erase, the subject as a data-subject
resource, keyDestroyed: true or false) with the actor and the date, in the hash chain. The
date of that entry plus the retention of the key backups is the day the erasure is complete.
The key is destroyed first and the entry written after, since the two stores, kept apart,
share no transaction: when the entry cannot be written the erasure fails, and running it again
records that no key was left, at a later date, so the completion date is never early
(@ddd-ts-kit/audit).
The right of access reads the same sealed values. EventStorePersonalDataExport of the kernel
hands over every value sealed with a key of the person, opened, one record per event under
<name>.<event type>, each value named by its path in the data; runExport of a generated
project gives it to exportDataSubject beside the exports of the contexts, as
platform.event-store (Personal data). A stream is
named after its aggregate, so the export reads the whole store; once the key is destroyed it
answers nothing.
What a context keeps of the same person in clear, the rows of its tables, is not sealed: it is
declared once next to the mapper (personalFields: the subject column, the personal columns, rows
deleted or pseudonymised, the columns that hold a file), erased through a PersonalDataErasure
port of the context, and the whole chain, the key first, then every copy in every tenant, then the
projections fed by the store, is eraseDataSubject of the kernel
(@ddd-ts-kit/kernel).
What it does not do: identifiers are not sealed. A stream named after a patient
(scheduling.attendance-record-<practice>.<patient>) keeps that identifier in the store. Use
identifiers that mean nothing outside the application.
The example keeps the keys in the table subject_keys of the scheduling schema of its own
database, next to the events, to stay runnable with one PostgreSQL; its README says so and names
what a deployment changes. Its erasure (npm run privacy:erase) destroys the key of a patient,
writes the erasure to the audit trail with the operator as actor, erases every copy the contexts
keep of the person in clear (the person of identity, the contact of notification, the notes, the
cancellation reasons and the documents of their appointments in scheduling), and rebuilds the
projections fed by the store, so that the history read model loses the clear reason too.
Projections fed by the store
Section titled “Projections fed by the store”A projection that only needs the facts of its own context is usually applied where the domain
events are dispatched, in the transaction of the command. A projection of event-sourced
aggregates can instead follow the store: declared @Projection(name, { feed: 'event-store' }),
it is applied by a CatchUpSubscription under its name, which reads the store after its
checkpoint, applies a batch and moves the checkpoint in one unit of work. A projection added
later starts at position zero and so is filled from the whole history. EventStoreProjectionRebuild
replays the store into an empty copy of the read model and swaps it in, without stopping the
subscription. Each row is stamped with the version of its stream (storedStampOf), so an event
applied twice changes nothing.
The history read model of the example is such a projection (an excerpt):
@Projection('scheduling.attendance-history', { feed: 'event-store' })export class AttendanceHistoryProjection {  constructor(private readonly history: AttendanceHistory) {}
  @On(AttendanceRecordNoShowNoted)  async noShowNoted(event: AttendanceRecordNoShowNoted): Promise<ReadModelWrite> {    const stamp = storedStampOf(event) ?? stampOf(event); // the version of the stream: applied twice, changes nothing    // ... upserts the entry `${event.aggregateId}#${stamp.version}` if it is newer  }}
applyingProjection(projection, serializer) reads the events back with the serializer of one
aggregate, and refuses (DeclarationError) a projection whose @On methods name an event that
serializer does not declare: such an event would otherwise be passed over at every batch,
silently. A projection fed by the store follows the events of one event-sourced aggregate; a
read model that joins two of them is two projections, or a projection fed by the dispatcher.
Under shared-table tenancy
Section titled “Under shared-table tenancy”The execution scope is what says that streams belong to tenants: init --tenancy shared-table
hands it to the store (InMemoryEventStore(scope), or scope in the options of
createKnexEventSourcing, createDrizzleEventSourcing, createPrismaEventSourcing and
createTypeOrmEventSourcing), and a project without tenancy does not, so nothing there is recorded
or refused. Given the scope, the store records the tenant of the work at the first append of a
stream, in the nullable tenant_id column of the events, and gives it back on each stored event
(StoredEvent.tenantId).
- Work that names no tenant is refused before any statement, with a
NoCurrentTenantError, whether it reads or appends, on a stream that exists or not, and so is work outside any execution scope. No stream is created in no tenant. - A stream of another tenant is refused with an
EventStreamTenantError, which names the stream and never the other tenant, from whatever version it is read. The repository of an aggregate answers it as it answers an id nobody saved:findByIdgivesundefined, so that a caller learns nothing of an id it does not own. - An elevation reads, it never writes. Platform staff and system jobs elevated over the tenant
(
acrossTenants) may read its streams and append to none, since a write names one tenant: a job that appends runs per tenant.
readAll and head stay open, because a subscription reads the whole store and applies each event
in its tenant; the rule event-sourcing/store-behind-repository keeps them out of the use cases. A
stream stored before the column existed has no tenant and is refused to everyone until a migration
gives it one. Every repository of an event-sourced aggregate relies on this,
generate repository --tenant-scoped included: the store is what isolates the stream, not a
condition on a statement. The same contract cases hold the in-memory store and the four ORM. A
context declared the control plane of the tenants belongs to no tenant, so it keeps its state in
tables: generate aggregate --event-sourced refuses it.
A CatchUpSubscription or an EventStoreProjectionRebuild given the same scope applies each
event in the tenant of its stream (origin event, as a consumer of the outbox runs), so the
projection reads and writes that tenant only.
Testing
Section titled “Testing”givenEvents(rehydrate, events).when(command).thenEvents([...]): the behaviour of the aggregate from a history, without a database.expectSnapshotEquivalence({ events, rehydrate, policy, state }): a snapshot rebuilds the state of the full replay, for every version of the history.eventStoreContractandeventStoreUnitOfWorkContractfor a store; the repository contract of the kit applies to the adapter like to any other.
A spec of the aggregate reads as the facts it starts from, the command, and the facts it records:
import { describe, expect, it } from 'vitest';import { givenEvents } from '@ddd-ts-kit/testing';import { EventSourcedAggregate, type AggregateHistory, type Appliers, NamedDomainEvent } from '@ddd-ts-kit/kernel';
class AttendanceRecordCreated extends NamedDomainEvent('scheduling.attendance-record.created') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,    readonly patientId: string,  ) {    super();  }}
class AttendanceRecordNoShowNoted extends NamedDomainEvent('scheduling.attendance-record.no-show-noted') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,    readonly appointmentId: string,  ) {    super();  }}
type AttendanceRecordEvent = AttendanceRecordCreated | AttendanceRecordNoShowNoted;
// the aggregate of "The whole chain, in memory"declare class AttendanceRecord extends EventSourcedAggregate<AttendanceRecordEvent> {  static rehydrate(id: string, history: AggregateHistory<AttendanceRecordEvent>): AttendanceRecord;  get missed(): number;  noteNoShow(appointmentId: string, now: Date): void;  protected appliers(): Appliers<AttendanceRecordEvent>;}
const rehydrate = (id: string, history: AggregateHistory<AttendanceRecordEvent>) => AttendanceRecord.rehydrate(id, history);const now = new Date('2026-03-09T10:00:00Z');const created = new AttendanceRecordCreated('practice-1.patient-1', now, 'patient-1');
describe('Attendance record', () => {  it('notes a no-show and counts it as missed', () => {    givenEvents(rehydrate, [created, new AttendanceRecordNoShowNoted('practice-1.patient-1', now, 'appointment-1')])      .when((record) => record.noteNoShow('appointment-2', now))      .thenEvents([AttendanceRecordNoShowNoted])      .thenState((record) => expect(record.missed).toBe(2));  });
  it('refuses to note an appointment twice', () => {    givenEvents(rehydrate, [created, new AttendanceRecordNoShowNoted('practice-1.patient-1', now, 'appointment-1')])      .when((record) => record.noteNoShow('appointment-1', now))      .thenError('ALREADY_NOTED', { appointmentId: 'appointment-1' });  });});
Moving an aggregate to event sourcing, and back
Section titled “Moving an aggregate to event sourcing, and back”To event sourcing, one aggregate at a time:
- Generate the codec and the events with the CLI, and add the apply methods: the aggregate compiles against both its rows and its events while the rest of the steps run.
- Declare a birth event that carries the whole current state (
<Name>Migrated, or the birth event with its fields), with its stored shape. - A migration script, in one transaction per batch: for each row, append that event to the stream of the aggregate at version 0. A stream that already exists is skipped: the script can run again.
- Switch the binding of the repository port to the event-store adapter. The table becomes read-only; drop it in a later migration, once a release has run on the streams.
- Rebuild the projections that the table fed, from the store if they become store-fed.
Back to state in a table: replay each stream once into the state, write the row, switch the binding of the port back, and keep the streams as an archive or delete them, after checking what the law asks of the history (the erasure keys go with them). Both directions keep the port, the use cases and the domain events untouched; only the aggregate's internals, its adapter and its storage change.
What each adapter gets
Section titled “What each adapter gets”| Store | Status |
|---|---|
| in memory | InMemoryEventStore, InMemorySnapshotStore, InMemoryCheckpointStore, InMemorySubjectKeyStore: tests and single-process applications; not transactional |
| PostgreSQL through knex | createKnexEventSourcing, tables by createEventStoreTables in a migration |
| PostgreSQL through drizzle | createDrizzleEventSourcing, tables declared by eventStoreTables for drizzle-kit |
| PostgreSQL through Prisma | createPrismaEventSourcing over the raw queries of the client, models of prisma/event-store.postgresql.prisma |
| PostgreSQL through TypeORM | createTypeOrmEventSourcing over the entity manager, tables as eventStoreEntities |
| MySQL, SQLite | not provided: the store relies on PostgreSQL statements (a jsonb record set, an update and an insert in one statement) |
| KurrentDB (EventStoreDB) | a later adapter. Its streams, expected revisions and $all subscriptions fit the port, but it is a separate store: the outbox and the processed-event store of the context cannot share its transaction, so "no double write" would move to "the outbox reads the store" (a subscription that publishes), its positions are log offsets, not the gapless 1, 2, 3 the contract states, and its client and server image are too heavy for the suites of this repository to run it honestly |
All the PostgreSQL stores are one implementation in the kernel (PostgresEventStore and its
companions over a SqlRun); each ORM package only runs its statements, and each is held to the
same contract suites.
Limits
Section titled “Limits”readAllandheadare not tenant-scoped: they feed the subscriptions, which run on a context of their own and apply each event in its tenant. Give them to infrastructure only.- One event store per database schema:
init --event-sourcing onwires one, in theevent_storeschema, bound bysrc/platform/event-sourcing/with the keys of the data subjects and the cipher; a context that keeps its own binds its stores in its module rather than in the platform. - Appends are serialised per store (above).
- A projection fed by the store whose rows each come from several streams cannot be stamped by stream version alone: stamp it by event id and instant.
- The past-tense check is a list of words, not a grammar; an irregular verb it does not know is suppressed with a reason.
- Under a tenancy,
inithands the execution scope to the event store (persistence.eventSourcingis then a function of the scope). It generates no catch-up subscription: a project that runs one passes the samescopetoCatchUpSubscriptionandEventStoreProjectionRebuild. generate projectionandgenerate repositoryhave no event-sourced form yet: the projection fed by the store and the repository adapter are written by hand (the example shows both).
Sources
Section titled “Sources”- Martin Fowler, "Event Sourcing", 2005, https://martinfowler.com/eaaDev/EventSourcing.html
- Greg Young, Versioning in an Event Sourced System, Leanpub, 2017
- Vaughn Vernon, Implementing Domain-Driven Design, Addison-Wesley, 2013, appendix A
- Martin Kleppmann, Designing Data-Intensive Applications, O'Reilly, 2017, chapters 4 and 11
- "Crypto-shredding", as described for event stores by Mathias Verraes and others: erase by destroying the key
See also
Section titled “See also”- Personal data in a generated project: the declaration of the personal columns of a table, the erasure that reads it, and what the keys of the store add to it
- Aggregates, Domain and integration events
- Transactional outbox, Event versioning
- CQRS as used here
- The example:
examples/scheduling, the attendance record of the scheduling context