
@ddd-ts-kit/kernel
The building blocks every context depends on, and nothing else: no framework, no ORM, no
logger, no dependency at all. It is the only package of the kit domain/ may import;
application/ imports it too, and @ddd-ts-kit/auth next to it for permissions and policies.
npm i @ddd-ts-kit/kernelThree entries: @ddd-ts-kit/kernel (the building blocks, the ports, the standard interfaces and
their doubles), @ddd-ts-kit/kernel/declarations (the decorators with which a class says
what it is, see "Declarations") and @ddd-ts-kit/kernel/testing (the recording buses of a
spec, see "The spec of a reaction").
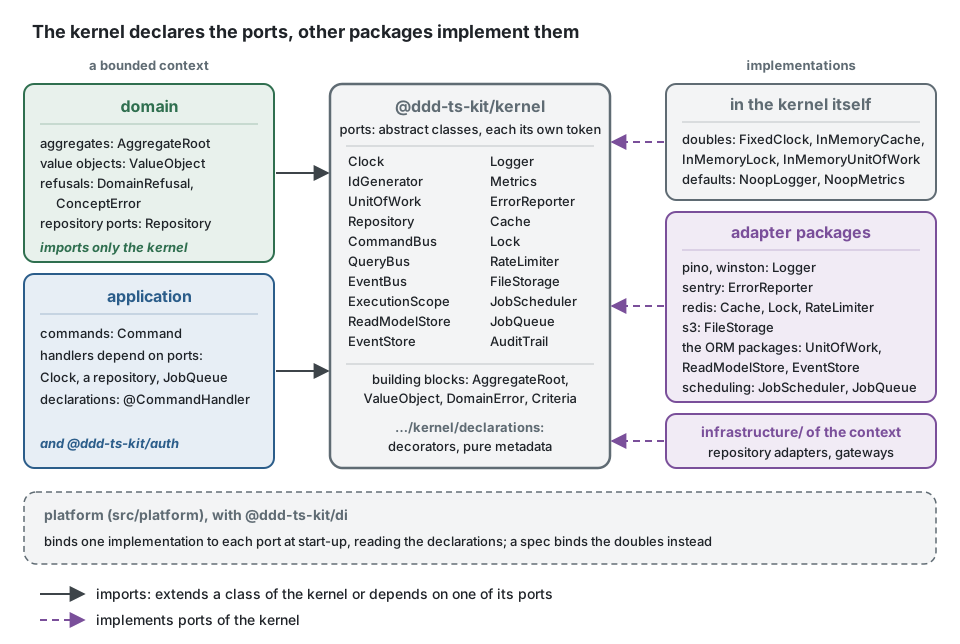
The kernel says what a context needs (a Clock, a UnitOfWork, a Logger) and never
how: every port is an abstract class with abstract members only. Its implementations live
elsewhere: the doubles and in-process versions of the kernel itself for tests and a single
process, the adapter packages of the kit (@ddd-ts-kit/pino, @ddd-ts-kit/redis,
@ddd-ts-kit/s3, the ORM packages, ...) for production, and the infrastructure/ of each
context for its own repositories and gateways. The platform chooses one per port when it
starts, so a business rule never changes with a library.
What is inside
Section titled “What is inside”| Area | Exports |
|---|---|
| Domain | Entity, AggregateRoot (version, recorded events), ValueObject, DomainEvent, DomainError with a stable code, ConceptError (the errors of one concept, each built by a static factory: see "Domain errors"), DomainRefusal (one class per refusal, built by static factories), FactualRefusal, isRefusal, CodeOf, RefusalOf, Refusal, RefusalFacts, the generic InvariantViolation, NotFoundError, ConflictError (and UniqueViolationError, a value a unique constraint keeps already held), ConcurrencyError, PreconditionFailedError, Result with ok, err, unwrap |
| Ports | Clock, IdGenerator, UnitOfWork, Repository (abstract classes: each one is its own injection token), UseCase, DependencyKind (the roles a binding declares, read by di, tracing and aspects: repository, gateway, external, use-case, publisher, consumer, domain-event-handler, job) |
| Buses | Command, Query, CommandBus, QueryBus, BusMiddleware, the in-process InMemoryCommandBus and InMemoryQueryBus (register(type, handler, { context }) names the bounded context in MessageInfo), unitOfWorkMiddleware |
| Events | IntegrationEvent, IntegrationEventPublisher, IntegrationEventSubscriber, EventBus (both at once), EventSubscribers (the subscriber of each bounded context), ProcessedEventStore, idempotent, InMemoryEventBus (runs every handler of an event, then rejects with an AggregateError of the failures; with { failures: 'as-thrown' }, the default in a later minor version, the failure of a single handler is rethrown as it is, with its code), EventBusFailures, DomainEventDispatcher, IntegrationEventCallback and DomainEventCallback (the functions a subscriber and a dispatcher are given), executionContextOfEvent, inEventScope, scopedPublisher, EventDelivery (what a provider says of one delivery: attempt, last attempt, transport, source, consumer), messagingSystemOf |
| Domain events and the unit of work | dispatchingOnSave (the wrapper that makes a repository hand over what the aggregates it is given recorded), announceDomainEvents, withinUnitOfWork (what every UnitOfWork.run is built on: queue, dispatch before the commit, after-commit phase), unitOfWorkStage and UnitOfWorkStage, DomainEventPhase, DomainEventSubscription, SaveAfterCommitError, AfterCommitFailure, reportAfterCommitFailures, InMemoryDomainEventDispatcher |
| State machines | defineStateMachine, StateMachine, TransitionError, InvalidStateMachineError, mermaidOfStateMachine (see "State machines") |
| Actor | Actor, AuthorizedCommand, AuthorizedQuery, ActorContext, systemActor |
| Standard interfaces | Session, ExecutionContext and ExecutionScope, Logger, Metrics, ErrorReporter, Cache, CacheInvalidation and CachePurger (with cacheTag, tenantCacheTags, CachePurgeRequest, PublishedCacheInvalidation, PurgingPublisher, RepeatedCachePurger: see "Purging the HTTP caches"), Lock, RateLimiter, Page and PageRequest, AuditStamp, TenantScoped, AuditTrail, AuditReader and AuditEntry |
| Scheduled jobs | JobScheduler, ScheduledJob, JobExecution, JobSchedule, JobOptions, JobDefinition, JobRun, JobDescription, parseJobSchedule, describeJobSchedule, jobPolicy, executionContextOfJob |
| Background jobs | JobQueue, BackgroundJob, BackgroundJobExecution, BackgroundJobPayloadSchema, processTimeoutDuePayload, EnqueueOptions, QueuedJob, QueuedJobStatus, backgroundJobPolicy, retryDelayMs, executionContextOfBackgroundJob, whenCommitted (see "JobQueue") |
| Process managers | ProcessManager, ProcessDecision, ProcessRunner, ProcessStore, InMemoryProcessStore, UnreadableProcessStateError (see "ProcessRunner and ProcessStore") |
| Files | FileStorage, StoredFile, FileScanner, FileKeys, TenantFileKeys, FileStaging, FileUpload, fileUploadsMiddleware, FileInspection, FileError, InMemoryFileStorage, LocalFileStorage, PurgeStagedFiles (see "FileStorage, StoredFile, FileScanner") |
| Tenancy | tenantScopeOf, tenantReachOf, acrossTenants, tenantKey, tenantCacheKey, isTenantId, TenantDirectory, InMemoryTenantDirectory (see "Tenancy") |
| Event sourcing | EventSourcedAggregate, EventStore, defineStoredEvent, EventSerializer, EventSourcedRepository, SnapshotPolicy, personalData, PersonalDataCipher, CatchUpSubscription, EventStoreProjectionRebuild, InMemoryEventStore, PostgresEventStore (see "Event sourcing") |
| Personal data | personalFields, PersonalDataErasure, PersonalDataExport, eraseDataSubject, exportDataSubject, PersonalDataExportDocument, inEachTenant, recordsInEachTenant, isDataSubjectId, PersonalDataRecord, InMemoryPersonalData (see "Personal data") |
| Read side | Criteria, defineCriteria, validateCriteria, scoped, planCriteria, evaluateCriteria, pageOfPlan, hydrate, ReadModelStore, stampOf, TableReadModelStore, ProjectionRebuild, InMemoryReadModelStore (see "Criteria", "Hydration" and "Projections") |
| Persistence helpers | optimisticUpdate, expectVersion (the version a caller read, If-Match over HTTP, still the current one, else PreconditionFailedError: 412), schemaNameOf, stampCreation, stampUpdate, tenantScopeOf, encodeCursor, decodeCursor |
| Error reporting | ErrorReporter, ErrorReport, errorReportOf, reportOnce, isUnexpectedError, errorReportingMiddleware, DeadLetterReports, reportProcessFailures, NoopErrorReporter |
| Doubles | FixedClock, SequentialIdGenerator, InMemoryUnitOfWork, FixedActorContext, FixedExecutionScope, InMemoryLogger, InMemoryMetrics, InMemoryErrorReporter, InMemoryCache, InMemoryCacheInvalidation, InMemoryCachePurger, InMemoryLock, InMemoryRateLimiter |
Testing (@ddd-ts-kit/kernel/testing) |
RecordingCommandBus, RecordingQueryBus: buses that keep every message they are handed, in order (executed), and answer what the spec told them (answering(type, answer)), nothing otherwise (see "The spec of a reaction") |
Declarations (@ddd-ts-kit/kernel/declarations) |
Requires, Public, CommandHandler, QueryHandler, IntegrationEventHandler, DomainEventHandler, Scheduled, Background, Projection, On, applyingProjection, Repository, Gateway, Adapter, Policy, Edge (for the decorators of a transport package, such as @Controller), injected, injectedDependencies, declarationOf, listDeclarations, DeclarationError, Token, describeToken, tokenIdentity, portDefect |
The rules these blocks serve are in docs/ARCHITECTURE.md.
A first aggregate
Section titled “A first aggregate”The four building blocks of a model, in one file for the reading (a project gives each its own
file, and ddd-ts-kit generate writes them):
import { AggregateRoot, DomainRefusal, Entity, ValueObject, NamedDomainEvent } from '@ddd-ts-kit/kernel';
// The codes of the context, in <context>.codes.ts, and its refusals, one class each (see "Domain errors").export const OrderingCodes = {  InvalidQuantity: 'INVALID_QUANTITY',  OrderAlreadyPlaced: 'ORDER_ALREADY_PLACED',  OrderEmpty: 'ORDER_EMPTY',} as const;
export class InvalidQuantity extends DomainRefusal {  readonly code = OrderingCodes.InvalidQuantity;
  static forUnits(units: number) {    return InvalidQuantity.refusal(`${units} is not a positive whole quantity.`, { units });  }}
export class OrderAlreadyPlaced extends DomainRefusal {  readonly code = OrderingCodes.OrderAlreadyPlaced;
  static forOrder(orderId: string) {    return OrderAlreadyPlaced.refusal(`Order ${orderId} is already placed.`, { orderId });  }}
export class OrderEmpty extends DomainRefusal {  readonly code = OrderingCodes.OrderEmpty;
  static onPlacement(orderId: string) {    return OrderEmpty.refusal(`Order ${orderId} has no line to place.`, { orderId });  }}
// A value object: immutable, compared by value, valid once built.export class Quantity extends ValueObject<{ readonly units: number }> {  private constructor(props: { readonly units: number }) {    super(props);  }
  static create(units: number): Quantity {    if (!Number.isInteger(units) || units <= 0) {      throw InvalidQuantity.forUnits(units);    }
    return new Quantity({ units });  }
  get units(): number {    return this.props.units;  }}
// An entity: known by its identity, reached only through its aggregate root.export class OrderLine extends Entity {  constructor(    productId: string,    readonly quantity: Quantity,  ) {    super(productId);  }}
// A domain event: a fact of the past, named <context>.<aggregate>.<fact>.export class OrderPlaced extends NamedDomainEvent('ordering.order.placed') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,    readonly lineCount: number,  ) {    super();  }}
// The aggregate root: the only way in, every rule checked by an intention method.export class Order extends AggregateRoot {  private readonly lines: OrderLine[] = [];  private placed = false;
  private constructor(id: string) {    super(id);  }
  static open(id: string): Order {    return new Order(id);  }
  add(productId: string, quantity: Quantity): void {    if (this.placed) {      throw OrderAlreadyPlaced.forOrder(this.id);    }
    this.lines.push(new OrderLine(productId, quantity));  }
  place(now: Date): void {    if (this.placed) {      throw OrderAlreadyPlaced.forOrder(this.id);    }
    if (this.lines.length === 0) {      throw OrderEmpty.onPlacement(this.id);    }
    this.placed = true;    this.record(new OrderPlaced(this.id, now, this.lines.length));  }}
// What a spec of the aggregate checks:const order = Order.open('o-1');order.add('p-7', Quantity.create(2));order.place(new Date('2026-01-05T09:00:00Z'));
order.pullEvents(); // [OrderPlaced { aggregateId: 'o-1', lineCount: 1, ... }]Quantity.create(2).equals(Quantity.create(2)); // true: same valuenew OrderLine('p-7', Quantity.create(1)).equals(new OrderLine('p-7', Quantity.create(5))); // true: same identity| Block | What the kernel gives it |
|---|---|
Entity<Id> |
id and equals: two entities are equal when their class and their id are |
ValueObject<Props> |
frozen props, equals by value (dates by their time, lists and records deeply), toJSON |
AggregateRoot<Id> |
an entity with version, the optimistic concurrency token its repository adapter manages, record(event) for its methods and pullEvents(). The recorded events are not enumerable: spreading, comparing or serialising an aggregate never sees them |
DomainEvent |
an interface: name, occurredAt, aggregateId |
Instead of changing the state from outside, where every caller has to remember the rule:
order.status = 'placed'; // nothing checks that the order has linesevents.push({ name: 'ordering.order.placed' }); // and nothing ties the fact to the changewrite one intention method on the aggregate, which checks the rule and records the fact in the same move:
order.place(clock.now());Result, ok, err and unwrap are for a project that has value objects answer their
refusal instead of throwing it ("stack.valueObjects": "result"). Why each block exists:
Aggregates and
Entities and value objects.
Domain errors
Section titled “Domain errors”A business refusal is a DomainError: an answer the code planned for, known everywhere by its
code. A context has one class per refusal, named after what is refused, which extends
DomainRefusal; its static factories are named after what the refusal is about, and the code
of every refusal of the context is written once, in the closed list <context>.codes.ts:
import { DomainRefusal } from '@ddd-ts-kit/kernel';
declare const calendar: { readonly id: string };declare const slot: { readonly startsAt: Date };
// scheduling.codes.tsexport const SchedulingCodes = {  SlotTaken: 'SLOT_TAKEN',  UnknownAppointment: 'APPOINTMENT_NOT_FOUND',} as const;
export type SchedulingCode = (typeof SchedulingCodes)[keyof typeof SchedulingCodes];
// domain/errors/slot-taken.error.tsexport class SlotTaken extends DomainRefusal {  readonly code = SchedulingCodes.SlotTaken;
  static forCalendar(calendarId: string, startsAt: Date) {    return SlotTaken.refusal(      `The slot starting at ${startsAt.toISOString()} on calendar ${calendarId} is already held.`,      { calendarId, startsAt },    ).exposing('startsAt');  }}
// domain/errors/unknown-appointment.error.tsexport class UnknownAppointment extends DomainRefusal {  readonly code = SchedulingCodes.UnknownAppointment;
  static forAppointment(appointmentId: string) {    return UnknownAppointment.refusal(`Appointment ${appointmentId} does not exist.`, { appointmentId });  }}
throw SlotTaken.forCalendar(calendar.id, slot.startsAt);| Member | What it does |
|---|---|
readonly code |
written by the class, read from the list of its context under its own name: one code per class, whatever the factory |
protected static refusal(message, facts?) |
builds the refusal of a factory: an instance of the class it is called on, typed with its code and those facts. The constructor is protected and a subclass declares none, so outside its class a refusal exists only through a factory |
protected exposing(...names) |
called on the refusal by its factory: these facts may leave the process. None does by default |
protected causedBy(cause) |
called by its factory: the error this refusal translates, as cause |
message, name, cause |
as on any DomainError; name is the class |
facts |
every fact the factory was given, as plain data (RefusalFacts: text, numbers, booleans, dates, null, lists of them), for the code that catches the error and for the tests |
exposedFacts |
the facts a client may read: what @ddd-ts-kit/http writes under facts in the problem document |
toJSON() |
{ name, code, message }, plus facts when some are exposed: never the stack, the cause or a private fact |
static is(error) |
narrows what was caught to this refusal, with the facts of each of its factories |
Instead of a bare Error, which nothing downstream can tell from a bug:
throw new Error(`Slot ${startsAt.toISOString()} is taken`); // reported as unexpected, answered as a 500write the refusal, which every layer knows by its code:
throw SlotTaken.forCalendar(calendar.id, slot.startsAt); // a planned answer: a 4xx with code SLOT_TAKENThe HTTP status of each code is chosen in the presentation layer, in one place; the error
logs, the spans and the audit trail record the code, and the error reporter leaves a
DomainError alone (the two exceptions are under "ErrorReporter").
The codes the packages of the kit raise are a list too, KitCodes, with its type KitCode:
KitCodes.Forbidden is 'FORBIDDEN', KitCodes.ValidationFailed is 'VALIDATION_FAILED', and so on for
NotFound, Conflict, InvariantViolation, Unauthorized, NotAcceptable, ConcurrencyConflict,
InvalidCriteria, InvalidPageRequest, Timeout, CircuitOpen, BulkheadFull, AttemptsExhausted,
ServiceUnavailable, PreconditionFailed, PreconditionRequired, FileTooLarge, UnsupportedMediaType,
FileNotFound, FileRejected and InvalidFileKey. A route names them in errors and a test expects them
(rejects.toMatchObject({ code: KitCodes.Forbidden })) without writing the string: the editor completes
the key, and a misspelled one does not compile.
The codes of a context are a closed vocabulary, SchedulingCode: isRefusal(error, SchedulingCodes)
narrows what was caught to one of them, so a switch on its code is exhaustive, and the class of
one refusal knows its facts:
import { isRefusal } from '@ddd-ts-kit/kernel';
if (isRefusal(error, SchedulingCodes)) {  switch (error.code) {    case 'SLOT_TAKEN':      return 'choose another slot';    case 'APPOINTMENT_NOT_FOUND':      return 'book again';  }}
if (SlotTaken.is(error)) {  retryAfter(error.facts.startsAt); // a Date}
isRefusal(error, 'SLOT_TAKEN'); // whatever the class: the code is what everything downstream keys on
A factory lets its return type be inferred: an annotation : SlotTaken would hide its facts
from is.
Facts are private. A message is written for a human and answered to the client as detail;
the facts are data, and stay in the process unless the factory names the ones that may leave.
Never expose what identifies a person. The audit trail and the spans record the code alone.
One class per concept is the form of ConceptError, and keeps working: a class gathers the
refusals of one concept, each a factory named after the refusal that sets its own code, and
CodeOf<typeof AppointmentError> is the union of its codes.
import { ConceptError, type CodeOf } from '@ddd-ts-kit/kernel';
export class AppointmentError extends ConceptError {  static slotTaken(calendarId: string, startsAt: Date) {    return AppointmentError.refusal('SLOT_TAKEN', `The slot at ${startsAt.toISOString()} is held.`, {      calendarId,      startsAt,    }).exposing('startsAt');  }}
export type AppointmentErrorCode = CodeOf<typeof AppointmentError>; // 'SLOT_TAKEN'
ConceptError has the members above, but refusal(code, message, facts?) takes the code, and
AppointmentError.is(error, 'SLOT_TAKEN') narrows to one code of the class. ConceptError and
DomainRefusal share FactualRefusal, the facts and their exposure, which is what
@ddd-ts-kit/http reads.
One class per error is the form of 0.1 and 0.2, and keeps working: DomainError is still
abstract over code, its constructor still public, and InvariantViolation, NotFoundError,
ConflictError and ConcurrencyError, each one refusal under a fixed code, are still built
with new.
export class SlotTakenError extends DomainError { readonly code = 'SLOT_TAKEN';}A project says which form it writes with "stack.refusals" in ddd-ts-kit.config.json
(named, what init writes; factories, one class per concept; or classes, what a config
without the key means); the errors/* rules hold the first two, and ddd-ts-kit error-factories
moves a project from the others to named. The forms can live in one project.
State machines
Section titled “State machines”import { AggregateRoot, DomainRefusal, defineStateMachine } from '@ddd-ts-kit/kernel';
export const ParcelStatus = { Registered: 'registered', Shipped: 'shipped', Delivered: 'delivered' } as const;export type ParcelStatus = (typeof ParcelStatus)[keyof typeof ParcelStatus];
// shipping.codes.ts, then one class per refusalexport const ShippingCodes = { ParcelUnpaid: 'PARCEL_UNPAID', ParcelTransitionRefused: 'PARCEL_TRANSITION_REFUSED',} as const;
export class ParcelUnpaid extends DomainRefusal { readonly code = ShippingCodes.ParcelUnpaid;
static forParcel(parcelId: string) { return ParcelUnpaid.refusal(`Parcel ${parcelId} is not paid yet.`, { parcelId }); }}
export class ParcelTransitionRefused extends DomainRefusal { readonly code = ShippingCodes.ParcelTransitionRefused;
static forParcel(parcelId: string, from: ParcelStatus, transition: string) { return ParcelTransitionRefused.refusal(`Parcel ${parcelId} cannot ${transition} once ${from}.`, { parcelId, from, transition, }); }}
// What the transitions are judged with: the aggregate hands it to `next`.interface ParcelMoment { readonly parcelId: string; readonly paid: boolean;}
// domain/state-machines/parcel.state-machine.tsexport const parcelLifecycle = defineStateMachine({ states: Object.values(ParcelStatus), initial: [ParcelStatus.Registered], transitions: { ship: { from: [ParcelStatus.Registered], to: ParcelStatus.Shipped, guard: ({ parcelId, paid }: ParcelMoment) => (paid ? undefined : ParcelUnpaid.forParcel(parcelId)), }, reroute: { from: [ParcelStatus.Shipped] }, deliver: { from: [ParcelStatus.Shipped], to: ParcelStatus.Delivered }, }, refused: ({ from, transition }, { parcelId }: ParcelMoment) => ParcelTransitionRefused.forParcel(parcelId, from, transition),});
// domain/aggregates/parcel.aggregate.ts: the aggregate asks the machine, never tests its status by handexport class Parcel extends AggregateRoot { private status: ParcelStatus = parcelLifecycle.start(ParcelStatus.Registered);
private constructor( id: string, private readonly paid: boolean, ) { super(id); }
static register(id: string, paid: boolean): Parcel { return new Parcel(id, paid); }
ship(): void { this.status = parcelLifecycle.next(this.status, 'ship', this.moment()); }
deliver(): void { this.status = parcelLifecycle.next(this.status, 'deliver', this.moment()); }
private moment(): ParcelMoment { return { parcelId: this.id, paid: this.paid }; }}
Parcel.register('p-1', false).ship(); // throws PARCEL_UNPAID: the guard refusedParcel.register('p-2', true).deliver(); // throws PARCEL_TRANSITION_REFUSED: registered cannot deliver
parcelLifecycle.allowedFrom(ParcelStatus.Shipped); // ['reroute', 'deliver']parcelLifecycle.isFinal(ParcelStatus.Delivered); // trueThe lifecycle of an aggregate, in domain/state-machines/<aggregate>.state-machine.ts.
next(from, transition, context) answers the next status or throws: the refusal refused builds
from a static factory for a transition the state does not allow, or the refusal of a guard.
start(state) checks an initial state, can(...) answers without throwing, allowedFrom(state)
and isFinal(state) read the graph, describe() gives it as data and
mermaidOfStateMachine(description) as a Mermaid diagram. A transition without to keeps the
state. A declaration naming an unknown state throws InvalidStateMachineError when the file
loads. Why, and the rule that holds the aggregate to it:
State machines.
Domain events and the unit of work
Section titled “Domain events and the unit of work”An effect of a domain event exists only if the state change that recorded it is committed.
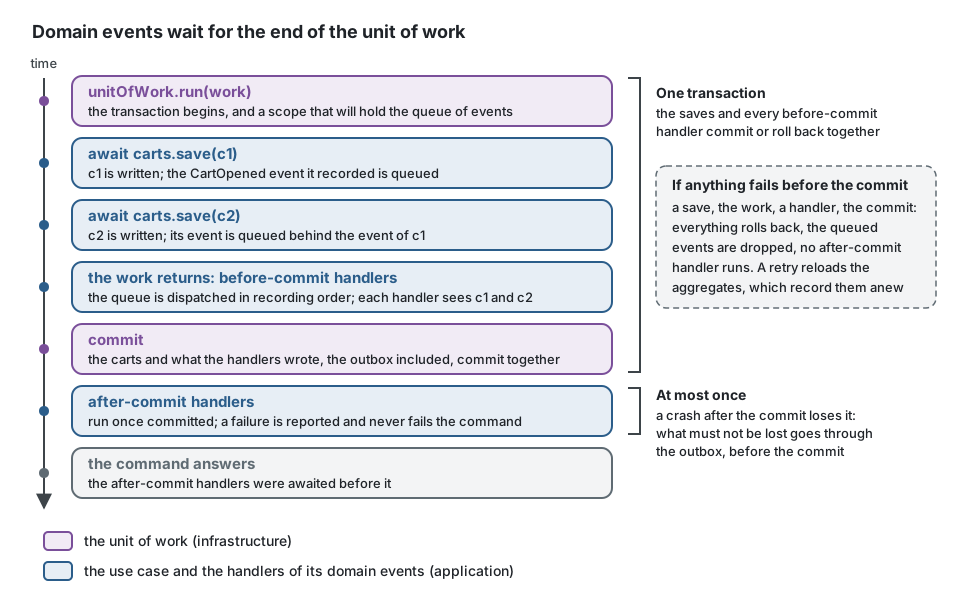
An aggregate records its events; nothing in a use case hands them over. A repository wrapped
by dispatchingOnSave(repository, () => dispatcher) pulls them itself, once a method that was
handed the aggregate has resolved:
const orders = dispatchingOnSave(new KnexOrderRepository(db), () => dispatcher);
await unitOfWork.run(async () => {  await orders.save(order);            // persisted; the events `order` recorded are queued  await orders.saveAll([first, second]);  await orders.remove(order);          // a "deleted" event is queued with the removal});                                    // dispatched here, in recording order, before the commit
kernelModule() of @ddd-ts-kit/di applies it to every binding of kind repository, so an
application never writes this line; the table of what it guarantees (ordering, re-entrancy,
failures, wrapper order) is in the README of that package. In short:
- Inside a unit of work a save only queues, in recording order across all the saves. Once the work has returned, still inside the transaction, the queue is dispatched: every handler sees every save. Events recorded by handlers that save wait behind the others, in the same order, without recursion. Then the transaction commits.
- The events are pulled only when the call succeeded. The first
before-commithandler that fails rejects the unit of work; so does the work, a later save or the commit. The queued events are then dropped and never put back on the aggregates: a retry reloads them. - Outside any unit of work the save dispatches before it resolves,
before-commithandlers thenafter-commitones.
The whole timeline, with the doubles of the kernel and nothing else, as a spec would set it up:
import { NamedDomainEvent,  AggregateRoot,  InMemoryDomainEventDispatcher,  InMemoryUnitOfWork,  dispatchingOnSave,  type DomainEvent,} from '@ddd-ts-kit/kernel';
class CartOpened extends NamedDomainEvent('shop.cart.opened') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,  ) {    super();  }}
class Cart extends AggregateRoot {  static open(id: string, now: Date): Cart {    const cart = new Cart(id);
    cart.record(new CartOpened(id, now));
    return cart;  }}
class InMemoryCarts {  readonly saved: string[] = [];
  async save(cart: Cart): Promise<void> {    this.saved.push(cart.id);  }}
const journal: string[] = [];const dispatcher = new InMemoryDomainEventDispatcher();const carts = dispatchingOnSave(new InMemoryCarts(), () => dispatcher);const unitOfWork = new InMemoryUnitOfWork();
dispatcher.on(CartOpened.eventName, async (event) => {  journal.push(`before-commit ${event.aggregateId} sees ${carts.saved.join(' and ')}`);});dispatcher.on(CartOpened.eventName, async (event) => void journal.push(`after-commit ${event.aggregateId}`), {  phase: 'after-commit',});
const now = new Date('2026-01-05T09:00:00Z');
await unitOfWork.run(async () => {  await carts.save(Cart.open('c1', now));  journal.push('saved c1');  await carts.save(Cart.open('c2', now));  journal.push('saved c2');});
// journal: saved c1, saved c2,//          before-commit c1 sees c1 and c2, before-commit c2 sees c1 and c2,//          after-commit c1, after-commit c2
pullEvents() stays public for this wrapper and for the specs of an aggregate; a use case and
a repository adapter never call it. An aggregate is recognised by what it does (it has
pullEvents), so a context compiled against another copy of the kernel is followed too.
Two phases
Section titled “Two phases”| Phase | Declared | Runs | A failure |
|---|---|---|---|
before-commit (default) |
dispatcher.on(name, callback) |
at the end of the unit of work, inside its transaction | fails the command; everything rolls back |
after-commit |
dispatcher.on(name, callback, { phase: 'after-commit' }) |
once the transaction has committed, never when it rolled back, in dispatch order, awaited before the command answers | never fails the command: reported, and the other handlers still run |
With declarations the phase is an option of the decorator:
@DomainEventHandler(OrderPaid, { phase: 'after-commit' }).
The after-commit phase is at most once: a crash between the commit and the run loses it. What
must not be lost goes through the outbox as an integration event. A before-commit handler
may only have effects the transaction covers, because the commit can still fail after it ran
(domain-events/transactional-before-commit).
DomainEventDispatcher.dispatch(events, phase?) runs the handlers of one phase,
before-commit by default. InMemoryDomainEventDispatcher(failed?) is told each failure of an
after-commit handler and keeps the last hundred in afterCommitFailures, for specs.
reportAfterCommitFailures({ reporter, logger, scope? }) is the failed to give it wherever a
logger and an error reporter exist: one Logger.error entry ("A domain event handler failed
after the commit", with domainEvent, errorType, errorCode) and the error handed to the
ErrorReporter under the operation after-commit <event name>.
An after-commit handler that hands an aggregate to a wrapped repository (save, saveAll,
remove(aggregate)) is refused before the write with SaveAfterCommitError: the unit of work
is over. It sends a command through the CommandBus, which opens a unit of work of its own.
unitOfWorkStage() answers 'outside', 'open', 'before-commit' or 'after-commit'.
The spec of a reaction
Section titled “The spec of a reaction”That a before-commit handler runs inside the transaction and an after-commit one once it has
committed is a guarantee of the kernel, proven once by its own suite: the spec of a reaction
does not prove it again. It gives the reaction the fact and asserts what the reaction sent. An
event handler, an integration event handler and a controller send commands through the
CommandBus they receive: RecordingCommandBus of @ddd-ts-kit/kernel/testing keeps each one
it is handed, in order, in executed, and answers what the spec told it with
answering(type, answer) (an identifier, or a refusal the function throws), for the commands of
type and of its subclasses, nothing otherwise.
No handler runs: what the command does is the spec of its own handler. RecordingQueryBus does
the same for queries. The specs ddd-ts-kit generate writes for these roles start from them:
import { Command, type CommandBus, type DomainEvent } from '@ddd-ts-kit/kernel';import { RecordingCommandBus } from '@ddd-ts-kit/kernel/testing';
class ScheduleReminderCommand extends Command {  constructor(readonly invoiceId: string) {    super();  }}
/** When an invoice is issued, a reminder is scheduled for it. */class InvoiceIssuedEventHandler {  constructor(private readonly commands: CommandBus) {}
  async handle(event: DomainEvent): Promise<void> {    await this.commands.execute(new ScheduleReminderCommand(event.aggregateId));  }}
const issued: DomainEvent = { name: 'billing.invoice.issued', aggregateId: 'invoice-1', occurredAt: new Date(0) };const commands = new RecordingCommandBus();
await new InvoiceIssuedEventHandler(commands).handle(issued);
export const sent = commands.executed; // [new ScheduleReminderCommand('invoice-1')]
A unit of work of your own
Section titled “A unit of work of your own”The queue lives in an AsyncLocalStorage scope opened by withinUnitOfWork(work, transaction).
InMemoryUnitOfWork and the units of work of the ORM packages are built on it, so a run
called directly (a consumer, a script) has the timing of a command. unitOfWorkMiddleware
calls it too: a command is covered even with a UnitOfWork that does not. A nested run, or a
command sent from inside a unit of work, joins the scope in progress: one dispatch, at the end
of the outermost, and the after-commit phase after the outermost commit. Two concurrent
commands never share a scope.
A UnitOfWork written in a project builds run on it. transaction begins, calls what it is
given, commits when it resolved and rolls back when it rejected:
run<T>(work: () => Promise<T>): Promise<T> {  return withinUnitOfWork(work, (scoped) => {    if (this.current.getStore() !== undefined) { // nested: join the transaction      return scoped();    }
    return this.database.transaction((transaction) => this.current.run(transaction, scoped));  });}
unitOfWorkContract of @ddd-ts-kit/testing/contracts fails an adapter that forgot.
Declarations
Section titled “Declarations”A class says what it is, and the composition root is assembled from what the classes say.
@ddd-ts-kit/kernel/declarations holds the decorators that record it. They are pure metadata:
a declaration instantiates nothing, resolves nothing, reads no configuration and knows no
container. That is why they live here, where the application layer may import them. Turning
declarations into bindings is the job of @ddd-ts-kit/di (contextModule,
discoverContext), and of nothing else.
import { Repository } from '@ddd-ts-kit/kernel';import type { Order } from '@/contexts/ordering/domain/aggregates/order.aggregate';
export abstract class OrderRepository extends Repository<Order> { abstract findOpenOf(customerId: string): Promise<readonly Order[]>;}import { Clock } from '@ddd-ts-kit/kernel';import { CommandHandler } from '@ddd-ts-kit/kernel/declarations';import { OrderRepository } from '@/contexts/ordering/domain/repositories/order.repository';import { PlaceOrder } from '@/contexts/ordering/application/commands/place-order/place-order.command';
@CommandHandler(PlaceOrder)export class PlaceOrderHandler implements CommandHandler<PlaceOrder> { constructor( private readonly orders: OrderRepository, private readonly clock: Clock, ) {}
async execute(command: PlaceOrder): Promise<string> { /* ... */ }}import { Clock, ExecutionScope } from '@ddd-ts-kit/kernel';import { Repository } from '@ddd-ts-kit/kernel/declarations';import { Database } from '@/contexts/ordering/application/ports/database.port';import { OrderRepository } from '@/contexts/ordering/domain/repositories/order.repository';
@Repository(OrderRepository)export class KnexOrderRepository implements OrderRepository { constructor( private readonly database: Database, private readonly scope: ExecutionScope, private readonly clock: Clock, ) {}
/* findById, save, findOpenOf */}Repository is two things under one name, each in its entry: the abstract class a repository
port extends (main entry, imported by the port) and the decorator of its adapter (this entry,
imported by the adapter). No file needs both.
Ports and tokens
Section titled “Ports and tokens”A port is an abstract class, and the class is the injection token. The class names the
dependency and carries its type: a constructor parameter typed by it names what is injected, and
app.resolve(Clock) answers a Clock. Token<T> is that type: abstract new (...args: never) => T.
There is no token constant and no token file. A port has one place, one abstract class per file:
| Port | File |
|---|---|
| a repository of the domain | domain/repositories/*.repository.ts |
| any other port, and a value class | application/ports/*.port.ts |
export abstract class PaymentGateway { abstract charge(orderId: string, amount: Money): Promise<PaymentReceipt>;}The port rule. A port has abstract members only: no body, no constructor parameter, no
private or protected member. A port may extend another port. An adapter implements its port
and never extends it. The type stays structural, so a fake, an in-memory class or a plain
object literal stands for a port without ceremony.
import { Clock } from '@ddd-ts-kit/kernel';import { Adapter } from '@ddd-ts-kit/kernel/declarations';
interface Money {  readonly amount: string;  readonly currency: string;}
interface PaymentReceipt {  readonly reference: string;  readonly paidAt: Date;}
// application/ports/payment-gateway.port.ts: abstract members onlyexport abstract class PaymentGateway {  abstract charge(orderId: string, amount: Money): Promise<PaymentReceipt>;}
// infrastructure/external/http-payment-gateway.adapter.ts: implements its port, never extends it@Adapter(PaymentGateway, { kind: 'external' })export class HttpPaymentGateway implements PaymentGateway {  constructor(private readonly clock: Clock) {}
  async charge(orderId: string, amount: Money): Promise<PaymentReceipt> {    // the call to the payment provider goes here    return { reference: `${orderId}:${amount.amount}:${amount.currency}`, paidAt: this.clock.now() };  }}
// test/fakes: a plain object is a PaymentGateway, since the type is structuralexport const acceptingGateway: PaymentGateway = {  charge: async (orderId) => ({ reference: `fake-${orderId}`, paidAt: new Date('2026-01-05T09:00:00Z') }),};
Repository<A, Id> is the contract every repository shares (findById, save), as an
abstract class. The repository port of an aggregate extends it and adds its own finders, as
OrderRepository above; the adapter implements that port.
A value that is no port (a configuration object, a database handle, a list, a primitive)
is typed by an abstract class too, with abstract readonly properties, and a plain object is
bound to it with toValue of @ddd-ts-kit/di:
export abstract class Database {  abstract readonly client: Knex;}
// contexts/ordering/application/ports/payment-settings.port.tsexport abstract class PaymentSettings {  abstract readonly apiKey: string;}
// composition rootbuilder.bind(Database).toValue({ client: knex });builder.bind(PaymentSettings).toValue({ apiKey: configuration.paymentApiKey });
That is the one way: no string token, no symbol token, no helper. Instead of a token next to the type, two names to keep in step:
export const PAYMENT_GATEWAY = Symbol('PaymentGateway');
constructor(@Inject(PAYMENT_GATEWAY) private readonly payments: PaymentGateway) {}
write the type alone, which is the token:
constructor(private readonly payments: PaymentGateway) {}Identity across copies. A class is its own identity, and two copies of a package loaded in
one process (a duplicated install, a bundle next to node_modules) hold two classes. A port
that declares static readonly tokenKey = '<package>.<Port>' is known by that key instead,
the same in every copy: tokenIdentity(port) answers what a container keys by, and
describeToken(port) its name. Every injectable port of the kernel carries one (kernel.Clock,
kernel.CommandBus, ...); Repository<A, Id> is a base to extend, never a token, and carries
none.
export abstract class PaymentGateway {  static readonly tokenKey = 'ordering.PaymentGateway';
  abstract charge(orderId: string, amount: Money): Promise<PaymentReceipt>;}
The limit, plainly: a port of your own that declares no tokenKey and is loaded twice is
two tokens. What is bound under one copy is not found under the other. An application
compiled as one program never meets it; a port published in a package that may be installed
twice, or bundled next to node_modules, declares a tokenKey. The key is the identity: two
ports that declare the same key are the same token, so prefix it with the package or the
context. It is declared, never inherited: a port that extends a keyed port declares its own.
When to declare one: only for a port that one process may load from two copies of its package. A port of an application, compiled once into one program, never declares a key: the class is identity enough, and a key would only be a name to keep unique by hand.
A port that extends a port of the kernel declares its key as any other does, without
override: the kernel ports carry theirs as an own property that is not a declared member
(kernel.<ClassName>, set in a static block), so nothing is overridden.
export abstract class OrderRepository extends Repository<Order> {  static readonly tokenKey = 'ordering.OrderRepository';}
export abstract class BusinessClock extends Clock {  static readonly tokenKey = 'ordering.BusinessClock';}
What a class depends on is said by its constructor. A decorator lists nothing: each
constructor parameter is typed by one class, its token, and ddd-ts-kit docs reads the
signatures from the sources into the generated file of the context, which registers them with
injected:
import { AggregateRoot, Clock, Command, Repository } from '@ddd-ts-kit/kernel';import { CommandHandler, injected, injectedDependencies } from '@ddd-ts-kit/kernel/declarations';
declare class Order extends AggregateRoot {  static place(id: string, customerId: string, now: Date): Order;}
export abstract class OrderRepository extends Repository<Order> {}
export class PlaceOrder extends Command<string> {  constructor(    readonly orderId: string,    readonly customerId: string,  ) {    super();  }}
@CommandHandler(PlaceOrder)export class PlaceOrderHandler implements CommandHandler<PlaceOrder> {  constructor(    private readonly orders: OrderRepository,    private readonly clock: Clock,  ) {}
  async execute(command: PlaceOrder): Promise<string> {    const order = Order.place(command.orderId, command.customerId, this.clock.now());
    await this.orders.save(order);
    return order.id;  }}
// contexts/ordering/ordering.declarations.ts, generatedinjected(PlaceOrderHandler, [OrderRepository, Clock]);
injectedDependencies(PlaceOrderHandler); // [OrderRepository, Clock]: what a container builds the handler with
injected(Class, [Tokens]) records one token per constructor parameter, in order, in a
registry shared by every copy of the kernel a process loads; injectedDependencies(Class)
reads it back, and a container (@ddd-ts-kit/di) is what uses it. Nothing here reads
design:paramtypes: that metadata exists only with legacy decorators compiled by tsc or
swc, not with standard decorators nor under tsx or esbuild. A decorator still accepts a list
as its last argument, @CommandHandler(PlaceOrder, [OrderRepository, Clock]): the form 0.1
projects wrote. A declaration then carries it in dependencies, which is undefined when
the constructor is the statement, and a container gives it precedence.
What the compiler refuses, in both decorator modes:
- a list, of
injectedor of a decorator, that does not name one port per constructor parameter, each of the type of its parameter, in order: a missing or extra entry, a wrong type, a wrong order;injected(Class)without a list for a constructor that takes something; - a class that does not implement the port it is declared the adapter of, and an abstract class;
- a concrete class named where its port is expected:
[InMemoryOrderRepository, Clock]for a parameter typedOrderRepository. A list names ports, never what implements them.
What changed with the list becoming optional: a decorator without a list accepts any constructor, so the compiler no longer tells, at the decorator, a class whose list was forgotten. It does not have to: the list is derived from the constructor, checked where it is generated, and a class left without one is refused by name when the application is composed.
What is refused when the file loads, with a DeclarationError from @Repository,
@Gateway and @Adapter, because the compiler cannot see it:
- a port with a body:
TalkativePharmacy implements greet: a port is an abstract class with abstract members only. A member inherited from a parent port counts; - an adapter that extends its port:
CornerPharmacy extends Pharmacy: an adapter implements its port, it never extends it.
portDefect(port, implementation) is that check, answering the reason or undefined; a
container applies it to a binding made by hand. A class bound to itself is no port and is
left alone.
The decorators
Section titled “The decorators”| Decorator | On | Example |
|---|---|---|
Requires(permission, options?) |
a command or query that carries its actor | @Requires(permissions['visit.schedule'], { resource: (c: ScheduleVisit) => ({ type: 'patient', id: c.patientId }), audited: ['startsAt'] }) |
Public(options?) |
a command or query anybody may send | @Public() |
CommandHandler(Message) |
the one handler of a command | @CommandHandler(PlaceOrder) |
QueryHandler(Message) |
the one handler of a query | @QueryHandler(GetOrder) |
IntegrationEventHandler(definition, { consumer, actorOf? }) |
the handler of an integration event of another context | @IntegrationEventHandler(OrderPlaced, { consumer: 'billing.invoice-on-order-placed' }) |
DomainEventHandler(Event) |
a handler of a domain event of its own context | @DomainEventHandler(OrderPaid), attached under the name the event class declares once in static readonly eventName |
Scheduled(name, schedule and options) |
a job run by time, which triggers use cases | @Scheduled('billing.send-reminders', { cron: '0 7 * * 1-5', timeZone: 'Europe/Paris' }) |
Projection(name) with On(definition) on its methods |
a projector: the class that keeps one read model up to date | @Projection('scheduling.appointment-list'), @On(PaymentCaptured) |
Repository(Port, options?) |
the adapter of a repository of the domain | @Repository(OrderRepository) |
Gateway(Port, options?) |
the adapter of a port that calls another context | @Gateway(StockGateway) |
Adapter(Port, options?) |
the adapter of any other port | @Adapter(PaymentGateway, { kind: 'external' }) |
Policy(permission, { name }) |
a rule that needs the loaded element | @Policy(permissions['invoice.void'], { name: 'billing.only-issuer-voids' }) |
- Access is said on the message. A command extends
CommandorAuthorizedCommand, a queryQueryorAuthorizedQuery: the base class already says which of the two it is, so the decorator only says who may send it.@Requiresis refused by the compiler on a message without an actor.auditedlists the fields an audit trail may record (a name, or{ field, masked: true }), as plain data; the compiler checks that the message has them. - Dependencies are said by the constructor, as above. A list written as the last argument of a decorator, the form of 0.1, names one port per parameter and is checked against the constructor. There is no parameter decorator and no reflection.
- The role is checked too: a handler of another message or of another result, an event
handler of another payload, a job without
runare refused by the compiler. - Options of a repository, a gateway and an adapter:
transient: true(one instance per resolution instead of one per application),replaces: true(takes the place of a binding made earlier, such as a default of the kernel module),aspects: [...](wrappers, the first outermost); an adapter also takeskind: 'external' | 'publisher'. - One name for the decorator and for the shape of its class:
CommandHandler,QueryHandler,IntegrationEventHandlerandDomainEventHandlerare each a decorator and a type, so one import serves@IntegrationEventHandler(OrderPlaced, ...)andimplements IntegrationEventHandler<OrderPlacedPayload>. A job implementsScheduledJob. - Names are written, not derived: the consumer name, the policy name, the job name and the
name of the domain event survive the renaming of a class, and the empty string is refused.
The name of a domain event is written once on its class,
extends NamedDomainEvent('..')orstatic readonly eventName: its handlers and projections read it there (NamedDomainEventType), and a class without it is refused by the compiler. - A declared class is its own token:
@ddd-ts-kit/dibinds a handler, a job or a policy under its class.
declarationOf(Class) answers what a class declared, as frozen plain data, or undefined;
listDeclarations() lists the declared classes the process still holds, for diagnostics. A
class plays one role: a second declaration on the same class throws DeclarationError when
the file loads, and so does @Requires or @Public on what is neither a Command nor a
Query, and @Scheduled with a name or a schedule that cannot be read. A declaration is not
inherited by a subclass.
The names of the main entry differ on purpose: there, IntegrationEventCallback and
DomainEventCallback are the plain functions given to subscribe and to on, and
CommandHandler and QueryHandler are the interfaces alone.
Where it is stored. In one registry per process, reached through Symbol.for, with the
classes held weakly. A context compiled against one copy of the kernel is therefore read by a
container holding another (a duplicated install, a bundle next to node_modules), and a module
reloaded by a watcher leaves no trace of its former classes. Symbol.metadata is not used:
Node 24 does not define it, and the legacy decorator mode has no context to carry it.
Not in the domain. domain/ carries no decorator: aggregates, entities, value objects,
domain events, domain services and repository ports declare nothing. A domain event is
named by the handler that reacts to it, not by itself. @UseCase does not exist: the
canonical tree has one handler per command and no application service to bind.
Integration events and their subscribers
Section titled “Integration events and their subscribers”IntegrationEventPublisher is what use cases publish through, IntegrationEventSubscriber
what handlers are subscribed on, and EventBus both at once. EventSubscribers gives each
bounded context its subscriber: forContext(name) answers an IntegrationEventSubscriber.
One bus serves every context by default; a broker gives each consuming context its own, so
that a context extracted into its own process keeps its queues. @ddd-ts-kit/di subscribes
the integration event handlers of a context on EventSubscribers.forContext(<context name>).
Scheduled
Section titled “Scheduled”@Scheduled('billing.send-reminders', { cron: '0 7 * * 1-5', timeZone: 'Europe/Paris' })export class SendRemindersJob implements ScheduledJob { constructor(private readonly commands: CommandBus) {}
async run(execution: JobExecution): Promise<void> { await this.commands.execute(new SendReminders(systemActor('billing.send-reminders'), execution.scheduledAt)); }}A job lives in application/scheduling/, in a *.job.ts file, and only triggers use cases:
it receives buses and ports by its constructor and typically sends one command. The second
argument is the schedule and, next to it, the options:
| Key | Default | |
|---|---|---|
every |
an interval, as milliseconds or '30s', '15m', '2h', '1d', aligned on the Unix epoch |
|
cron, timeZone |
timeZone: 'UTC' |
the five standard fields or a shorthand (@hourly, @daily, @weekly, @monthly, @yearly), on the clocks of an IANA zone |
overlap |
'skip' |
an occurrence that comes while the previous run is in progress is skipped, or 'queue'd behind it |
missed |
'skip' |
occurrences that passed without being reached are dropped, or the latest is 'run-once' |
timeoutMs |
none | the signal of a longer run is aborted |
jitterMs |
0 |
a random delay before each run |
enabled |
true |
meant to be overridden by configuration where the job is wired |
singleInstance |
true |
the scheduler takes the Lock of each occurrence |
Exactly one of every and cron is written, and the compiler refuses the rest. The name is
<context>.<job-name> in lower case, unique in the application. JobExecution is what run
receives: scheduledAt, startedAt, attempt and an abort signal. What the schedules mean
across a change of clocks, what one instance among several guarantees and how a job is tested
are in the README of @ddd-ts-kit/scheduling.
Background
Section titled “Background”@Background({ maxAttempts: 3, timeout: '10m' })export class CompileStatementsBackgroundJob implements BackgroundJob<CompileStatementsPayload> { static readonly jobName = 'billing.compile-statements';
// the schema of its payload, `zodSchema(z.object({ month: z.string() }))` or any validation library static readonly payload = compileStatementsPayload;
constructor(private readonly commands: CommandBus) {}
async run(payload: CompileStatementsPayload, execution: BackgroundJobExecution): Promise<void> { await this.commands.execute(new CompileStatements(execution.jobId, payload.month)); }}A background job is named by its static jobName, which is how a use case enqueues it
(jobs.enqueue(CompileStatementsBackgroundJob, { month }), the payload typed by run). Its static
payload is the schema of that payload, a BackgroundJobPayloadSchema (parse(input) answering a
Result, which the Schema of @ddd-ts-kit/validation is, whatever library it adapts): the worker
reads the stored payload with it before each run and never runs one it refuses
(INVALID_JOB_PAYLOAD); the timeout job of a process uses processTimeoutDuePayload. The decorator
takes the options, all optional: maxAttempts (5), backoff ({ baseMs: 1000, factor: 2, maxMs: 300000 }), timeout and lease (30 s), as milliseconds or '10m'. A name that is not
<context>.<job-name>, a class without a static payload and options it cannot read throw a
DeclarationError when the file loads. BackgroundJobExecution is what run receives: jobId, attempt, enqueuedAt,
startedAt, the checkpoint an earlier attempt saved, an abort signal, saveCheckpoint(value)
and reportProgress({ done, total }).
Decorator modes
Section titled “Decorator modes”Every decorator of this entry works under both decorator modes of TypeScript, and the same
source line type-checks under both, checks of the role and of a dependency list included.
Neither needs emitDecoratorMetadata, and what a constructor takes is known in both the same
way: read from the source, registered by injected.
| Stack | tsconfig.json |
|---|---|
| class-validator, NestJS, TypeORM entities, any library with legacy decorators | "experimentalDecorators": true |
| anything else | leave experimentalDecorators unset: standard (TC39) decorators need no flag |
One program has one mode, which is why the kit follows the project instead of choosing. A
class decorator receives the class first in both modes; the standard call adds a context,
which these decorators do not read. Nothing else differs: no emitDecoratorMetadata, no
reflect-metadata, no parameter decorator in either mode. Both are compiled by TypeScript 5,
6 and the native TypeScript 7. Under Vitest, legacy decorators need nothing; standard ones
need decorators() of @ddd-ts-kit/testing/vitest.
Standard interfaces
Section titled “Standard interfaces”Standard means that every project built with the kit has the same shape under the same name, so an adapter, a middleware or a dashboard written once fits them all. Extensible means that a project adds its own fields without forking the type (see "How to extend").
Session
Section titled “Session”The authenticated session of an actor, as plain data.
| Field | |
|---|---|
id, actor, issuedAt, expiresAt? |
who, since when, until when |
authenticationMethod |
none, password, sso, token, api-key, service, or a string of the project |
authenticationStrength? |
{ mfa?, assuranceLevel? } |
impersonatedBy? |
id of the support actor acting as actor; logFieldsOf carries it to every log line |
locale?, timeZone?, client? |
BCP 47 tag, IANA zone, { ip?, userAgent? } as opaque strings |
scopes? |
what the credential allows whoever presents it (the OAuth 2.0 scope): a limit on the client, never what the actor may do |
extensions |
the fields of the project |
hasScope(session, scope) reads the scopes; a project names its scope vocabulary once by
declaration merging of SessionScopes (interface SessionScopes { readonly 'invoices:read': true }),
and SessionScope, the type a guard takes, is then that vocabulary instead of any string.
isExpired(session, clock.now()), isImpersonated(session), anonymousSession(),
systemSession(name, issuedAt?), and isSession(value), the structural guard a boundary uses on
what it received as a principal.
ExecutionContext and ExecutionScope
Section titled “ExecutionContext and ExecutionScope”What every unit of work carries, whatever started it: correlationId, causationId?, actor,
session?, tenantId?, elevation? (platform staff reading over tenants, see "Tenancy"),
locale?, deadline?, scheduledAt? (for a scheduled job, the instant it was due), origin
(http, event, schedule, queue for a background job, cli, or a string of the project)
and extensions. executionContext(init) builds one and takes the tenant of the actor;
withActor(context, actor) is the same work seen as another actor.
ExecutionScope (current(), require(), run(context, work)) gives the context of the work
in progress to code that is not handed it. The boundary sets it once:
// presentation or platform: one run per request, consumed event, jobscope.run(executionContext({ correlationId, actor, session, origin: 'http' }), () => handle(request));// infrastructure: a repository adapterconst row = { ...toRow(order), ...stampCreation(scope, clock), ...tenantScopeOf(scope) };Both ends, with the implementation that follows the asynchronous call chain:
import {  AsyncLocalStorageExecutionScope,  FixedClock,  executionContext,  stampCreation,  tenantScopeOf,  type Actor,} from '@ddd-ts-kit/kernel';
const scope = new AsyncLocalStorageExecutionScope();const clock = new FixedClock(new Date('2026-01-05T09:00:00Z'));const actor: Actor = { id: 'u-42', type: 'user', tenantId: 'acme', roles: ['agent'], attributes: {} };
// the boundary: set once for the requestawait scope.run(executionContext({ correlationId: 'req-7f3a', actor, origin: 'http' }), async () => {  // ...the command goes through the bus to its handler, which saves; in the repository adapter:  const row = { id: 'o-1', ...stampCreation(scope, clock), ...tenantScopeOf(scope) };  // { id: 'o-1', createdAt, createdBy: 'u-42', updatedAt, updatedBy: 'u-42', tenantId: 'acme' }  return row;});
Use cases and the domain never read the scope: they receive the actor, and anything else they
need, in the command or query (authz/actor-explicit). The scope is for loggers, audit columns,
tenant scoping and outgoing headers. Instead of a handler that asks the scope who acts, a
dependency its signature hides:
const actor = this.scope.require().actor;write a command that carries its actor, the first argument of an AuthorizedCommand, and read
command.actor in the handler:
export class CancelOrder extends AuthorizedCommand { constructor(actor: Actor, readonly orderId: string) { super(actor); }}A consumed event opens its own context: executionContextOfEvent(event, { consumer }) has
origin event, the correlation of the event (its id when it names none), the event as
causationId, systemActor(consumer) as actor and the tenantId of the event, so the
consumer reads and writes in that tenant only; inEventScope(scope, { consumer }, handler)
wraps a handler with it. The standard envelope carries no actor, so that no personal data
travels by default: a project whose envelopes name one passes actorOf. On the way out,
scopedPublisher(publisher, scope) stamps the correlation and the tenant of the work in
progress on every event published without them, so everything one stimulus causes is found
again across processes and stays in its tenant.
ActorContext stays, unchanged. ScopedActorContext implements it on top of a scope: the
current actor is the actor of the current execution context, so the two cannot disagree.
AsyncLocalStorageExecutionScope follows the asynchronous call chain; FixedExecutionScope is
the test double, and follows a FixedActorContext when given one.
Logger
Section titled “Logger”debug, info, warn, error(message, fields?), child(fields), isLevelEnabled(level) and
flush(). LogFields spells the well-known keys once: correlationId, causationId,
context, actorId, tenantId, errorType, errorCode, durationMs; any other key is
accepted. A call never throws, whatever the fields: when they cannot be read or serialized the
entry is written with UNWRITABLE_FIELDS (logError: "unserializable fields") in their place.
The kernel never writes to the console: NoopLogger is the default, InMemoryLogger records
entries for a test, a JSON lines adapter is in @ddd-ts-kit/aspects, and @ddd-ts-kit/pino
and @ddd-ts-kit/winston are the adapters of those libraries. The domain and use cases do not
log.
Errors are log values. LogValue admits an Error, so
logger.error('payment failed', { error }) compiles as it is, and a project may name the key
once (interface LogFields { error?: Error }, see "How to extend"). An Error directly under a
key of the fields is written by every logger as describeError(error) describes it, an
ErrorDescription:
| Key | |
|---|---|
type |
the class name |
code |
the code of a DomainError; absent for any other error |
message |
the message |
stack |
the stack of this error alone |
cause |
the cause, described the same way when it is an Error: eight errors deep at most, so a chain that loops ends |
Deeper in the fields (inside a nested object or a list) an error is left to the serializer of
the adapter: pass it under a key. describeErrorFields(fields) is the copy of the fields a
logger writes; an adapter of your own calls it and is held to the result by loggerContract.
Messages of unexpected errors can be dropped. Every logger of the kit takes
scrubMessages: true (DescribeErrorOptions): the message of every error that is not a
DomainError becomes SCRUBBED_MESSAGE ([message removed]) and its stack loses its first
line, which repeats it. Messages of DomainErrors are written by the project and stay. It is
the option of the same name of @ddd-ts-kit/sentry, with the same rule and the same marker.
The default keeps the messages: a log that says [message removed] costs every investigation.
What the kit logs on its own never holds a message. The logged aspect,
loggingMiddleware and the job scheduler never hand an error to a logger: they write
errorType and errorCode, as identifyError(error) gives them, and the error itself goes to
the ErrorReporter. That holds whatever scrubMessages says. The full description is for the
error a project decides to log, in an adapter or a route; scrubbing is its opt-in for logs that
leave its hands.
isLevelEnabled(level) says whether an entry of that level would be written, for the
logger and its children. Ask it before building fields that cost; the kit does, in logged,
loggingMiddleware and the scheduler. NoopLogger answers false.
flush() resolves once every entry logged so far, through the logger or a child, was
handed to its destination, and never rejects. It is called once, when the process stops, after
the last entry: the application of @ddd-ts-kit/di calls it at the end of stop(). What is
logged after a flush is unspecified, and never throws: pino and StdoutLogger still write it,
winston, whose flush ends the logger, drops it. A second call resolves too.
InMemoryLogger takes { level?, fields?, base?, scrubMessages? } like a real adapter: a
threshold (default debug, every entry), fields read at each entry, fields added to every
entry. Its entries hold what a logger writes: an error passed as a field is recorded as its
description. CREDENTIAL_KEYS and REDACTED are the field names and the marker StdoutLogger
and the pino and winston adapters redact with, and isCredentialKey(name) the comparison they
share, without case; InMemoryLogger redacts nothing.
Metrics
Section titled “Metrics”counter(name).increment(labels?, by?), histogram(name).record(value, labels?),
gauge(name).set(value, labels?). Label values come from a small closed set, never an
identifier. NoopMetrics is the default; InMemoryMetrics records samples and answers
counterValue, histogramValues and gaugeValue for a subset of labels.
ErrorReporter
Section titled “ErrorReporter”report(error, report) and flush(timeoutMs): where unexpected failures go to be looked at,
an error tracker. report is synchronous: it queues and returns, never throws and never waits
for the tracker; flush waits for the queue before the process stops and never rejects.
ErrorReport is plain data, identifiers only: origin, operation, context,
correlationId, traceId, actorId, tenantId, errorCode, severity (fatal, error,
warning) and the project's extensions. NoopErrorReporter is the default,
InMemoryErrorReporter records reports for a test, and @ddd-ts-kit/sentry is the adapter
for Sentry and GlitchTip.
No handler, aggregate or repository calls it: they throw. What stands around them reports, each attached from outside:
| Capture point | Is | Reports |
|---|---|---|
| buses | errorReportingMiddleware(reporter, scope), first on the bus |
a command or query failing with anything but a DomainError; silent while an event is consumed |
| HTTP | reportHttpErrors(reporter) of @ddd-ts-kit/http, as onError |
every request answered 5xx |
| jobs | reportFailedRuns(reporter) of @ddd-ts-kit/scheduling, as onRun |
a run that failed with anything but a DomainError |
| events | new DeadLetterReports(reporter): onFailure on the hook of the provider, observing(subscriber) around its subscriber |
an event its provider gives up, never a retried delivery |
| process | reportProcessFailures(reporter) |
uncaughtException and unhandledRejection, then exit code 1 after a flush |
A DomainError is a business refusal and is never reported, unless HTTP answers it as a 5xx or
it buries an event (a warning). All of them go through reportOnce: the first capture point
that sees an error object reports it, the boundaries it crosses afterwards recognise it, so a
command failing inside a request or a job is one report, named after the command.
errorReportOf(error, source, executionContext?) builds the report: origin, correlation, actor
and tenant ids come from the execution context, never threaded by hand.
import { FixedClock, InMemoryCache, cacheKey } from '@ddd-ts-kit/kernel';
interface Quote {  readonly pair: string;  readonly rate: string;}
const quoteKey = (pair: string) => cacheKey<Quote>('quote', pair);
const clock = new FixedClock(new Date('2026-01-05T09:00:00Z'));const cache = new InMemoryCache(clock, { maxEntries: 500 });
await cache.set(quoteKey('EUR-USD'), { pair: 'EUR-USD', rate: '1.0842' }, { ttlMs: 60_000 });const hit: Quote | undefined = await cache.get(quoteKey('EUR-USD')); // the quote, typed by its key
clock.advance(60_000);await cache.get(quoteKey('EUR-USD')); // undefined: expired, by the clock
The key carries the type of its value. InMemoryCache(clock, { maxEntries? }) expires by the
Clock and is bounded. tenantCacheKey<Quote>(scope, 'quote', pair) is the same key confined to
the tenant of the work in progress: what one tenant cached is never served to another.
Purging the HTTP caches
Section titled “Purging the HTTP caches”Two ports, so that a use case can never purge before its commit:
| Port | Called by | Does |
|---|---|---|
CacheInvalidation.invalidate(tags) |
a before-commit handler of the domain event that changed what the answers show |
asks for the tags to be purged once the work commits; domain-events/transactional-before-commit allows it |
CachePurger.purge(tags) |
the relay of the outbox, never a use case (refused before the commit) | purges a shared cache now: InMemoryCachePurger here, Varnish and the CDNs in @ddd-ts-kit/http/purgers |
cacheTag('calendar', id) names a resource (calendar:c-1, the identifier percent-encoded),
cacheTag('calendar') every resource of a kind; the routes of @ddd-ts-kit/http tag their
answers with the same function. PublishedCacheInvalidation({ publisher, ids, clock, scope, perTenant? }),
what kernelModule() of @ddd-ts-kit/di binds, publishes one CachePurgeRequest on the
publisher, the tags under the tenant of the work (tenantCacheTags) when perTenant is set, as
a multi-tenant application whose answers are tagged per tenant sets it (work that names no tenant
is then refused with NoCurrentTenantError: its purge would meet no answer): behind an outbox it
is a row of the transaction, gone with a rollback, kept across a crash after the commit.
new PurgingPublisher(purger, broker) is what the relay publishes through: the purge requests
go to the purger, the other events to the broker, and a failed purge throws so that the relay
retries it. new RepeatedCachePurger(purger, { againAfterMs, onFailure? }) purges, then the same
tags once more againAfterMs later, for a read that loaded the previous state before the commit
and reached the cache after the first purge; the second purge is best effort, reported to
onFailure. InMemoryCacheInvalidation remembers the tags asked for (invalidated), for specs.
import type { Lock } from '@ddd-ts-kit/kernel';
declare function exportEverything(): Promise<void>;
export async function nightlyExport(lock: Lock): Promise<void> {  const handle = await lock.acquire('nightly-export', { ttlMs: 60_000, waitMs: 0 });
  if (handle === undefined) { // somebody else holds the key    return;  }
  try {    await exportEverything();  } finally {    await handle.release();  }}
A mutex between processes, to avoid doing the same work twice. acquire answers undefined
when the key is held, at once or after waitMs; the lock frees itself after ttlMs; the
fencingToken of a LockHandle grows with each acquisition of a key, so a resource that
remembers the highest one refuses a holder whose lock expired. It is an efficiency tool, never
the guard of an invariant: what must not happen twice is refused by a database constraint.
InMemoryLock(clock, { retryDelayMs?, sleep? }) excludes inside one process and expires by the
Clock: the fake, and enough for a single instance. The adapter between processes is in
@ddd-ts-kit/redis. acquiring(attempt, waitMs, waiting) is the retry loop an adapter shares.
FileStorage, StoredFile, FileScanner
Section titled “FileStorage, StoredFile, FileScanner”// The command wraps what the controller received: the bus stages it before the transaction opens.this.document = new FileUpload(received, 'appointment-documents');
// The handler, inside the unit of work:const { file, fileName } = command.document; // a StoredFile, staged and scannedappointment.attachDocument(unwrap(AttachedDocument.create(file, fileName, now)), now);await appointments.save(appointment);await staging.promoteOnCommit(file.key); // moved to its key with the commitFileStorage holds the content of files, never the database: put (a stream in, measured and
hashed, refused with FILE_TOO_LARGE beyond maxBytes, leaving nothing), get (a stream out),
stat, delete, copy, move, list(prefix), and short signed links, signedDownloadUrl and
signedUploadUrl (at most MAX_SIGNED_URL_SECONDS, one hour). No method takes or returns a
whole file. A key is checked by isFileKey (segments of letters, digits, ., - and _, none
starting with a dot) before anything is touched, and FileKeys generates it on the server:
TenantFileKeys(ids, clock, scope) writes tenants/<tenant>/<area>/<year>/<month>/<id>, the
tenant segment only when the work in progress names one (the tenant id as it is: the kernel
refuses any other than letters, digits, - and _, so two tenants never share a prefix). The links of
signedUploadUrl carry a maxBytes, which the storages the application serves enforce.
StoredFile is what an aggregate keeps: key, size, mediaType, checksum (sha256:<hex>),
never the provider. FileScanner is the hook of an antivirus or a content check, called on the
staged file before it is accepted; AcceptEveryFileScanner is the one of a project that has
none yet. FileError carries the refusals: FILE_TOO_LARGE, UNSUPPORTED_MEDIA_TYPE,
FILE_NOT_FOUND, INVALID_FILE_KEY, FILE_REJECTED, INVALID_FILE_URL_EXPIRY.
A write to the storage is not rolled back with a transaction. FileStaging(storage, scanner, reporter) gives the order that keeps both consistent, each step once:
stage(key, content, options)writes understaging/<key>and scans; a refused file is removed (FILE_REJECTED). A file from a client travels in its command as aFileUpload(theReceivedFileand the area of its key), staged byfileUploadsMiddleware(desk), a bus middleware placed after the permission and before the unit of work, so no transaction waits on an upload.upload.fileis the stagedStoredFile.promoteOnCommit(key)moves the file to its key as the last step of the unit of work (atCommit, aCommitStepofapplyandundo): a promotion that fails rolls the command back, and a transaction that rolls back after it returns the file tostaging/. A committed row never points intostaging/.deleteAfterCommit(key)deletes, once committed, a file the aggregate no longer references (afterCommit, at most once: a failure or a crash leaves an unreferenced file, reported).purge(olderThan)removes the staged files older than the instant, all orphans; the jobPurgeStagedFilesruns it (the platform registers it asfiles.purge-staged, every hour, for files staged a day ago or more).
For a large file the client uploads straight to the storage: uploadUrl(key, { expiresInSeconds, mediaType, accepted, maxBytes }) answers the link for the client and the pending grant
(PendingUpload: key, size cap, media types, and the text rule and contentRules given with
them) that the command records on the aggregate; it throws when an accepted type has no content
rule, since no file of it could be confirmed;
confirm(pending), called by a command that reads the grant back from the aggregate, never
from the client, checks what arrived against the cap and on its bytes (contentMatches), scans
it, and answers the StoredFile. No final key may start with staging/ (assertFinalKey).
FileInspection is the pass-through every connector streams through: it counts, hashes, and
with an expectation holds back the first bytes until they prove the declared media type
(acceptsMediaType, contentMatches: a PDF starts with %PDF-, office documents are zip
archives, text is UTF-8 without control characters, SVG and unknown binary formats never
match).
Each media type has a content rule (contentRuleOf): a signature (SIGNED_MEDIA_TYPES), text
(TEXT_MEDIA_TYPES), or the one the expectation states in contentRules for a type the kit
has none for, text or unchecked (the bytes are taken as they are); a rule stated for a
family (image/*) never reaches a type a browser runs (NAMED_ONLY_MEDIA_TYPES: SVG, HTML,
JavaScript), which is stated by its name. contentRuleDefects
lists, before any content arrives, the accepted types no content could prove and the stated
rules that do nothing: @ddd-ts-kit/http refuses a route on it, uploadUrl a link. The
expectation also says the text it takes (TextRule): utf-8, the default, or single-byte,
which also passes text in Windows-1252 or ISO-8859-1 (no NUL, no control character, no UTF-16
or UTF-32 byte order mark) and still refuses a binary file. The bytes are never decoded by the
kit: isUtf8(bytes) tells a reader which decoder to take.
Connectors: InMemoryFileStorage for the tests (keys() lists what it holds) and
LocalFileStorage({ directory, baseUrl, secret }) for development, both ServedFileStorage:
their signed links point at the application, which answers them with signedFileRoutes of
@ddd-ts-kit/http. The object store connector is @ddd-ts-kit/s3. Each passes
fileStorageContract of @ddd-ts-kit/testing/contracts. Background import and export (row by
row validation, an error report, resumption) is a design built on these ports and the job queue
(see "JobQueue"), not a feature of this version:
File import and export.
JobScheduler
Section titled “JobScheduler”abstract class JobScheduler { abstract register(job: JobDefinition): void; // { name, schedule, run, ...options } abstract start(): Promise<void>; abstract stop(): Promise<void>; // waits for the runs in progress, then aborts their signal abstract runNow(name: string): Promise<JobRun>; // for an operation or a test abstract describe(): readonly JobDescription[]; // name, schedule, enabled, running, nextRunAt, lastRun}What runs the declared jobs when they are due. It is not the Scheduler of
@ddd-ts-kit/aspects, which is a timer for retry and timeout: this one knows jobs, schedules
and instances. A JobRun is one occurrence and its outcome (succeeded, failed with the
code of the error and never its message, skipped-overlap, skipped-locked, missed). A job
that fails stops neither the scheduler nor the other jobs, and runNow answers failed
instead of rejecting: only an unknown name rejects (UnknownJobError), and a name registered
twice throws (DuplicateJobError). A succeeded run of a per-tenant job carries tenants, the
number of tenants it ran for: 0 means the tenant directory was empty and the job was never called.
A run happens inside ExecutionScope, in the context executionContextOfJob(name, { correlationId, scheduledAt, deadline?, tenantId? }) builds: origin schedule, systemActor(name), a correlation of its
own, and scheduledAt, the instant the run was due, which ExecutionContext carries for this
origin. A job is global by default and runs in no tenant; tenancy: 'per-tenant' makes the
scheduler run it once per tenant of a TenantDirectory, each run in that tenant.
parseJobSchedule(schedule) validates a schedule and answers the form occurrences are
computed from (InvalidJobScheduleError, code INVALID_JOB_SCHEDULE, otherwise);
describeJobSchedule(schedule) is its text; jobPolicy(options) validates the options and
fills in the defaults. The kernel holds no scheduler: the in-process one, the computation of
occurrences and the manual one for tests are @ddd-ts-kit/scheduling, and the contract of the
port is jobSchedulerContract of @ddd-ts-kit/testing/contracts.
JobQueue
Section titled “JobQueue”abstract class JobQueue { abstract enqueue<P>(job: BackgroundJobType<P>, payload: P, options?: EnqueueOptions): Promise<EnqueuedJob>; abstract cancel(id: string): Promise<boolean>; abstract find(id: string): Promise<QueuedJob | undefined>; // status, attempts, progress, last error code}Where a use case hands work to a worker. EnqueueOptions are delay or runAt, an
idempotencyKey (a job of the same name and key, enqueued for the same tenant and already kept,
is answered, duplicate: true) and a subject (the id of what the job works on, which find
answers next to the tenant: a query checks the job belongs to the element it was asked about).
QueuedJobStatus is the closed vocabulary of the statuses (waiting, running, succeeded,
cancelled, dead), to publish in a contract. Work done for a tenant finds and cancels the
jobs of that tenant only (an elevation, those of the tenants it names). Called inside a unit of
work, a job is added or cancelled with the business change: the stores of the ORM packages
write with the transaction, a store that cannot (Redis, memory) waits for the commit through
whenCommitted(write, failed?), the helper any such adapter uses. A run happens inside
ExecutionScope, in the context executionContextOfBackgroundJob({ jobId, enqueuedBy, deadline? })
builds: origin queue, the correlation, actor and tenant of the work that enqueued it
(EnqueuedBy), the job as the cause. backgroundJobPolicy(options) fills in the defaults and
retryDelayMs(policy, attempt) is the backoff. The queue, its worker and its stores are
@ddd-ts-kit/scheduling and the ORM packages; why and how:
Background jobs.
ProcessRunner and ProcessStore
Section titled “ProcessRunner and ProcessStore”abstract class ProcessRunner { abstract run<State>(process: ProcessType<State>, id: string, step: (current: State | undefined) => ProcessDecision<State> | undefined): Promise<void>; abstract timeout<State>(process: ProcessType<State>, due: ProcessTimeoutDue & { jobId: string }, step: (current: State) => ProcessDecision<State> | undefined): Promise<void>;}
abstract class ProcessStore { abstract load(name: string, id: string): Promise<StoredProcess | undefined>; abstract save(process: StoredProcess): Promise<void>; // ConcurrencyError unless version is the stored one plus 1}Process managers: a class of application/processes/ (ProcessManager<State>) with a static
processName, an optional static timeoutJob and a static isState guard; its steps answer a
ProcessDecision (state, commands, timeouts as { name, at }, cancel, ended). A state
the guard does not recognise throws UnreadableProcessStateError. InMemoryProcessStore keeps
the instances as JSON, for tests and one process. The runner is StoredProcessRunner of
@ddd-ts-kit/scheduling; why and how:
Sagas and process managers.
RateLimiter
Section titled “RateLimiter”import { DomainRefusal, type RateLimiter } from '@ddd-ts-kit/kernel';
export const IdentityCodes = { TooManyResetAttempts: 'TOO_MANY_RESET_ATTEMPTS' } as const;
export class TooManyResetAttempts extends DomainRefusal { readonly code = IdentityCodes.TooManyResetAttempts;
static withRetryAfter(retryAfterMs: number) { return TooManyResetAttempts.refusal('Too many password resets: try again later.', { retryAfterMs }).exposing( 'retryAfterMs', ); }}
export async function allowReset(limiter: RateLimiter, accountId: string): Promise<void> { const decision = await limiter.consume(`password-reset:${accountId}`, { limit: 3, windowMs: 3_600_000 });
if (!decision.allowed) { throw TooManyResetAttempts.withRetryAfter(decision.retryAfterMs); }}A sliding window: at any instant, at most limit allowed calls in the windowMs before it. A
RateLimitDecision is { allowed, remaining, retryAfterMs }; a refused call is not counted.
The key is whatever is limited: a client, a tenant, a route and an address together. In a
multi-tenant project, tenantKey(scope, 'password-reset', accountId) confines it to the tenant of
the work in progress (tenant:<id>:password-reset:<account>) and refuses work that names none.
InMemoryRateLimiter(clock) counts inside one process; the adapter shared by several instances
is in @ddd-ts-kit/redis. rateLimitDecisionOf(counted, limit) turns what an adapter counted
into the decision.
Tenancy
Section titled “Tenancy”The tenant of the work is ExecutionContext.tenantId, set at the boundary and read by
infrastructure only, like the rest of the context. The kernel holds what every strategy shares;
the isolation itself (tenant column, row-level security, schema or database per tenant) is in the
persistence packages, and the whole picture in
Multitenancy.
| Concept | What it does |
|---|---|
isTenantId(value), assertTenantId(id), InvalidTenantIdError |
the one grammar of a tenant id (letters, digits, _, -, at most 63): executionContext, executionContextOfEvent, acrossTenants, InMemoryTenantDirectory, tenantScopeOf, tenantReachOf and the row-level security settings refuse any other, so that no tenant id can be read as a wildcard, a list or a key separator |
tenantScopeOf(scope) |
the one tenant a write names; NoCurrentTenantError for work that names none |
assertNamesTenant(context, access) |
what a store of tenant data checks before it reads or writes: the work names a tenant, or reads under an elevation; NoCurrentTenantError otherwise, outside any execution scope included |
tenantReachOf(scope) |
what a read may see: { kind: 'tenant', tenantId }, or { kind: 'elevated', tenants } under an elevation |
tenantsOf(actor), isTenantMember(actor, tenantId) |
the tenants an actor belongs to: its tenantId and its tenants attribute |
acrossTenants({ scope, trail, clock, ids }, { reason, tenants }, work) |
platform staff reading over tenants: refused without a reason or a tenant, recorded in the AuditTrail (action tenancy:elevate) before the work runs; writes still name one tenant |
tenantKey(scope, ...segments), tenantCacheKey(scope, ...segments) |
keys of rate limits, locks and caches confined to the tenant: tenant:<id>:<segments>, each segment percent-encoded, so that two lists of segments never give one key |
TenantDirectory, InMemoryTenantDirectory |
the tenants that exist, for per-tenant jobs, provisioning and migrations |
TENANT_SETTINGS, tenantSettingValues(context), TENANT_ISOLATION_POLICIES, tenantPolicyExpressions(column) |
what the row-level security of the persistence packages shares: the three settings of a transaction (ddd_ts_kit.tenant_id, and for an elevation only ddd_ts_kit.reach and ddd_ts_kit.every_tenant), their values for the work in progress, the names of the four policies (one per command) and their read and write expressions |
An elevation is never implied by a role: the platform decides the permission to elevate (a use
case or a guard), then calls acrossTenants. A trail that fails to record it refuses it.
Page and PageRequest
Section titled “Page and PageRequest”One shape for every search, in two variants:
import { cursorPage, offsetPage } from '@ddd-ts-kit/kernel';
declare const cursor: string; // the nextCursor of the previous page
offsetPage({ offset: 40, limit: 20, sort: [{ field: 'placedAt', direction: 'desc' }] });cursorPage({ cursor, limit: 50 });// both build a PageRequest; the search answers a Page<T>: { items, total?, nextCursor? }
A cursor is opaque to the client and plain to the reader: encodeCursor(position) writes the
sort values of the last item of a page, decodeCursor(cursor) reads them back and refuses what
it did not write. It is not signed: the read port checks the types of what it decodes before
they reach a statement. A cursor needs a total order: append a unique key (the primary key)
to the sort, in the same direction, put it in the position, and compare the whole tuple. Rows
that are equal on the sort field otherwise have no defined order, and a page could repeat or
skip one of them. The adapter packages show the query for each ORM.
offsetPage and cursorPage validate and raise InvalidPageRequestError
(INVALID_PAGE_REQUEST) beyond PageLimits (default size 20, maximum 100). pageOf(items, more)
and mapPage(page, map) build and translate the answer. The sortable fields are a type
parameter, PageRequest<'placedAt' | 'total'>: they differ for each read port, which a global
augmentation could not express.
AuditStamp and TenantScoped
Section titled “AuditStamp and TenantScoped”AuditStamp (createdAt, createdBy, updatedAt, updatedBy) and TenantScoped (tenantId)
are columns of a stored record, not properties of an aggregate. stampCreation(scope, clock),
stampUpdate(scope, clock) and tenantScopeOf(scope) fill them in a repository adapter:
// insert: who creates is also who last updatedconst row = { ...toRow(order), ...tenantScopeOf(scope), ...stampCreation(scope, clock) };// update: the two columns to set, the creation is left alone; the tenant is part of every conditionawait update({ ...toRow(order), ...stampUpdate(scope, clock) }, { id: order.id, ...tenantScopeOf(scope) });stampUpdate(stamp, scope, clock) is the form for an adapter that holds the stored stamp (a
document store rewriting the whole record): it answers it whole, creation untouched.
tenantScopeOf raises NoCurrentTenantError for work that names no tenant, so a statement can
never run unscoped by omission. Every adapter package names the columns the same way:
created_at, created_by, updated_at, updated_by, tenant_id.
AuditTrail, AuditReader and AuditEntry
Section titled “AuditTrail, AuditReader and AuditEntry”abstract class AuditTrail { abstract record(record: AuditRecord): Promise<void>;}
abstract class AuditReader { abstract search(filter: AuditFilter, page: PageRequest<AuditSortField>): Promise<Page<AuditEntry>>;}The two ports of an audit trail and the shape of one entry (AuditEntry, AuditRecord for
what a source hands over, AuditFilter, and the types they name), so that code which records
or lists depends on the kernel alone. AuditTrail is append only and is fed by infrastructure
and cross-cutting code (a bus middleware, the authorization hook, an event subscription), never
by a use case or an aggregate. AuditReader is what a query handler depends on to list
entries. A project adds fields to every entry through AuditEntryExtensions.
The kernel holds no implementation: the hash chain, the sources, redaction, verification and
the stores, the in-memory one included, are @ddd-ts-kit/audit.
Not in the kernel
Section titled “Not in the kernel”Feature flags have no port here. Their evaluation model (boolean or variant, targeting, percentage, who the subject is) differs with each provider, and OpenFeature already is the vendor-neutral contract: a project that needs flags declares a port in the context that reads them, named after the decision it takes.
Criteria
Section titled “Criteria”A read of a read model, described once for every search: filters, a sort, a page. A criteria knows field names and nothing of a store. It is not a specification: a specification is a business predicate on an aggregate and lives in the domain; a criteria describes a read.
import { ReadModelStore, defineCriteria } from '@ddd-ts-kit/kernel';
export interface AppointmentRow {  readonly id: string;  readonly status: 'booked' | 'confirmed' | 'cancelled';  readonly startsAt: Date;  readonly practitionerId: string;  readonly cancelledAt: Date | null;  readonly tenantId: string;}
export const appointmentCriteria = defineCriteria<AppointmentRow>({  fields: {    id: { type: 'string' },    status: { type: 'string', filter: ['eq', 'in'], sortable: true },    startsAt: { type: 'instant', filter: ['gte', 'lt', 'between'], sortable: true },    practitionerId: { type: 'string', filter: ['eq'] },    cancelledAt: { type: 'instant', filter: ['isNull'], nullable: true },    tenantId: { type: 'string' },  },  defaultSort: [{ field: 'startsAt', direction: 'asc' }],  tieBreaker: 'id',  limits: { maxPageSize: 50 },});
export abstract class AppointmentList extends ReadModelStore<AppointmentRow> {}const criteria = Criteria.of<AppointmentRow>() .where('status', 'in', ['booked', 'confirmed']) .where('startsAt', 'gte', query.from) .or((any) => any.where('practitionerId', 'eq', query.practitionerId).where('cancelledAt', 'isNull', false)) .orderBy('startsAt', 'asc') .page(query.page);
const scope = await this.access.scope(query.actor, permissions['appointment.read'], 'appointment');
return this.appointments.search(scoped(criteria, scope, { ids: 'id', filter: { tenantId: 'tenantId' } }));From the handler to the store, a criteria is checked twice, and the scope of the actor travels with it:
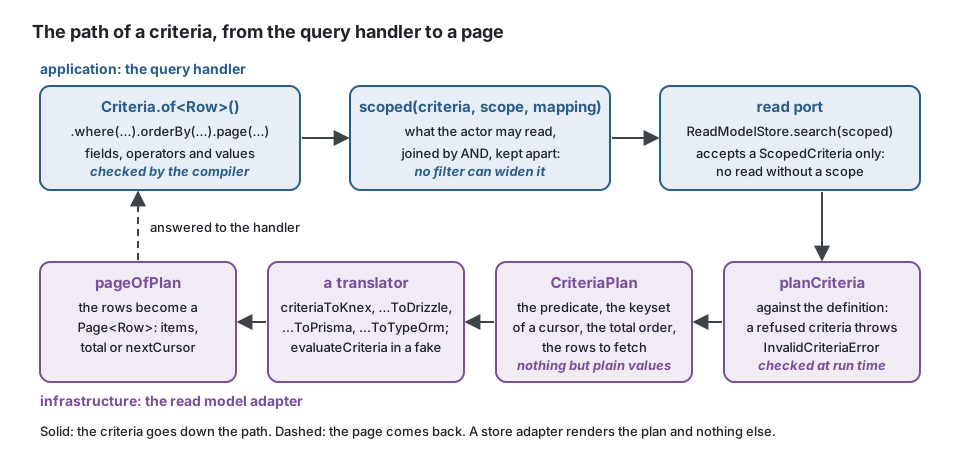
Checked by the compiler. where takes a field of the row, an operator that applies to
what the field holds, and a value of its type: where('seats', 'contains', '2'), an order on
a boolean, isNull on a field that is never null, a value outside a union of literals and a
field hydrated at query time are all refused. The same holds for a declaration: the type of
each field, its operators and nullable are checked against the row.
Checked by the read port. validateCriteria(definition, criteria) answers the violations,
never throws, and never quotes a value. planCriteria(definition, criteria) validates first and
throws InvalidCriteriaError (INVALID_CRITERIA): a criteria its definition refuses never
reaches a statement.
| Code | Path | Refused |
|---|---|---|
unknown_field |
filter.<field> |
a field the definition does not declare |
operator_not_allowed |
filter.<field> |
an operator the field does not declare |
invalid_value |
filter.<field> |
a value that is not of the type of the field, an empty list, a between without two values, an empty text to search |
in_list_too_long |
filter.<field> |
a list above maxInList (100) |
too_deep |
filter |
groups nested deeper than maxDepth (1: or(a, b); 2: or(and(a, b), c)) |
empty_group |
filter |
a group without a filter |
too_many_filters |
filter |
more conditions than maxFilters (20) |
unsortable_field |
sort |
a sort on a field not declared sortable (the tie-breaker always is) |
page_too_large |
page.limit |
a page above maxPageSize (100; the default size is 20) |
invalid_cursor |
page.cursor |
a cursor that is not the nextCursor of a page of the same sort |
What a criteria means
Section titled “What a criteria means”The reference is evaluateCriteria(definition, rows, criteria), which runs a criteria over
rows held in memory and is what a fake of a read port answers with. Every store translator is
held to the same table by criteriaContract of @ddd-ts-kit/testing/contracts.
| Rule | Meaning |
|---|---|
| Types | string; number; boolean; instant, a Date compared by its time, to the millisecond; decimal, a string of digits (-12.50) compared as a number without the rounding of a float |
eq, ne, in |
by value: two instants of the same time are equal whatever the zone they were written in, 10.5 is 10.50 |
gt, gte, lt, lte |
numbers, decimals and instants by value; strings by Unicode code point, so upper case comes before lower case ('B' < 'a'); not on a boolean |
between |
both bounds included |
contains, startsWith |
on a string only, case sensitive, the text taken literally: %, _ and \ are characters; an empty text is refused |
containsIgnoringCase, startsWithIgnoringCase |
the same searches with each letter of both sides in lower case, and nothing else folded: an accent is kept (e does not find é), no letter is rewritten (ss does not find ß). Every store answers the same for the ASCII letters and for a letter with one upper-case and one lower-case form, each one character long (É and é, Ñ and ñ, Greek and Cyrillic included); see below for the others |
isNull |
true keeps the rows without a value, false those with one; only on a field declared nullable |
| A null | never satisfies a comparison, ne included; only isNull sees it |
| Conditions | joined by AND |
and, or, not |
not holds on the rows that do not satisfy all its filters, nulls included: logic has two values, so not(room eq 'B') keeps the rows without a room, where SQL alone would drop them |
| Sort | the orderBy calls, then the sort of the page request for the fields not ordered yet; without any, the defaultSort of the definition |
| Total order | the tie-breaker of the definition ends every sort, in the direction of the last field, unless the sort names it |
| Null in a sort | the greatest value: last ascending, first descending (the default of PostgreSQL) |
false and true |
false first ascending |
| Offset page | the slice and total, the count of the filtered rows |
| Cursor page | no total; nextCursor when another page follows. The cursor holds the sort values of the last row, is checked against the declared types when it comes back, and belongs to one sort |
| No page | the first page of the default size |
A search that ignores case. foldCase(text) is the rule in memory: toLowerCase() of
JavaScript on both sides. The ORM packages write an ILIKE (the insensitive mode of Prisma),
which PostgreSQL folds with the locale of the database: a database created with the C locale
folds the ASCII letters alone. OpenSearch gets a regular expression that names both forms of
each letter. Outside the letters the table above guarantees, each store follows its own table:
the dotted and dotless I of Turkish, ß and ẞ, the final sigma, the ligatures and the
Kelvin sign may be found by one store and not by another. A b-tree index serves neither
LIKE '%x%' nor any ILIKE: on PostgreSQL, a GIN index of the pg_trgm extension on the
column (gin_trgm_ops) serves both, for a text of three characters or more. The kit does not
create it: it goes in a migration of the project.
Two things follow from where a store keeps its data, and are written in each adapter README.
Strings are ordered by the collation of their column: the reference is the "C" collation
of PostgreSQL, so a text column that is sorted or compared by range is declared COLLATE "C".
A decimal reads back as its column formats it (10.5, or 10.5000 for a fixed scale):
compare decimals as numbers.
The scope of the actor
Section titled “The scope of the actor”scoped(criteria, accessScope, mapping) answers a ScopedCriteria, which is what a read port
asks for: a read cannot reach it without a scope. The scope is kept apart from the filters and
joined to them by AND, so nothing a caller writes, an or or a not included, widens what the
actor may read; refine changes the criteria and keeps the restriction.
| Scope | Becomes |
|---|---|
{ kind: 'all' } |
nothing: the criteria as it is |
{ kind: 'none' }, or ids without any id |
an empty page, without a query |
{ kind: 'ids', ids } |
in on the field mapping.ids names; the list is the authorizer's and is not bounded by maxInList |
{ kind: 'filter', filter } |
one eq per entry, on the field mapping.filter names for its key |
A scope the mapping cannot express throws UnmappedReadScopeError instead of reading without
the restriction, and so does a mapped field the definition does not declare. The fields of a
scope need no operator in the definition: the read port chose them, not the caller. The scope
is the shape AccessScope of @ddd-ts-kit/auth, named ReadScope here so that the kernel
depends on no authorization model.
What that means on four rows, run in memory with the reference semantics:
import { Criteria, defineCriteria, evaluateCriteria, scoped } from '@ddd-ts-kit/kernel';
interface BookingRow {  readonly id: string;  readonly room: string | null;  readonly tenantId: string;}
const bookings = defineCriteria<BookingRow>({  fields: {    id: { type: 'string' },    room: { type: 'string', filter: ['eq'], nullable: true },    tenantId: { type: 'string' },  },  defaultSort: [{ field: 'id', direction: 'asc' }],  tieBreaker: 'id',});
const rows: BookingRow[] = [  { id: 'a-1', room: 'A', tenantId: 'acme' },  { id: 'a-2', room: 'B', tenantId: 'acme' },  { id: 'a-3', room: null, tenantId: 'acme' },  { id: 'g-1', room: 'A', tenantId: 'globex' },];
// `not` keeps the row without a room, where SQL alone would drop itevaluateCriteria(bookings, rows, Criteria.of<BookingRow>().not((all) => all.where('room', 'eq', 'B')));// items: a-1, a-3, g-1
// an `or` the caller writes never widens the scope: the scope is joined to it by ANDconst anyRoom = Criteria.of<BookingRow>().or((any) => any.where('room', 'eq', 'A').where('room', 'eq', 'B'));const acmeOnly = { kind: 'filter', filter: { tenantId: 'acme' } } as const;evaluateCriteria(bookings, rows, scoped(anyRoom, acmeOnly, { filter: { tenantId: 'tenantId' } }));// items: a-1, a-2; g-1 belongs to another tenant
// the caller cannot filter on tenantId itself: the field declares no operatorevaluateCriteria(bookings, rows, Criteria.of<BookingRow>().where('tenantId', 'eq', 'globex'));// throws InvalidCriteriaError: filter.tenantId (operator_not_allowed)
For a store
Section titled “For a store”planCriteria answers a CriteriaPlan, plain data a translator renders and nothing else: the
predicate of the filters and the scope, the predicate of the keyset for a cursor page, the
total order, the rows to fetch. Negations are already pushed down to the comparisons, so a
translator renders and, or and tests; the keyset is a predicate like another, so paging by
cursor is written once. pageOfPlan(plan, rows, total?) turns the rows a query answered into
the Page. The adapter packages hold the translators: criteriaToKnex, criteriaToDrizzle,
criteriaToPrisma, criteriaToTypeOrm.
Limits. No join: a field of another context is filtered once a projection copied it. No
aggregation, no full-text search. A long ids scope is a long IN list: beyond a few
thousand identifiers, project the right the scope stands for into the read model.
Hydration
Section titled “Hydration”Completing the rows of a read with data of another bounded context, at query time, through a gateway port: for detail views and small pages whose foreign data must be fresh. A list that filters or sorts by the foreign field needs a projection instead.
const page = await this.appointments.search(criteria);
return hydrate(page)  .with('practitioner', (row) => row.practitionerId, this.practitioners.byIds)  .with('location', (row) => row.locationId, this.locations.byIds)  .orElse('practitioner', unknownPractitioner, { onFailure: 'fallback', timeoutMs: 300 });
lookup is (ids: readonly string[]) => Promise<ReadonlyMap<string, T>>, a method of the
gateway port; the cached aspect of @ddd-ts-kit/aspects goes around the gateway as around
any other.
| Rule | |
|---|---|
| Calls | one per relation for the whole page, with each key once; none when no row has a key. Never one per row |
| Concurrency | the relations are looked up at the same time |
| Result | the row and the hydrated properties, typed; a Page stays a Page with the same total and nextCursor, a list of rows becomes a page of them; warnings is added |
| A row without a key, or unknown on the other side | left without the property, which is typed optional |
orElse(name, fallback) |
every row has the property, typed required: the fallback where nothing was found |
| A lookup that rejects | fails the whole hydration (policy fail, the default), fallback or not |
orElse(name, fallback, { onFailure: 'fallback' }) |
the rows take the fallback and warnings holds { relation, code: 'lookup_failed' }: never a silent success, never the error message |
timeoutMs |
the lookup is given up after that long (HydrationTimeoutError, warning code lookup_timed_out), then follows onFailure |
A hydrated property cannot be named by a criteria definition: FieldOf<Row> keeps the fields
that hold a scalar, and the compiler refuses the rest. The traces show one gateway <Port>.byIds span per relation, as for any call to a gateway: hydration opens no span itself.
Projections
Section titled “Projections”A projector keeps one read model up to date from events: integration events of upstream contexts, domain events of its own. It writes its read model through a port and does nothing else: it sends no command and reads no other context.
import { stampOf, type IntegrationEvent } from '@ddd-ts-kit/kernel';import { On, Projection } from '@ddd-ts-kit/kernel/declarations';
@Projection('scheduling.appointment-list')export class AppointmentListProjection {  constructor(private readonly appointments: AppointmentList) {}
  @On(AppointmentBooked)  booked(event: AppointmentBooked) {    return this.appointments.upsertIfNewer(event.aggregateId, stampOf(event), () => rowOf(event));  }
  @On(PaymentCaptured)  paid(event: IntegrationEvent<PaymentCapturedPayload>) {    return this.appointments.updateIfNewer(event.payload.appointmentId, stampOf(event), (row) => ({      ...row,      paid: true,    }));  }
  @On(AppointmentCancelled)  cancelled(event: AppointmentCancelled) {    return this.appointments.delete(event.aggregateId, stampOf(event));  }}
@Projection('<context>.<name>') is a declaration like the others: both decorator
modes, its dependencies stated by its constructor, one class per file, in
application/projections/, in a *.projection.ts file. @On(definition) on a method says
"this method applies that integration event"; @On(EventClass) says it for a domain event of the
projection's own context, under the name its class declares once, static readonly eventName.
A method that takes another event is refused by the compiler, a projection without any @On and an @On on a class without @Projection throw
when the file loads. A method answers what its store answered, which is how the application
counts what was applied and what was stale.
A role of the CLI. application/projections/ is a directory of the canonical tree,
ddd-ts-kit generate projection <context> <Name> <event-type> writes a projector with its
spec, the generated barrel <context>.declarations.ts exports it and registers what its
constructor takes, and ddd-ts-kit describe and the reference of CONTEXT.md list it with
the events it applies.
Idempotent and ordered by construction
Section titled “Idempotent and ordered by construction”ReadModelStore<Row> is the port of a read model: get, upsertIfNewer, updateIfNewer, delete and
search(scopedCriteria). Every row carries the stamp of the event that last changed it, and a
write happens only if its event is newer:
| Rule | |
|---|---|
| Stamp | stampOf(event): the id and the instant of an integration event; the name, the aggregate and the instant of a domain event; plus stampOf(event, version) when the event carries a per-key version |
| Newer | a greater version when both stamps carry one; else a later instant; at the same instant, the greater event id. The same event is never newer than itself. The order is total among stamps that all carry a version, and among stamps that carry none; between one of each the instants decide, which is not an order, so a key should see one kind (one kind of stamp per key) |
upsertIfNewer(key, stamp, next) |
for an event that says the whole row, or may create it: writes next(current), current being undefined when the key holds no row; stale when the row holds this event or a later one; ignored when next answers undefined, which is a filter (the event does not concern this read model) and never the way to wait for a row |
updateIfNewer(key, stamp, change) |
for an event that changes part of a row another event created: writes change(current); stale when the row, or the trace of its deletion, holds this event or a later one; missing when the key holds no row, the trace of a deletion older than the event, or a row of another tenant: nothing is written, the store never throws for it, and the projection decides. Right only when the events of the key are applied in order (which write for which event) |
delete(key, stamp) |
the row is gone for get and search, and a trace stays, its key and its stamp without any of its data: an older event delivered late does not bring it back, a later one does. A key the read model does not hold takes the same trace and answers traced, since no row was removed (as does a deletion over an earlier trace), so the creation this deletion follows is stale when it is delivered after it. On an SQL store every column of the row is nullable, or the store refuses the table with ReadModelTableNotReadyError (what a deleted row leaves) |
| Concurrency | a write is conditional on the whole stamp it read (sameStamp: the event id, the instant and the version, in every store) and is read again when another got there first; five attempts, then ConcurrencyError and the redelivery of the event |
| Transaction | the store writes on the executor of the unit of work, so the row and the processed-event mark of the event commit or roll back together |
So a redelivery, a duplicate and two events of one key delivered out of order all end on the
same row. What this does not give: an older event skipped as stale is not applied later, so
an event should carry the state of the fields it sets, or come in order per key (the outbox
orders per key); a change updateIfNewer answered missing or stale for is not applied later
either; with instants and
no version, the order of two events of one key is the order of the clocks that stamped them;
a version is compared with the version the row holds, so pass one only when every event of a
row comes from the same stream, and then on every one of them. One write is one row: an event that concerns many rows lists
them with a criteria and writes each.
TableReadModelStore is the one implementation of the port, over a ReadModelTable an
adapter gives (three statements and the query of a plan): InMemoryReadModelStore here for
the fakes, KnexReadModelStore, DrizzleReadModelStore, PrismaReadModelStore and
TypeOrmReadModelStore in the adapter packages, all held to readModelStoreContract.
On PostgreSQL the table of such a store holds the trace of a deleted row only if every column the
store maps as a field of its row accepts NULL. PostgresTraceColumns reads it from the database,
for those columns and no other: which refuse NULL, which nothing can open (a part of the primary
key, an identity or a generated column, a column of a domain that refuses NULL, a column that is
not there), whether the table exists, what its check constraint <table>_live_rows_whole keeps
whole, which other check constraints name a column of the row, and whether it is a view. It is
the refusal of one store before its first trace, and tableState() of a TableReadModelStore
answers the same reading as a ReadModelTableState. ReadModelTables asks it of the stores an
application lists, each entry a name and what builds the store as the application binds it:
hosting(contexts) keeps the entries of the contexts an application hosts and contexts names
those the list holds; states() and notReady() list, require() refuses with
ReadModelTablesNotReadyError,
atStart(logger) is what an application calls when it starts (atStart(logger, 'reported') logs
the tables as one error and lets the start go on), and report() is what a command prints, with
an outcome that tells a table that is not ready from a database that could not be read. Every
entry is tried: one whose store cannot be built or whose table the database refuses to read is
told under its name, in unread of the error, with its cause in a few words (the message of the
driver, never the statement), and the others are still read. A database that cannot be reached is
no refusal of a start: atStart logs one warning with the short cause and goes on, report()
answers unread. The verdict is the
store's by construction, a table nobody lists is never read, and a store without a table (memory,
OpenSearch) has nothing to say. What the check cannot decide is a warning: a constraint that is
not validated, a constraint of that name that is not written as the kit writes it (the form is
read exactly, as PostgreSQL prints it), another check on a column of the row unless it is written for the live rows only (deleted or ..), a view, a store the
application names as not listed. A refusal names the table, what keeps it from holding a trace
and the migration to write, in steps (statements holds both in order): the change of
definition, one statement that touches the mapped columns alone, writes the constraint not valid
and never drops a constraint that is not the kit's; then the validation and the cleaning of the
rows deleted before, which a large table runs outside the transaction of the first step. It can
be run twice. All held to readModelTablesContract on the four ORM: see
Every table checked at the start, and before a deployment.
Rebuild
Section titled “Rebuild”A read model fed by events that no event store keeps is rebuilt from the source of truth, the read contract the owning context publishes, behind a gateway port that answers stamped rows. A read model of event-sourced aggregates is rebuilt from the store instead: Fed by the event store.
await new ProjectionRebuild({ table: appointments.table, source, unitOfWork }).run();// source.export(cursor): a page of { key, row, stamp } and its nextCursor// source.lookup(keys): the rows of these keys as they are now| Step | What happens |
|---|---|
| 1 | an empty copy of the table is opened, with its indexes and constraints and the traces of the deleted rows; from then on every write of the projection records its key before it writes |
| 2 | the export is copied, page by page, into the copy. Events keep being applied to the table, which keeps answering reads |
| 3 | the recorded keys are read again from the source, in rounds, until few remain |
| 4 | in one transaction: the writers are held, the last recorded keys are read again, the copy takes the name of the table, the old table is dropped |
The copy is filled from the source alone, never from the table being replaced, so a rebuild
repairs rows the projection got wrong. No event is lost: an event is delivered after its
source committed it, so either the export read its row afterwards, or its key was recorded and
read again, or it is applied after the swap to a row whose stamp is older. No event is
applied twice: an event the source already reflected is stale against the stamp its row
came with. Both rest on what the source says of each row: the stamp of the last event its
state reflects. With the id and instant of that event, or a per-key version, the guarantee is
exact; with an updatedAt alone, an event of the very same instant is applied once more over
the state that already holds it, which is harmless for an event that sets state and wrong for
one that counts.
The window. Reads are never interrupted until step 4. Writers wait during step 4, for the
time it takes to read the last keys again (at most settledBelow, 50 by default, unless the
table changes faster than maxRounds rounds can follow) and to rename two tables. A write that
had started just before fails and is redelivered. A rebuild that fails drops its copy and
leaves the table as it was. On PostgreSQL the copy is made LIKE ... INCLUDING ALL:
privileges granted on the table by name, row security policies and triggers are not copied
and are restored by the migration that follows, and the indexes of the copy keep the names
PostgreSQL derived for them.
Fed by the event store
Section titled “Fed by the event store”A projection of event-sourced aggregates can be fed by the store rather than where the domain
events are dispatched: @Projection('scheduling.attendance-history', { feed: 'event-store' }).
The dispatcher then never calls it (@ddd-ts-kit/di registers no handler for it); a catch-up
subscription does, under the name of the projection, and the same projection rebuilds its read
model from position zero.
const apply = applyingProjection(projection, serializer); // the @On methods, by event name
const subscription = new CatchUpSubscription({ name: 'scheduling.attendance-history', store, checkpoints, unitOfWork, apply });
await subscription.catchUp(); // or poll() from a job: one batch, one unit of work
await new EventStoreProjectionRebuild({ table: history.table, store, unitOfWork, applierOn: (copy) => applyingProjection(new AttendanceHistoryProjection(copy), serializer),}).run();| Piece | What it does |
|---|---|
CatchUpSubscription |
Reads the store after the checkpoint of its subscriber (CheckpointStore), applies a batch and moves the checkpoint in one unit of work. A failure applies none of the batch; two runs of one subscriber never both move it (ConcurrencyError). A new projection starts at zero, so it catches up on the whole history |
applyingProjection(projection, serializer) |
(@ddd-ts-kit/kernel/declarations) hands each stored event an @On method applies, read back by the serializer of its aggregate, to that method; passes over the rest of the store |
storedStampOf(event) |
The stamp of an event read from the store: its id, instant and version in its stream, so the rows of one stream are ordered by the stream, not by clocks. undefined for an event that did not come from a store |
EventStoreProjectionRebuild |
Fills an empty copy of the table by replaying the store from position zero through the projection built over the copy (ShadowReadModelStore); then, in one transaction, holds the writers, replays what was appended meanwhile and puts the copy in place of the table. The subscription goes on from its checkpoint; what it applies again is stale against the copy. A failed rebuild leaves the table as it was |
A projection fed by the store applies the domain events of its context only: an integration
event reaches a projection where it is consumed, and @On(definition) on such a projection
throws when the file loads.
Seen from outside
Section titled “Seen from outside”Through the ports that exist. @ddd-ts-kit/di counts projection_events_total by context,
projection, event and result (applied, traced, stale, ignored, missing, failed) on Metrics, and
sets projection_last_event_age_ms, the age of the last event applied when it was: the lag.
missing is a change updateIfNewer found no row for.
A projection is subscribed as a consumer under its name, so each delivery is one process <projection> span, with the calls to its read model below it, and an event buried after its
retries reaches the error reporter as for any consumer.
Event sourcing
Section titled “Event sourcing”Chosen per aggregate, never per project: the other aggregates of the context keep their state in tables. When to choose it and what it costs: docs/concepts/event-sourcing.md.
type AttendanceEvent = AttendanceRecordOpened | NoShowNoted;
export class AttendanceRecord extends EventSourcedAggregate<AttendanceEvent, AttendanceState> {  private state: AttendanceState = { noShows: 0 };
  private constructor(id: string) {    super(id);  }
  static open(id: string, now: Date): AttendanceRecord {    const record = new AttendanceRecord(id);
    record.record(new AttendanceRecordOpened(id, now));
    return record;  }
  static rehydrate(id: string, history: AggregateHistory<AttendanceEvent, AttendanceState>): AttendanceRecord {    const record = new AttendanceRecord(id);
    return record.replay(history, (state) => record.restore(state));  }
  noteNoShow(appointmentId: string, now: Date): void {    if (this.state.noShows >= 3) {      throw PatientBarred.forRecord(this.id);    }
    this.record(new NoShowNoted(this.id, now, appointmentId));  }
  protected appliers(): Appliers<AttendanceEvent> {    return {      [AttendanceRecordOpened.eventName]: () => undefined,      [NoShowNoted.eventName]: (event) => this.applyNoShowNoted(event),    };  }
  private restore(state: AttendanceState): void {    this.state = state;  }
private applyNoShowNoted(event: NoShowNoted): void { this.state = { noShows: this.state.noShows + 1 }; }}| Piece | What it does |
|---|---|
EventSourcedAggregate<E, S> |
A command checks its invariants on the state, then record(event): the event is applied through the method appliers() names for it, and kept for the save. Only apply methods (and restore, for a snapshot) change the state (event-sourcing/state-in-apply). appliers() must name every event of the union, or it does not compile |
replay(history, restore?) |
Rebuilds from { snapshot?, events }, through the same apply methods, recording nothing. version is the number of events of the stream the aggregate reflects |
appendChanges(aggregate, append) |
What a repository adapter calls: the events recorded since the load and the version the stream must still have; on success the aggregate is at the new version |
EventStore |
The port: append(stream, expectedVersion, events) (a ConcurrencyError when somebody appended first, nothing kept of it), readStream(stream, after?), readAll(after, limit) in the order the appends committed, head(). InMemoryEventStore here; PostgreSQL through every ORM adapter. Held to eventStoreContract |
defineStoredEvent(Event, spec) |
How one event is stored: version of its shape, encode(event): NamedData (plain data, dates kept as ISO text), decode(data, envelope) reading each field by type (data.text('x'), data.instant('at'), data.record('amount')), and upcasters from each older version |
EventSerializer<E> |
Every stored event of one aggregate (StoredEventTypes<E>: one entry per event, or it does not compile). A stored event is never rewritten: it is upcast when read. An event of a later shape than the release knows, or a version without upcaster, is an UnreadableEventError |
EventSourcedRepository |
What the repository adapter delegates to: findById replays the stream <category>-<id> (from the last snapshot), save appends in the transaction of the unit of work; the events then leave with the save like any other |
SnapshotPolicy |
Per aggregate: every so many events, a version of the shape (another one is ignored, the stream replayed), encode, which seals a personal value with personalData as in an event, and decode. expectSnapshotEquivalence of @ddd-ts-kit/testing proves a snapshot rebuilds the state a full replay does |
personalData(subject, value) |
Marks a personal value in encode. PersonalDataCipher over a SubjectKeyStore seals it with the key of its data subject (AES-256-GCM); SubjectKeyStore.erase(subject) destroys the key, and a replay then reads ERASED_PERSONAL_DATA. decode reads a personal value with data.personalText('x'), data.personalInstant('at') or data.personal('email', Email.of), which answer undefined once the subject is erased, so a value that is not free text never makes the aggregate unreadable; data.isErased('x') says whether it was. The cipher opens an erased value as an ErasedValue, { $erased: { key } }, never as a text: data.text reads it ERASED_PERSONAL_DATA, a text that reads [erased] is not taken for one, and an upcaster sees that shape |
EventStorePersonalDataExport({ events, keys, name?, scope? }) |
The PersonalDataExport of what the event store keeps of a person: one record per event holding a value sealed with a key of the subject, under <name>.<event type> (event-store by default), naming its event (stream, aggregate id, version, instant), each value opened under its path in the data. Reads the whole store in rounds (batchSize, 500) in the order of the positions, which a store commits in, with a scope only the events of the tenant of the work; a value whose key was destroyed answers nothing, one that does not decipher is named in unreadable. runExport of a project with --event-sourcing on hands it over as platform.event-store |
@Repository(AttendanceRecordRepository)export class EventStoreAttendanceRecordRepository implements AttendanceRecordRepository {  private readonly streams: EventSourcedRepository<AttendanceRecord, AttendanceEvent, AttendanceState>;
  constructor(store: EventStore, snapshots: SnapshotStore, cipher: PersonalDataCipher) {    this.streams = new EventSourcedRepository({      store,      category: 'scheduling.attendance-record',      serializer: new EventSerializer<AttendanceEvent>(attendanceRecordEvents, { cipher }),      rehydrate: (id, history) => AttendanceRecord.rehydrate(id, history),      snapshots: { store: snapshots, every: 50, version: 1, encode: (record) => record.toState(), decode: stateOf },    });  }
  findById(id: string): Promise<AttendanceRecord | undefined> {    return this.streams.findById(id);  }
  save(record: AttendanceRecord): Promise<void> {    return this.streams.save(record);  }}
No double write. The store joins the transaction of the unit of work, and the publisher of
the integration events is a handler of the domain events that runs before the commit and
writes the outbox: the stream and the outbox records commit together or not at all.
eventStoreUnitOfWorkContract of @ddd-ts-kit/testing proves it for each transactional store:
nothing is published for an append rolled back or refused by a concurrency conflict.
Personal data
Section titled “Personal data”The right to erasure, of access and to portability, for what a context keeps of a person in clear: its rows. What a stored event seals is erased by the key of its data subject (see "Event sourcing"); what a table holds in clear is declared once, next to the mapper, and erased, exported and inventoried from that declaration.
export const personPersonalFields = personalFields<PersonRow>(PERSONS, { subject: 'id', // the column that names the data subject: an opaque identifier, never personal data itself fields: ['display_name', 'email'], erasure: 'row', // or 'pseudonymise': the rows stay, each text field reads ERASED_PERSONAL_DATA});| Piece | What it does |
|---|---|
personalFields(table, { subject, fields, erasure, files?, retention? }) |
The declaration: which columns of a table are personal, whose they are, and how the rows of a subject are erased (row, deleted; pseudonymise, each text field reads ERASED_PERSONAL_DATA and any other field nothing). files names the columns that hold the key of a file of the subject: the file is deleted from the FileStorage and the column emptied, whatever the mode. Refused (InvalidPersonalFieldsError): no field, a column listed twice, a subject column declared personal |
PersonalDataErasure |
The port a context extends and names, as it extends Repository: export abstract class PatientErasure extends PersonalDataErasure {}. name is the copy it reaches, as the report names it; erase(subject) erases what the context holds of the subject in the tenant of the work and answers how many rows it reached, none the second time. The persistence packages implement it from the declarations; InMemoryPersonalData here |
PersonalDataExport |
The port of the right of access and to portability, extended and named by the context as the erasure is: exportOf(subject) answers one PersonalDataRecord per row about the subject in the tenant of the work, { source, values }, the source <name>.<table>, each personal column and each file column (by its key) as plain data (PersonalDataValue: a scalar as it is, an instant as ISO text, null for nothing, JSON text for anything else), no other column and nothing of anyone else. The persistence packages implement it from the declarations (KnexPersonalDataExport, DrizzlePersonalDataExport, PrismaPersonalDataExport, TypeOrmPersonalDataExport); InMemoryPersonalData here |
eraseDataSubject(subject, { keys?, copies, shared, inEveryTenant, rebuilds, isKnown }) |
The whole erasure, in order: the key of the subject destroyed (SubjectKeyStore.erase, wrapped by auditedSubjectKeys of @ddd-ts-kit/audit so that a dated entry proves it; keys left out, nothing is sealed and the copies alone are erased, as in a project whose aggregates are rows), every copy erased in every tenant (each wrapped by auditedPersonalDataErasure, whose entries prove the erasure with or without a key), shared, the copies no tenant confines (the outbox, the job store), erased once, every projection fed by the store rebuilt. A copy or a rebuild that fails does not stop the others; the first failure is thrown once everything ran, and running the erasure again completes it. A subject that is not an opaque identifier (isDataSubjectId, the grammar of a tenant id) is refused before any key is touched (NotADataSubjectIdError); an id that destroyed no key, erased nothing and that isKnown denies is refused before the rebuilds (UnknownDataSubjectError): a mistyped id, or an erasure already complete. Answers { erased, copies, rebuilt }: whether a key was destroyed, the rows each copy reached, the events each projection replayed |
inEachTenant(scope, tenants) |
What inEveryTenant is given: runs a copy once per tenant, in the context of the work given that tenant, and sums the rows. A write of tenant data is confined to the tenant of its context and never widened by an elevation, so this is the one way to erase in every tenant |
exportDataSubject(subject, { exports, inEveryTenant, clock, isKnown }) |
The right of access and to portability (GDPR articles 15 and 20): every export, in the order listed, in every tenant, gathered into one PersonalDataExportDocument: format (PERSONAL_DATA_EXPORT_FORMAT, ddd-ts-kit/personal-data-export@1, so that a reader knows the shape and a later one is told apart), subject (the opaque id, never a name), exportedAt (from the clock: what the document states is true of that instant), records. Written as JSON, it is the structured, commonly used and machine-readable form article 20 asks for. An export that fails stops the gathering, since a document that silently lacked a context would state less than the system keeps; a subject that is not an opaque identifier is refused before anything is read (NotADataSubjectIdError: an export looks a person up by id, never by a name or an email, which would be a search in personal data); an id that answers no record and that isKnown denies is refused (UnknownDataSubjectError) rather than answered with an empty document that would state nothing is kept. Give it the exports wrapped by auditedPersonalDataExport of @ddd-ts-kit/audit, so that each handover leaves a dated entry naming who read what of whom, never the values |
retention: { after, days | months | years } |
How long the rows keep the person (GDPR article 5(1)(e)), counted from a date column of the row that is not personal data and dates the end of the relation (ended_at), never its beginning: counted from a registration, the purge would erase people who are still customers; one unit, a positive whole number of it (refused otherwise, InvalidPersonalFieldsError). Past that, the purge erases the row as erasure says; a row whose date is empty never expires. expiredBefore(period, now) gives the instant, in calendar units of UTC |
PersonalDataRetention, purgeExpiredPersonalData(now, retentions), isPersonalDataRetention |
The storage limitation: the port purgeExpired(now) answers the rows a copy erased, in the tenant of the work or in every tenant when the work names none; the erasure adapters of the four persistence packages and InMemoryPersonalData implement it from the same declarations. purgeExpiredPersonalData runs every copy at one instant, a failing one not stopping the others, and answers { purged } by copy; isPersonalDataRetention tells a copy that purges from one that only erases. A generated project runs it every night (privacy.purge-expired) and by hand (privacy:purge) |
dataSubjectErasedV1 |
The announcement of an erasure, privacy.data-subject.erased version 1, { subjectId, erasedAt }: the id of the person alone, no operator (the audit trail keeps who asked, the correlation id of the event leads to it), a name refused at create (InvalidDataSubjectErasedError). It lives here because the application layer of every context handles it, and it is shaped as a definition of @ddd-ts-kit/events, so that its registry, catalog, AsyncAPI, on and consume take it; @IntegrationEventHandler(dataSubjectErasedV1, { consumer }) declares a handler. A generated project publishes it through the outbox at the end of privacy:erase |
recordsInEachTenant(scope, tenants), eachTenant(scope, tenants, work) |
What inEveryTenant of an export is given: runs an export once per tenant and gathers the records in the order of the tenants, as inEachTenant sums the rows of an erasure; both over eachTenant, which runs the work once per tenant, in the context of the work given that tenant, and answers each result |
InMemoryPersonalData(name, declaration, { files? }) |
The reference implementation of both ports over one declaration, the rows held in memory (insert, all): the fake of a context, and what personalDataErasureContract and personalDataExportContract of @ddd-ts-kit/testing hold every adapter to |
pseudonymisedValueOf(sqlType) |
What a pseudonymised column reads, from its SQL type: ERASED_PERSONAL_DATA for a text (text, varchar, char, citext), nothing for any other type. The one rule the adapters of the four persistence packages follow (KnexPersonalDataErasure, DrizzlePersonalDataErasure, PrismaPersonalDataErasure, TypeOrmPersonalDataErasure), so that one declaration erases the same way on every ORM. NotNullablePersonalColumnError is what they throw, before any file or row is touched, for a column that would read nothing and does not accept null |
What it does not reach: an integration event published before the erasure and whatever consumed
it, the backups until they expire, and the audit trail, which names a person by an opaque id and
never by a name. Say so where the erasure is offered. The scheduling example runs this chain
(npm run privacy:erase) over the PersonalDataErasure of each of its contexts, the network of
each copy reached as a tenant, and
docs/concepts/personal-data.md says what a generated
project holds: the adapters of each persistence package, the platform folder init writes, the
register and the rules.
How to extend
Section titled “How to extend”Session, ExecutionContext, Actor, AuditEntry and ErrorReport each have an empty interface that a project fills by
declaration merging, once, in a declaration file of its platform:
import '@ddd-ts-kit/kernel';
declare module '@ddd-ts-kit/kernel' { interface SessionExtensions { readonly plan: 'free' | 'team'; } interface ExecutionContextExtensions { readonly region: string; } interface ActorExtensions { readonly department: string; } interface AuditEntryExtensions { readonly region: 'eu' | 'us'; } interface ErrorReportExtensions { readonly deployment: 'blue' | 'green'; } interface LogFields { orderId?: string; error?: Error; } interface MetricLabels { region?: 'eu' | 'us' | undefined; }}session.extensions.plan; // 'free' | 'team' | undefinedcontext.extensions.region; // string | undefinedactor.attributes.department; // string | undefinedentry.extensions.region; // 'eu' | 'us' | undefinedlogger.info('shipped', { orderId: 42 }); // compile error: orderId is a stringextensions, not top-level fields. A project field lives underextensions, so a standard field added toSessionorExecutionContextin a later version can never collide with it.- Optional when read.
anonymousSession(),systemSession()andexecutionContext()carry no extension, and they must stay truthful in every project: an extension reads asT | undefined. Actorkeeps its bag. Authorizers already readactor.attributesby name, and actors travel in messages:ActorExtensionsgives known attributes a name and a type inside that bag instead of adding a second one. An extension that is not anActorAttribute(a string, a number, a boolean or a list of strings) reads asnever.AuditEntryExtensionsholds JSON. An entry is hashed and stored as it is: an extension that is not plain JSON (aDate, a class) reads asnever.LogFieldsandMetricLabelstake new well-known keys the same way; unknown keys stay allowed.- Nothing to register. The augmentation is types only. Adapters of the kit keep compiling: they never read a project extension.