
@ddd-ts-kit/audit
A tamper-evident audit trail that the use cases never write to. Who was allowed or refused what, which command ran and how it ended, which integration event occurred, which data subject was erased: each fact is an append-only entry, hash-chained to the one before it, recorded by a bus middleware, the authorization hook, the HTTP pipeline when a guard refuses, an event subscription, or the key store of the data subjects. No handler and no aggregate contains an audit call.
npm i @ddd-ts-kit/auditnpm i knex pg # only for @ddd-ts-kit/audit/knexnpm i drizzle-orm # only for @ddd-ts-kit/audit/drizzlenpm i typeorm # only for @ddd-ts-kit/audit/typeorm| Entry | Holds | Imports |
|---|---|---|
@ddd-ts-kit/audit |
InMemoryAuditTrail, the sources (auditDecisions, auditGuardRefusals, auditMiddleware, auditIntegrationEvents, auditedSubjectKeys, auditedPersonalDataErasure, auditedPersonalDataExport, auditedPersonalDataRetention), logLostRecords and auditRecordOf, auditedFields, auditedProjection and masked, the AuditMasker port and hmacMasker, verifyChain, verifyTrail and its job VerifyAuditTrail, TenantAuditReader, the chain primitives (canonicalize, hashOf, wellFormed, GENESIS_HASH, chainOfTenant); re-exported from the kernel: AuditEntry, the AuditTrail and AuditReader ports and the types they name |
the kernel only |
@ddd-ts-kit/audit/knex |
KnexAuditTrail, createAuditTables, dropAuditTables |
knex (optional peer) |
@ddd-ts-kit/audit/drizzle |
DrizzleAuditTrail, auditEntriesTable, auditChainsTable, auditGuardStatements |
drizzle-orm (optional peer) |
@ddd-ts-kit/audit/prisma |
PrismaAuditTrail, auditPrismaModels, auditGuardStatements |
nothing: the client of the unit of work of @ddd-ts-kit/prisma fits structurally |
@ddd-ts-kit/audit/typeorm |
TypeOrmAuditTrail, auditEntities, auditGuardStatements |
typeorm (optional peer) |
@ddd-ts-kit/audit/testing |
auditTrailContract |
@ddd-ts-kit/testing (optional peer), the runner you pass |
The idea
Section titled “The idea”An audit trail answers "who did what, when, and was it allowed" to somebody who does not trust the application: an auditor, a customer, a regulator. Three consequences:
- It is fed from outside the use cases. A handler that must remember to call the audit will forget, and an aggregate that calls it has stopped being a model. Authorization decisions, refusals at the HTTP edge, commands and integration events already pass through a few places (the authorization middleware, the HTTP pipeline, the buses, the event subscriptions); the entries are written there.
- It is append-only and each entry seals the previous one. Changing, removing or
reordering an entry breaks the chain at a place
verifyChainnames. - It holds identifiers and codes, never content. Same rule as tracing and the aspects package: class names, permission ids, error codes; never arguments, results or messages. A value only enters when the project declares it, field by field.
It is not a log (logs are sampled, rotated and lost), not event sourcing (it does not rebuild
state) and not the AuditStamp of the kernel (createdBy, updatedBy: the last writer of a
row, not the history).
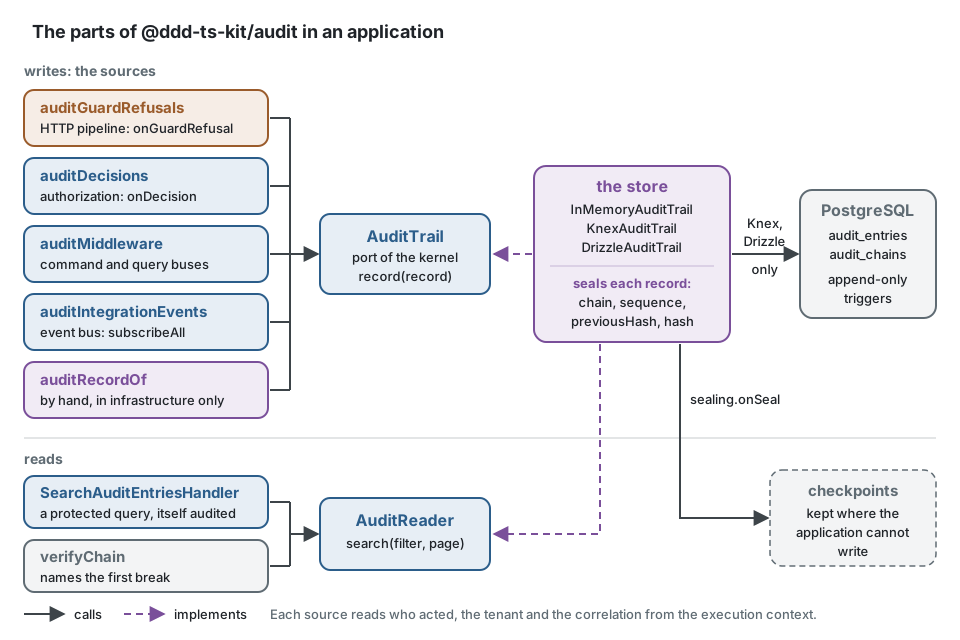
The diagram is the map of this page: the entry and its hash, the sources, redaction, verification, the stores and querying.
A first trail, in memory
Section titled “A first trail, in memory”Everything at once, in one file that runs: a command bus with the audit middleware, the
declaration of what the entry of one command carries, two commands, then the verification of
the chain and what a changed entry does to it. InMemoryAuditTrail is the fake of the tests;
in production a SQL store takes its place and nothing else changes.
import {  AuthorizedCommand,  FixedClock,  FixedExecutionScope,  InMemoryCommandBus,  SequentialIdGenerator,  executionContext,  type Actor,} from '@ddd-ts-kit/kernel';import { InMemoryAuditTrail, auditMiddleware, auditedFields, hmacMasker, masked, verifyChain } from '@ddd-ts-kit/audit';
class RescheduleAppointmentCommand extends AuthorizedCommand {  constructor(    actor: Actor,    readonly appointmentId: string,    readonly startsAt: Date,    readonly patientEmail: string,    readonly note: string,  ) {    super(actor);  }}
const ada: Actor = { id: 'ada', type: 'user', tenantId: 'acme', roles: ['practitioner'], attributes: {} };
// In an application, the HTTP boundary opens this scope for each request.const scope = new FixedExecutionScope(executionContext({ correlationId: 'request-1', actor: ada, origin: 'http' }));const trail = new InMemoryAuditTrail();
const commands = new InMemoryCommandBus()  .use(    auditMiddleware(trail, {      scope,      clock: new FixedClock(new Date('2026-03-01T10:00:00.000Z')),      ids: new SequentialIdGenerator('audit'),      masker: hmacMasker('a secret of the configuration', { keyId: 'k1' }),      fields: [        auditedFields(RescheduleAppointmentCommand, ['startsAt', masked('patientEmail')], {          resource: (command) => ({ type: 'appointment', id: command.appointmentId }),          context: 'scheduling',        }),      ],    }),  )  .register(RescheduleAppointmentCommand, { execute: async () => undefined }); // the handler: no audit call
const startsAt = new Date('2026-03-04T09:30:00.000Z');await commands.execute(new RescheduleAppointmentCommand(ada, 'apt-1', startsAt, 'lin@example.org', 'Family matter'));await commands.execute(new RescheduleAppointmentCommand(ada, 'apt-1', startsAt, 'lin@example.org', 'Again'));
// trail.entries[0]:// { id: 'audit-1', chain: 'tenant:acme', sequence: 1, occurredAt: 2026-03-01T10:00:00.000Z,//   category: 'command', action: 'RescheduleAppointmentCommand', outcome: 'succeeded',//   resource: { type: 'appointment', id: 'apt-1' }, context: 'scheduling',//   changes: { startsAt: '2026-03-04T09:30:00.000Z', patientEmail: { masked: 'k1:f3997a...' } },//   actor: { id: 'ada', type: 'user', tenantId: 'acme' }, tenantId: 'acme',//   correlationId: 'request-1', origin: 'http', extensions: {},//   previousHash: '0000...0000', hash: 'f65501...' }// No `note`: it was not declared, so it was never read.
await verifyChain(trail.entries); // { valid: true, checked: 2 }
// Somebody moves the appointment by one hour, in the trail itself:const first = trail.entries[0];
if (first !== undefined) {  trail.entries[0] = { ...first, changes: { ...first.changes, startsAt: '2026-03-04T10:30:00.000Z' } };}
await verifyChain(trail.entries);// { valid: false, checked: 0,//   break: { kind: 'altered-content', chain: 'tenant:acme', position: 0, sequence: 1, entryId: 'audit-1' } }
Ada works in the tenant acme, so her entries go to the chain tenant:acme; the second one
carries the hash of the first as its previousHash. The rest of this page takes each piece in
turn.
The entry
Section titled “The entry”The entry is a standard type of the kernel, and the two ports, AuditTrail and AuditReader,
are abstract classes of the kernel, so that code which records or lists depends on the kernel
alone. A port class is also what a binding is keyed by: there is no token beside it. This
package re-exports them, and holds everything that makes a trail tamper-evident: the chain, the
sources, redaction, verification and the stores.
interface AuditEntry { id: string; chain: string; // 'tenant:<id>', or 'global' for work that names no tenant sequence: number; // position in the chain: 1, 2, 3, without a gap occurredAt: Date; category: 'authorization' | 'command' | 'query' | 'integration-event' | 'authentication' | 'data-access' | string; action: string; // a permission id, a command name, an event type outcome: 'allowed' | 'denied' | 'succeeded' | 'failed'; reason?: string; // a stable code: NO_MATCHING_ROLE, the code of a DomainError actor: { id: string; type: ActorType | 'unknown'; tenantId?: string }; tenantId?: string; // the tenant of the work in progress impersonatedBy?: string; sessionId?: string; resource?: { type: string; id: string }; context?: string; // bounded context correlationId: string; causationId?: string; origin: ExecutionOrigin; // 'http', 'event', 'schedule', 'cli', ... changes?: Record<string, string | number | boolean | null | { masked: string }>; extensions: AuditEntryExtensionValues; previousHash: string; hash: string;}A source hands an AuditRecord (the entry without chain, sequence, previousHash and
hash) to the trail, which seals it. Actor, tenant, session, impersonation, correlation,
causation and origin are read from the kernel ExecutionScope, never threaded through a use
case.
A project adds its own fields by declaration merging, as for the kernel Session. They live
under extensions, are optional when read, and must be JSON (a Date or a class reads as
never), since they are hashed and stored as they are. The interface is the kernel's: augment
@ddd-ts-kit/kernel, next to the other extensions of the project (augmenting
@ddd-ts-kit/audit still works):
declare module '@ddd-ts-kit/kernel' { interface AuditEntryExtensions { readonly region: 'eu' | 'us'; }}One chain per tenant
Section titled “One chain per tenant”Each entry belongs to one chain: tenant:<id> when the work in progress names a tenant,
global otherwise (chainOfTenant). The reasons: a tenant can be verified, exported and
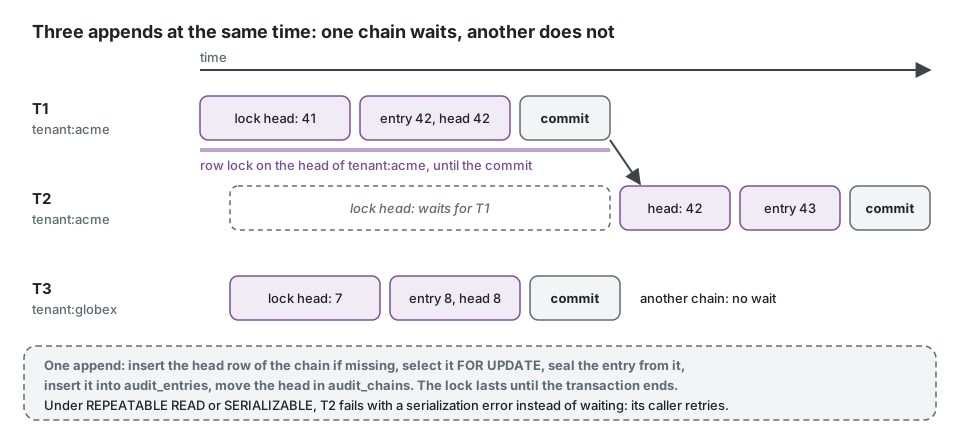
handed over without the entries of the others; appends to a chain are serialized, so one chain
for everything would make every command of the system wait for the same lock; and an
offboarded tenant leaves chains that still verify. The price: the order between entries of two
tenants is given by occurredAt only, not proven by a hash. Pass chainOf to a trail to
decide otherwise (one chain per bounded context, a single chain for a small system).
A command can act on a tenant other than the one of the work: a person of acme who opens an
organisation, or invites someone into another one they belong to. tenantOf(message) of
auditMiddleware names that tenant, and the entry of the message, once it succeeded, takes it
as its tenantId, so it is written in its chain, its actor.tenantId still that of the token.
A failure, and the decision of auditDecisions, stay in the tenant of the work: they record what
the caller asked, and a caller who names a tenant it cannot act in never writes to its chain, nor
opens one.
The hash
Section titled “The hash”hash is the SHA-256, in lower-case hexadecimal, of the canonical form of the entry without
hash, so previousHash, chain and sequence are part of what is sealed. The canonical
form (canonicalize) is meant to be computed again by any program, in any language:
- JSON without whitespace, encoded in UTF-8;
- the keys of every object sorted by UTF-16 code unit, at every depth;
- a property whose value is
undefinedleft out; occurredAtwritten in ISO 8601 UTC with milliseconds (2026-03-01T10:00:00.000Z);- strings and numbers as
JSON.stringifywrites them.
An entry is hashed as a store keeps it. A surrogate without its pair has no UTF-8 encoding and
PostgreSQL refuses NUL, so every text of an entry, the keys of changes and extensions and the
name of the chain included, is sealed with U+FFFD in their place: what is read back is what was
hashed, whatever a record held. wellFormed gives that form, to a store of your own as well.
The first entry of a chain has previousHash equal to GENESIS_HASH (64 zeros).
Wiring the sources
Section titled “Wiring the sources”Everything happens in the composition root. Assembled by hand first; the same pieces bound in
an application of @ddd-ts-kit/di come after the sources.
The order of the command middlewares matters:
import { unitOfWorkMiddleware } from '@ddd-ts-kit/kernel';import { authorizationMiddleware } from '@ddd-ts-kit/auth';import { subscribeAll } from '@ddd-ts-kit/events';import { auditDecisions, auditIntegrationEvents, auditMiddleware, auditedFields, hmacMasker, masked } from '@ddd-ts-kit/audit';import { KnexAuditTrail } from '@ddd-ts-kit/audit/knex';
const trail = new KnexAuditTrail(unitOfWork, { schema: 'audit' }); // anything with `executor()`: the unit of work of @ddd-ts-kit/knex, or its contextconst source = { scope, clock, ids };
commandBus  // 1. who may: refused before any transaction opens  .use(authorizationMiddleware({ authorizer, map, onDecision: auditDecisions(trail, { ...source, sensitivePermissions: ['records:medical-file.read'] }) }))  // 2. what ran and how it ended: opens the unit of work itself  .use(auditMiddleware(trail, {    ...source,    unitOfWork,    masker: hmacMasker(config.auditMaskingSecret, { keyId: 'k1' }),    fields: [auditedFields(RescheduleAppointmentCommand, ['status', 'startsAt', masked('patientEmail')], {      resource: (command) => ({ type: 'appointment', id: command.appointmentId }),      context: 'scheduling',    })],  }))  // 3. joins the transaction opened by 2  .use(unitOfWorkMiddleware(unitOfWork));
// 4. what occurred between contextssubscribeAll(eventBus, auditIntegrationEvents(trail, { registry, clock, ids, processed, unitOfWork }));
a. Authorization decisions
Section titled “a. Authorization decisions”auditDecisions(trail, options) returns the onDecision function of the authorization
middleware of @ddd-ts-kit/auth. The types match structurally: this package does not depend on
the auth package. Each entry has category authorization, the permission id as action,
allowed or denied as outcome, the denial code as reason, the resource of the decision.
What is recorded by default:
| Decision | Recorded |
|---|---|
| denied, command or query | always |
| allowed, anything that is not a read | always |
allowed read of a permission listed in sensitivePermissions |
always |
| any other allowed read | no |
Recording every list and every page view drowns the trail and makes it expensive to keep, so
the allowed reads are the ones you choose. allowedReads: 'all' records them all,
allowedReads: { sample: 0.01 } one in a hundred. A read is, by default, a decision whose
kind is query: the middleware takes it from the bus that carried the message, whatever the
class is named. A decision taken outside a bus names no kind and is recorded. Pass isRead to
decide otherwise.
When the decision concerns another actor than the one of the execution context (a consumer
sending a command on behalf of a user), the entry names the actor of the decision with type
unknown: its type and tenant are not in what the hook receives.
a'. Refusals at the edge
Section titled “a'. Refusals at the edge”A request a guard refuses (HasRole, HasScope, TenantMember, a tenant the caller does not
belong to) never reaches a use case, so the authorization middleware does not see it. The HTTP
pipeline reports it to onGuardRefusal, and auditGuardRefusals(trail, { clock, ids }) records
it: category authorization, action http:<operationId>, outcome denied, the code of the
refusal as reason (FORBIDDEN, UNAUTHORIZED), and the actor, session, tenant and correlation
of the request. A caller without a credential is not recorded: it is no one to hold to account,
the tenant it addressed is its own choice, and recording it would let unauthenticated traffic
write to the trail (and open hash chains) without bound; those refusals belong to the access log
and to rate limiting. A recorded refusal is in the tenant of the caller's credential. A guard
that fails instead of refusing (a lookup that threw, not a DomainError) is not reported.
mountExpress(app, routes, { ...boundary, onGuardRefusal: auditGuardRefusals(trail, { clock, ids }) });b. Commands, and the unit of work
Section titled “b. Commands, and the unit of work”auditMiddleware records each command with outcome succeeded or failed, and the code of
the DomainError as reason. A failure that is not a DomainError is recorded as
UNEXPECTED_ERROR: neither its class nor its message enters the trail, they quote data.
queries: [ReadMedicalFileQuery] or queries: 'all' records queries too.
Two requirements pull in opposite directions: the entry of a failed command must survive
the rollback, and the entry of a succeeded command must not exist if its transaction did
not commit. A middleware placed inside the unit of work loses the first, one placed outside
loses the second (a crash between the commit and the record, or an entry written for a commit
that was then refused). Hence the arrangement: the middleware is installed before
unitOfWorkMiddleware and is given the unit of work.
- It opens the unit of work itself;
unitOfWorkMiddleware, and any nestedrun, join that transaction. - After the handler returns, it writes the
succeededentry in that transaction. The entry and the state change commit together, or neither exists. If the entry cannot be written, the command fails and rolls back: no state change without its trace. - When the handler throws, or the commit is refused, the transaction is gone; the middleware
then writes the
failedentry outside of it, and rethrows the failure of the use case. If that write fails too, the caller still receives the failure of the use case, andonLostRecordis told.
logLostRecords(logger) is an onLostRecord that writes one audit entry lost line to the log,
at level error: the category, the action and the reason of the entry, the type and the code of
the failure, never its message, which quotes data. A project generated with the trail on passes
it to auditMiddleware, auditedSubjectKeys, auditedPersonalDataErasure,
auditedPersonalDataExport and auditedPersonalDataRetention, in the application and in the
scripts of --privacy on.
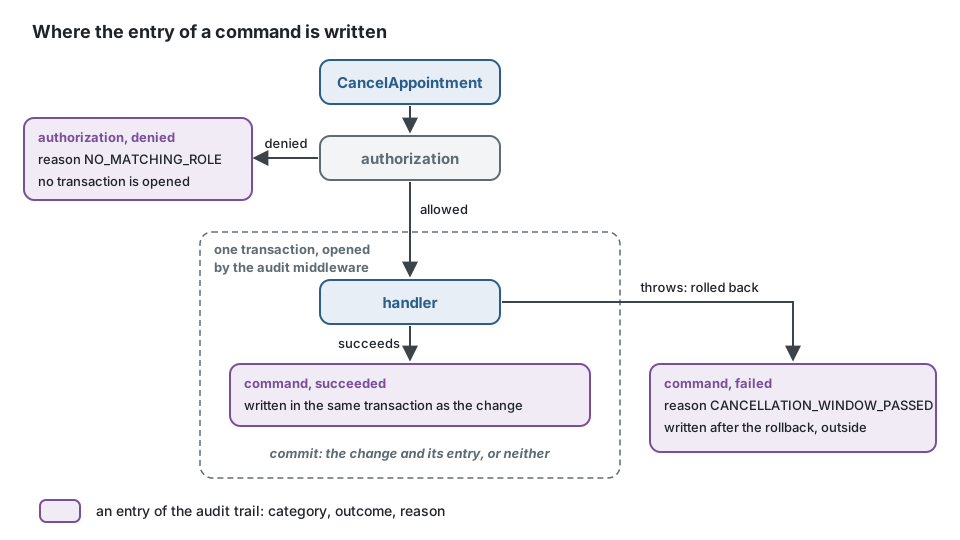
Without unitOfWork (no database, the in-memory trail) the middleware records after the
handler. Recording through the outbox would also be atomic for successes, but an outbox row
shares the fate of the transaction, so it cannot carry the failures: it solves half of the
problem.
Put the authorization middleware before this one. A refused command then leaves one
authorization denied entry and opens no transaction; with the opposite order it would also
leave a command failed entry with reason FORBIDDEN.
c. Integration events
Section titled “c. Integration events”auditIntegrationEvents(trail, options) returns one subscription per event type of the
registry, to hand to subscribeAll. It reads the envelope only (type, id, correlation), never
the payload: the entry says that billing.invoice.issued occurred, with the event id as
causationId and the correlation of the envelope. Delivery is at least once, so it
deduplicates by event id through the ProcessedEventStore it is given, under the consumer
name audit; with unitOfWork, the mark and the entry commit together.
d. By hand, the exception
Section titled “d. By hand, the exception”AuditTrail.record stays available for what none of the sources can see: a
data-access entry written by infrastructure, such as an export. auditRecordOf fills
everything the scope knows:
await trail.record(auditRecordOf({ scope, clock, ids }, { category: 'data-access', action: 'scheduling.appointments.export', outcome: 'succeeded', changes: { rows: 2000, format: 'csv' },}));This is infrastructure code. A call to the trail in domain/ or application/ is the defect
this package exists to prevent, and
layer/application-inward reports
an import of @ddd-ts-kit/audit in application/. What a handler is tempted to write, and what
replaces it:
import { AuthorizedCommand, type Actor, type AuditTrail, type Clock, type ExecutionScope, type IdGenerator } from '@ddd-ts-kit/kernel';import { auditRecordOf, auditedFields } from '@ddd-ts-kit/audit';
class CancelAppointmentCommand extends AuthorizedCommand {  constructor(    actor: Actor,    readonly appointmentId: string,  ) {    super(actor);  }}
// Instead of: the handler records its own entry. Each handler must remember to, a failure// leaves no entry at all, and the use case now depends on the audit.export class CancelAppointmentHandler {  constructor(    private readonly trail: AuditTrail,    private readonly source: { scope: ExecutionScope; clock: Clock; ids: IdGenerator },  ) {}
  async execute(command: CancelAppointmentCommand): Promise<void> {    // ... cancel the appointment ...    await this.trail.record(      auditRecordOf(this.source, {        category: 'command',        action: 'CancelAppointmentCommand',        outcome: 'succeeded',        resource: { type: 'appointment', id: command.appointmentId },      }),    );  }}
// Write: the handler only cancels. In the composition root, one declaration says what the entry// carries, and `auditMiddleware` records every outcome, failures included, with their code.export const cancelAppointmentAudit = auditedFields(CancelAppointmentCommand, [], {  resource: (command) => ({ type: 'appointment', id: command.appointmentId }),  context: 'scheduling',});
e. Erasures of data subjects
Section titled “e. Erasures of data subjects”Crypto-shredding erases a person by destroying the key their personal values were sealed with,
in the SubjectKeyStore of the kernel
(Event sourcing). The
date of that destruction is what the erasure is measured from: add the retention of the backups
of the keys, and you have the day it is complete. auditedSubjectKeys(keys, trail, { scope, clock, ids }) wraps the store, so that every erase, whoever calls it (a script, a command
handler, a job), writes an entry:
| Field | Value |
|---|---|
category |
data-access |
action |
personal-data:erase (SUBJECT_ERASURE_ACTION) |
outcome |
succeeded, or failed when the store threw, with the code of a DomainError or UNEXPECTED_ERROR as reason |
resource |
{ type: 'data-subject', id: <subject> } |
changes |
{ keyDestroyed: true }, or { keyDestroyed: false } when the subject had no key left |
| actor, tenant, session, correlation, origin | the execution scope |
The subject is the id the keys are stored under: an opaque identifier, never a name or an
email, like every resource id. A caller that takes the subject from a person (a script, a
form) checks its shape before erase: the entry is permanent, and the trail never holds
personal data. keyFor and find pass through and write nothing.
// the composition root: wrap once, and give the same instance to the container and to the scriptsconst subjectKeys = auditedSubjectKeys(eventSourcing.subjectKeys, trail, { scope, clock, ids });
builder.rebind(SubjectKeyStore).toValue(subjectKeys); // an erasure from a use case is recorded too
The keys and the trail are better kept apart (the keys in a store of their own, with a shorter backup retention), and then the two writes share no transaction; neither do they in a script that opens no unit of work. The order is chosen so that the trail never says more than what happened:
- The execution context is read first: an erasure outside
ExecutionScope.runthrowsNoExecutionContextErrorbefore any key is touched. A script opens one, with the operator as actor and the origincli. - The key is destroyed.
- The entry is written, dated once the store has answered.
When step 3 fails, erase rejects with that error: the key is gone, no entry says so yet, and
the caller knows the erasure is not finished. Running it again finds no key and records
keyDestroyed: false, at a later date: a completion date computed from that entry can be late,
never early. An erasure has to be safe to run again anyway, since what follows it (rebuilding
the projections that hold a clear copy) can fail too. The opposite order would write "erased"
before knowing it, and leave a false proof when the destruction then fails.
When step 2 fails, the store may or may not have destroyed the key: the entry says failed,
with the code of a DomainError or UNEXPECTED_ERROR, and the caller receives the error of
the store. If that entry cannot be written either, onLostRecord(error, record) is told, as
with auditMiddleware.
When the keys and the trail are in one database and the erasure runs inside a unit of work (a
command handler, behind unitOfWorkMiddleware), both writes join its transaction: the
destruction and its entry commit together or neither exists, and a failure rolls back the
failed entry with the rest. What the trail keeps of that failure is the failed entry of the
command, which auditMiddleware writes after the rollback.
What a project keeps in clear is erased copy by copy, and no key is destroyed for it: a project
whose aggregates are rows has no key store at all. auditedPersonalDataErasure(copy, trail, { scope, clock, ids }) wraps a PersonalDataCopy, so that every erase writes the same entry, with the name
of the copy as context and changes: { rows }, 0 included, under the actor of the work. The
execution context is read first, the rows are erased, then the entry is written; a failure is recorded
with its code and rethrown, onLostRecord told when that entry is lost too. runErasure of a
generated project wraps every copy, the outbox and the job store included.
const audited = (copy: PersonalDataCopy): PersonalDataCopy => auditedPersonalDataErasure(copy, trail, source);
await eraseDataSubject(subject, { copies: dataSubjectCopies.map(audited) });
f. Exports of data subjects
Section titled “f. Exports of data subjects”The right of access and to portability hands a person everything the system keeps of them: a read
of the whole profile, which the accountability of article 5(2) asks to be traceable, who read what
of whom and when. auditedPersonalDataExport(port, trail, { scope, clock, ids }) wraps the
PersonalDataExport port of a context, so that every exportOf, whoever calls it (the
privacy:export script of a generated project, a command handler, a job), writes an entry:
| Field | Value |
|---|---|
category |
data-access |
action |
personal-data:export (PERSONAL_DATA_EXPORT_ACTION) |
outcome |
succeeded, or failed when the port threw, with the code of a DomainError or UNEXPECTED_ERROR as reason |
resource |
{ type: 'data-subject', id: <subject> } |
context |
the name of the port: the bounded context |
changes |
{ records: <n> }, the number of records read, 0 when the context keeps nothing of the subject |
| actor, tenant, session, correlation, origin | the execution scope |
The entry never holds a value of the records: the trail is append-only and read by many, the
document goes to the person alone. The order is chosen so that no document leaves without its
trace: the execution context is read first (an export outside ExecutionScope.run is refused
before any row is read), the records are read, the entry is written, and only then are the records
handed over. When the entry cannot be written, exportOf rejects with that error and hands nothing
over; run again, it reads the same rows and records them. A trial run is a read like any other and
leaves its entry: try a script on a test subject, never on a real person. A read that fails is
recorded with its code, then rethrown; when that entry cannot be written either, onLostRecord(error, record) is
told. exportDataSubject of the kernel gathers the exports so wrapped into one dated document, and
init --privacy on wires it in src/platform/privacy/run-export.ts when the trail is on:
// src/platform/privacy/run-export.ts, as init writes it with --audit onconst audited = (port: PersonalDataExport): PersonalDataExport => auditedPersonalDataExport(port, trail, source);const exports = dataSubjectExports.map((port) => audited(container.resolve(port)));g. Purges of what outlived its retention
Section titled “g. Purges of what outlived its retention”The storage limitation of article 5(1)(e) is applied without anybody asking: the nightly job of a
generated project erases the rows that outlived the retention their declaration gives. The
accountability of article 5(2) asks for the proof that it runs. auditedPersonalDataRetention(port, trail, { scope, clock, ids }) wraps the PersonalDataRetention of a copy, so that every
purgeExpired writes an entry: category data-access, action personal-data:purge
(PERSONAL_DATA_PURGE_ACTION), the name of the copy as context, changes: { rows }, 0 included,
and no resource: a purge reaches rows by their age, never by whom they are about, so the entry
names nobody. The order is that of the exports: the execution context first (the job and the
script open one), the purge, then the entry; a failure is recorded with its code and rethrown,
onLostRecord told when that entry is lost too.
In an application of @ddd-ts-kit/di
Section titled “In an application of @ddd-ts-kit/di”The store is bound to both ports, and the masker to its own, each under its class:
import { AuditReader, AuditTrail } from '@ddd-ts-kit/kernel';import { defineContextModule } from '@ddd-ts-kit/di';import { AuditMasker, hmacMasker } from '@ddd-ts-kit/audit';import { KnexAuditTrail } from '@ddd-ts-kit/audit/knex';
export const trail = new KnexAuditTrail(unitOfWork, { schema: 'audit' }); // the unit of work bound to `UnitOfWork` and `KnexContext`
export const auditModule = defineContextModule({  name: 'audit',  register(builder) {    builder.bind(AuditTrail).toValue(trail);    builder.bind(AuditReader).toValue(trail);    builder.bind(AuditMasker).toValue(hmacMasker(config.auditMaskingSecret, { keyId: 'k1' }));  },});
builder.bind(AuditTrail).toClass(KnexAuditTrail, [KnexContext]) binds a store with its default
options instead, KnexContext being the port of @ddd-ts-kit/knex.
The sources are installed where the buses are built. The command bus of kernelModule() runs
the use case guard, then the unit of work; the audit middleware has to sit between the two, so
the bus is given through the options:
import { AuditTrail, InMemoryCommandBus, unitOfWorkMiddleware } from '@ddd-ts-kit/kernel';import { UseCaseGuard, kernelModule } from '@ddd-ts-kit/di';import { createApplication } from '@ddd-ts-kit/di/tsyringe';import { authorizationModule } from '@ddd-ts-kit/auth/di';import { AuditMasker, auditDecisions, auditMiddleware } from '@ddd-ts-kit/audit';
const source = { scope, clock, ids };
const app = createApplication({  modules: [    kernelModule({      executionScope: scope,      clock,      ids,      unitOfWork,      commandBus: (resolve) =>        new InMemoryCommandBus()          .use((message, next, info) => resolve(UseCaseGuard).check(message, next, info))          .use(auditMiddleware(resolve(AuditTrail), { ...source, unitOfWork, masker: resolve(AuditMasker), fields }))          .use(unitOfWorkMiddleware(unitOfWork)),    }),    auditModule,    schedulingModule,    authorizationModule({ authorizer, onDecision: auditDecisions(trail, { ...source, sensitivePermissions: ['records:medical-file.read'] }) }),  ],  authorization: 'required',});
A project generated by the CLI with --audit on (the default) has this wiring under
src/platform/audit/: create-audit-trail.ts builds the store of the entries, create-audit.ts its sources,
audit.module.ts binds the two ports, subscribes the integration events under the consumer
name audit and registers the protected SearchAuditEntriesQuery, and
src/platform/buses/create-command-bus.ts places the audit middleware between the use case
guard and the unit of work.
A handler or an adapter that needs the trail names the port in its dependencies and receives
the store: [AuditReader] for the query that lists entries (see Querying),
[AuditTrail] for the infrastructure adapter that records by hand.
Redaction
Section titled “Redaction”By default an entry carries no payload. changes exists only for what was declared:
auditedFields(RescheduleAppointmentCommand, ['status', 'startsAt', masked('patientEmail')]);auditedProjection(ExportAppointmentsCommand, (command) => ({ plain: { format: command.options.format } }));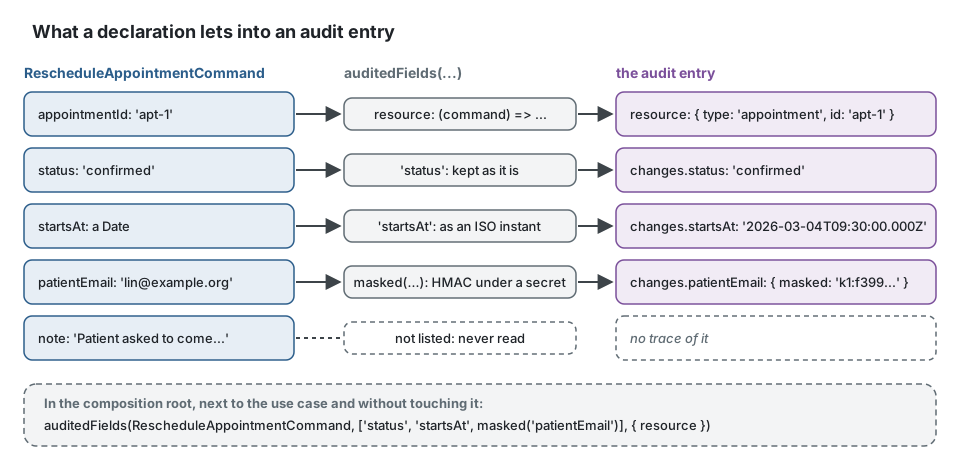
- A field that is not listed is never read. The compiler refuses a name the message does not have.
- A value is kept only if it is a string, a number, a boolean,
null, a bigint (as text) or aDate(as an ISO instant). An object is never stored whole: pick its scalars withauditedProjection. masked('patientEmail')stores{ masked: '<keyId>:<hex>' }: the HMAC-SHA-256 of the value under a secret (hmacMasker). Two entries about the same email carry the same mask, so "every entry about this person" can be answered by masking the email again; the email itself is not there, and without the secret a guess cannot be checked. A plain hash would not do: an email or a phone number is guessed in seconds.masked('patientEmail', { subject: 'patientId' })says whose the value is: the field of the message that holds the opaque id of the data subject, orsubjectOf: (command) => ...when no single field does. The masker reads it asdataSubject; the entry never carries it.- A field declared
maskedwithout a masker is refused when the middleware is built; a projection that asks for a mask without one fails the command at its first use.
What must never go in, declared or not:
- free text (a comment, a reason typed by a user, a message body): it contains anything;
- credentials and tokens, session cookies, API keys, one-time codes, even hashed;
- whole payloads, request bodies, aggregates, results of queries;
- error messages and stack traces: record the
code; - special categories of personal data (health, opinions, biometrics), even masked, unless a decision record says why.
The right to erasure and an append-only chain
Section titled “The right to erasure and an append-only chain”An entry cannot be deleted without breaking its chain, and a regulation may require that personal data be erased. The two coexist as long as the chain never holds the data:
-
Keep personal data out. An actor id, a resource id, a permission id are identifiers. If your identifiers are themselves personal data (an email as user id), fix that first, or mask them at the boundary.
-
Mask what you must correlate. A masked value is not readable; it is still linked to a person for whoever holds the secret.
-
Crypto-shredding for erasure.
subjectMasker(keys)masks each value under a key derived from the key of its data subject in theSubjectKeyStoreof the kernel, the same keys that seal the personal values of the stored events (HKDF of the material, labelled for the trail; in memory, or in thesubject_keystable the event store of every persistence package creates). Without event sourcinginitwrites no key store andprivacy:erasedestroys no key: a project that masks this way brings the store and its table, and gives the store askeystoeraseDataSubject, or its masks stay recomputable. Each masked field has to say whose it is,masked('patientEmail', { subject: 'patientId' }): the middleware refuses one that does not, at wiring time (MissingDataSubjectError), since the actor and the resource of an entry are rarely that person; and that subject has to be an opaque identifier (the grammar of a tenant id), since the key store writes it in clear: an email or a name in its place is refused before any key is created (MaskingSubjectNotAnIdError). Erasing a person (SubjectKeyStore.erase, wrapped byauditedSubjectKeysso that the erasure leaves its entry) destroys the key: every mask made with it becomes a random-looking token nobody can recompute, the entries stay, the hashes stay valid, and the key id written before each mask tells the masks of a key that is gone. The key store is then the system to protect: keep it apart from the trail and from the events, with a shorter backup retention.const keys = new PostgresSubjectKeyStore(run); // or InMemorySubjectKeyStore, or the one of create<Orm>EventSourcingauditMiddleware(trail, {scope,clock,ids,masker: subjectMasker(keys),fields: [auditedFields(RescheduleAppointmentCommand, ['status', masked('patientEmail', { subject: 'patientId' })])],});
What stays after erasure is "an actor with this opaque id did this at that time". Whether that
is acceptable is a legal question for the project, to answer before the first entry is written.
The erasure itself leaves a dated entry when the key store is wrapped by auditedSubjectKeys and
each copy by auditedPersonalDataErasure:
see e. Erasures of data subjects.
Verification and anchoring
Section titled “Verification and anchoring”const outcome = await verifyChain(reader, { chain: 'tenant:acme' });// { valid: true, checked: 1842 }// { valid: false, checked: 311, break: { kind: 'altered-content', chain: 'tenant:acme', position: 311, sequence: 312, entryId: '...' } }verifyChain(entries | reader, { chain?, from?, to?, checkpoints?, after? }) walks a chain in the
order given and reports the first place where it stops holding:
| Kind | Meaning |
|---|---|
altered-content |
the entry does not hash to its hash, does not link to the entry before it, or disagrees with a checkpoint |
missing-entry |
the expected sequence is nowhere in what was examined (a hole, a missing head, a chain shorter than to or than the last checkpoint given) |
reordered |
the expected sequence exists elsewhere, or a position appears twice |
position is the index among the examined entries of the chain, sequence the sequence that
was expected there. Given entries (an export), every chain found is verified, and the entries
are never sorted first: a shuffled file is reported as such. Given a reader, chain is
required and the range is read page by page, then held in memory: verify long chains by ranges
(from, to). A range starting above 1 trusts the entry before it. A chain that has archives
is verified from the anchor of the last one.
The walk stops at its first break: past it the chain proves nothing of what comes next, and after an entry that is gone or out of place where it goes on would be a guess. The break is the answer, and whoever has looked at it walks on from the entry after it, which trusts that entry:
await verifyChain(reader, { chain: 'tenant:acme', from: 313 });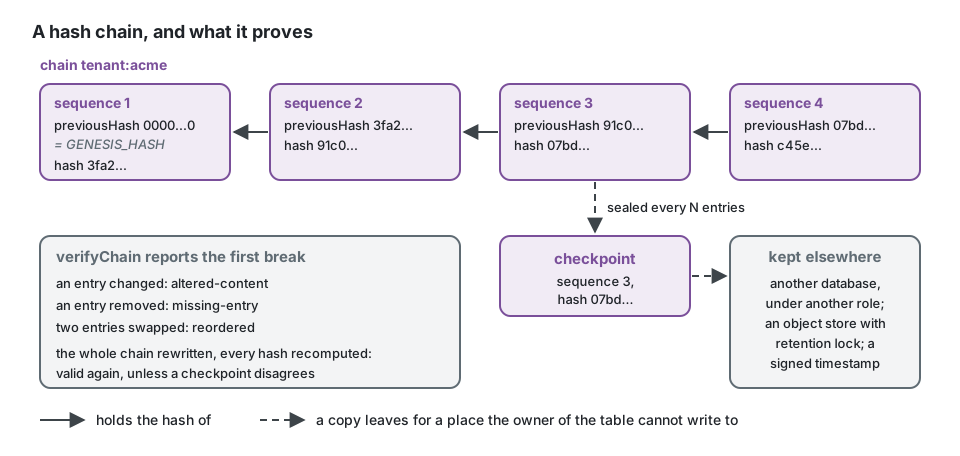
Why anchoring. The chain protects against whoever can change some rows. Whoever can
rewrite the whole table (a database administrator, an attacker with the owner's role) can
recompute every hash from the altered entry onwards: the result is a perfectly valid chain. The
only defence is a copy of some hashes where that person cannot write. sealing hands a
checkpoint over every N entries of a chain:
new KnexAuditTrail(unitOfWork, { schema: 'audit', sealing: { every: 1000, onSeal: (checkpoint) => outbox.append([auditChainSealed.create(checkpoint, meta)]) },});// later, against the checkpoints kept elsewhere:await verifyChain(reader, { chain, checkpoints });The hook runs when the entry is written, inside the unit of work when there is one. Appending
the checkpoint to the outbox there makes it leave only if the entry commits; a hook that calls
a remote service directly may anchor an entry whose transaction rolls back afterwards. Where
the checkpoints go is the project's choice: another database under another role, an object
store with retention lock, a transparency log, a signed timestamp. A truncated tail (the last
entries removed) is only seen by comparing with a later checkpoint or by asking for to: a chain
that stops before the last checkpoint given is reported missing-entry at the first position
gone, inside to when there is one. Given entries without chain, a chain a checkpoint names and
no entry holds is reported the same way.
Archiving
Section titled “Archiving”A trail grows for as long as the system lives, and every entry keeps the identifiers of a
person (GDPR article 5(1)(e), storage limitation). The four SQL stores and
InMemoryAuditTrail implement ArchivableAuditTrail: the oldest entries of each chain leave
the database for a FileStorage of the kernel, verified, and the chain goes on from their last
hash.
const { archives } = await trail.archiveBefore(new Date('2025-06-01T00:00:00Z'), { files, clock });// [{ chain: 'tenant:acme', fromSequence: 1, toSequence: 4211, lastHash: '...', entries: 4211,// fileKey: 'audit-archives/tenant/acme/000000000001-000000004211.ndjson', fileDigest: '...', archivedAt }]For each chain, in one transaction holding the head of the chain: the entries after the last
archive and older than the date, without a hole, are verified from the anchor of the archive
before them; they are written to one file, one canonical JSON per line; the archive is recorded
in audit_archives (range, last hash, SHA-256 of the file); then the entries are deleted. The
guard of the table lets a DELETE through only for entries an archive covers, and refuses any
change to the archives themselves. A chain that does not verify keeps every entry, a break being
for the operator to look at, not to bury in a file, and stops no other chain: each one is tried,
then AuditArchiveRefusedError says what was refused (refusals, each with its chain and its
chainBreak) and what the others archived (archives). The file is written, then read back from
the storage and its digest checked, before the transaction commits: a storage that did not keep it
is refused with AuditArchiveNotStoredError, which ends the run, and nothing of that chain is
removed; a failure afterwards leaves a file no archive names, which the next run writes again
under the same key.
What the trail proved stays provable:
const [first, second] = await trail.archivesOf('tenant:acme');verifyArchive(await textOf(files, second.fileKey), second, first);// { valid: true, entries: 1830 }: the digest, the range, every hash and link, the last hashawait verifyChain(trail, { chain: 'tenant:acme', after: { chain: 'tenant:acme', sequence: second.toSequence, hash: second.lastHash } });// { valid: true, checked: 1204 }: the entries left in the database link to the anchor of the last archiveafter says where the walk starts: at the position after the anchor, whose hash the first entry
must link to. A chain that has archives is verified that way. Its first entry has left the
database, so verifyChain(trail, { chain }) answers missing-entry at sequence 1, as for a chain
whose head was removed: the walk does not read the archives on its own. An anchor is what a row
of audit_archives says until verifyArchive has proved it against its file, so the caller names
the one it trusts.
verifyTrail(trail) verifies every chain of a trail that archives, each from the anchor of its
last archive to its head (chainHeads(): the sequence and the hash of its last entry), so a
chain cut at its tail answers missing-entry. The rows of the archives follow each other with
no gap, and the head goes on from the last one: a head behind it, or at its end with another
hash, answers altered-content. Given files, the storage the archives were written to, every
archive of each chain is read back, oldest first, and proved by verifyArchive against the one
before it: its digest, its range, every entry and link, its last hash. A storage that fails to
give a file back is the break of that chain alone (unreadable-archive). Without files, an
anchor is what its row says. Each chain stops at its own break and the others are verified all
the same:
await verifyTrail(trail);// { valid: true, checked: 1204, breaks: [] }// { valid: false, checked: 1180, breaks: [{ kind: 'altered-content', chain: 'tenant:acme', position: 24, sequence: 4235, entryId: '...' }] }VerifyAuditTrail(trail, files?) is the scheduled job of the platform that runs it and fails with
AuditTrailBrokenError (breaks, code AUDIT_TRAIL_BROKEN) on a break: the scheduler logs the
failed run and counts it. A generated project with the trail on registers it as audit.verify,
every night at 04:30 UTC, switched off with JOB_AUDIT_VERIFY_ENABLED=false, and npm run audit:verify runs the same verification by hand. The head is a row the role of the application
writes: it shows a tail removed behind the back of the trail, not a chain rewritten as a whole.
ArchiveAuditEntries(trail, files, clock, monthsOnline = 12) is the scheduled job of the
platform: each run archives the entries older than the first day of the month monthsOnline
whole months ago, in UTC, so a run missed is caught up by the next. A generated project whose
trail is in a database and whose files are in a storage registers it as audit.archive, on the
first day of every month at 04:00 UTC. With an object store (--storage s3) it runs unless
JOB_AUDIT_ARCHIVE_ENABLED=false; with --storage local it runs only with
JOB_AUDIT_ARCHIVE_ENABLED=true: the files would be on the disk of the server, which a
redeployment may wipe and a backup may not reach, and an archive removes the entries from the
database. Archive to a storage that is durable and backed up, with a retention lock where the law
asks for one.
A trail created before the archives adds them once, in a migration: addAuditArchives(knex, { schema }) on Knex, the statements of auditArchiveUpgradeStatements(schema) on Drizzle, Prisma
and TypeORM, after the table of the ORM was generated.
What an archive is not: a deletion. The entries still hold the identifiers of people, in a file instead of a row; how long the files are kept, and the retention lock of the bucket that keeps them, are decisions of the controller. The search of the trail reads the database only.
Stores
Section titled “Stores”InMemoryAuditTrail implements both ports: the fake for tests (entries is the store, to
assert and to tamper with) and enough for an application without a database.
The SQL stores are for PostgreSQL. They write on the executor of the unit of work
(KnexContext.executor(), DrizzleContext.executor(), PrismaContext.client(), TypeOrmContext.manager()): inside a unit of work the entry is
written at its commit and shares its fate, outside it is written at once in a transaction of its
own.
// knex: a migration of the projectimport { createAuditTables, dropAuditTables } from '@ddd-ts-kit/audit/knex';export const up = (knex) => createAuditTables(knex, { schema: 'audit' });export const down = (knex) => dropAuditTables(knex, { schema: 'audit' });
// drizzle: in the schema files drizzle-kit readsimport { auditChainsTable, auditEntriesTable, auditGuardStatements } from '@ddd-ts-kit/audit/drizzle';export const auditEntries = auditEntriesTable('audit');export const auditChains = auditChainsTable('audit');// and in a custom migration (drizzle-kit generate --custom), since drizzle-kit writes no trigger:for (const statement of auditGuardStatements('audit')) {  await db.execute(sql.raw(statement));}
new DrizzleAuditTrail(unitOfWork, { schema: 'audit' });
// prisma: the models in prisma/schema/schema.prisma (with "audit" in the schemas of the datasource), the// guard in a migration created with `prisma migrate dev --create-only`console.log(auditPrismaModels('audit'));new PrismaAuditTrail(unitOfWork, { schema: 'audit' });
// typeorm: the entities registered with the data source, the guard in a migration of your ownconst dataSource = new DataSource({ type: 'postgres', entities: [...auditEntities({ schema: 'audit' })] });new TypeOrmAuditTrail(unitOfWork, { schema: 'audit' });
The four stores share one PostgreSQL implementation, and their specs hold each to the same
contract, the entities and the models included: created by the migrations of a project, they
give the columns, the keys and the indexes of createAuditTables. Prisma writes raw statements on
the client of the unit of work: it nests no transaction, so an append inside one takes a
savepoint, and a failure of the database comes back with its SQLSTATE as code (23505,
23001), as on the other stores, where Prisma reports P2010. Its adapter of pg reads a
timestamptz without the offset of the session, so the reader asks PostgreSQL for the instant in
UTC.
Two tables: audit_entries (primary key (chain, sequence), unique id, indexes for the
reader) and audit_chains, one row per chain holding its last sequence and hash.
Concurrency. An append inserts the head row of its chain if it is missing, then takes it
with SELECT ... FOR UPDATE, computes the entry from it, inserts the entry and moves the head.
The row lock lasts until the transaction ends, so two appends to one chain never read the same
head and the chain cannot fork; appends to other chains do not wait. The primary key refuses a
duplicate position should the lock ever be bypassed. Under REPEATABLE READ or SERIALIZABLE
the second append fails with a serialization error instead of waiting, which rejects the unit of
work with TransactionConflictError (a ConcurrencyError, answered 409), and its caller retries
it, as for any other statement under those levels: the kit does not retry it.
At the commit. Inside a unit of work, what is recorded waits for its commit (atCommit of
the kernel): the entries are written last, after the work and its before-commit handlers,
each chain once, the chains in the order of their names. The head is then the last lock the
transaction takes and every transaction takes the heads in one order, so an append never closes
a deadlock (40P01) with the rows the work locked, nor with another chain, and a unit of work
still at its work does not make the other writers of its tenant wait. In return, the entries of
a unit of work are not visible inside it before the commit, and a refusal of the store (an id
written twice) fails the commit, not the call to record. Outside a unit of work the entry is
written at once; in a transaction opened by hand, the head then stays locked until that
transaction ends. A unit of work of another database opened inside the one in progress ends
before it: its entries are written at the commit of the outer one, in a transaction of their own.
Append-only in the database too. The migration helper creates the function
audit_entries_append_only and two triggers: UPDATE, DELETE and TRUNCATE on
audit_entries raise SQLSTATE 23001, whoever asks. Triggers stop mistakes and application
bugs; a role that owns the table can drop them. So the application should not own the table.
Run the migrations with an owner role, and give the application role and the role that archives
only what each needs:
revoke all on all tables in schema "audit" from public;grant usage on schema "audit" to app, audit_archiver;-- the application: appends, searches, verifies (audit.verify)grant select, insert on "audit"."audit_entries" to app;grant select, insert, update on "audit"."audit_chains" to app;grant select on "audit"."audit_archives" to app;-- the archive (audit.archive): the head of each chain locked, the archive recorded, the entries it covers removedgrant select, delete on "audit"."audit_entries" to audit_archiver;grant select, update on "audit"."audit_chains" to audit_archiver;grant select, insert on "audit"."audit_archives" to audit_archiver;The application can then neither rewrite nor remove an entry, nor disable or drop the guard. What
remains is the owner role and the superuser, which is what anchoring is for. The archive runs in a
process of its own connected as audit_archiver: in a generated project, JOB_AUDIT_ARCHIVE_ENABLED=false
for the application and a process of your own that runs ArchiveAuditEntries over a trail opened
with the DATABASE_URL of that role. An application that runs audit.archive itself, the default of
a generated project, also holds select, insert on audit_archives and delete on audit_entries.
The guard lets one DELETE through: that of an entry a row of audit_archives covers, which
archiveBefore writes in the same transaction. A role that may both insert into audit_archives
and delete from audit_entries can therefore let entries go behind a row of its own. Such a row
stays, the archives being append-only, and verifyTrail(trail, { files }) reads back the file of
every archive of each chain and proves it with verifyArchive: a row without its file, or
whose file does not prove it, is the break of its chain (missing-entry, or altered-content, at
the first sequence it names). The nightly audit.verify of a generated project with a storage of
files does so. Keep those two privileges to the role that archives.
A new store passes the same suite as these:
import { auditTrailContract } from '@ddd-ts-kit/audit/testing';auditTrailContract({ describe, it, expect, beforeEach }, { name: 'MyAuditTrail', createTrail: () => freshTrail(), tamper, cut });tamper and cut do what somebody with access to the storage does, rewrite an entry or remove the
end of a chain; without them the suite checks that on what it read. A store that archives passes
archivableAuditTrailContract too, with the same createTrail and cut: the head of every chain
(chainHeads), the archive of the entries older than a date (archiveBefore), its row
(archivesOf), and a verification that goes from the last archive to the head.
Querying
Section titled “Querying”const page = await reader.search( { tenantId: 'acme', actorId: 'ada', category: 'authorization', outcome: 'denied', from, to }, cursorPage({ limit: 50, sort: [{ field: 'occurredAt', direction: 'desc' }] }),);Filters: actorId, resource ({ type, id? }), action, category, outcome, period
(from included, to excluded), correlationId, tenantId, chain, fromSequence,
toSequence. Pagination uses the kernel types: an offset page answers total, a cursor page
nextCursor. Sort by occurredAt (then chain and sequence, the order a person reads in) or by
sequence (chain by chain, the order of verification).
AuditReader is a port of its own because reading the trail is itself a sensitive act. Expose
it as a use case like any other, which makes it protected and audited by the mechanisms above:
import { AuthorizedQuery, type AuditEntry, type Page } from '@ddd-ts-kit/kernel';
export class SearchAuditEntriesQuery extends AuthorizedQuery<Page<AuditEntry>> { /* actor, tenantId, filter, page */ }
// authorization: deny by default, one permission, flagged sensitiverequires(SearchAuditEntriesQuery, auditPermissions['trail.read']);auditDecisions(trail, { ...source, sensitivePermissions: ['audit:trail.read'] });auditMiddleware(trail, { ...source, queries: [SearchAuditEntriesQuery] });import { AuditReader, type AuditEntry, type Page } from '@ddd-ts-kit/kernel';import { QueryHandler } from '@ddd-ts-kit/kernel/declarations';
@QueryHandler(SearchAuditEntriesQuery)export class SearchAuditEntriesHandler { constructor(private readonly reader: AuditReader) {}
execute(query: SearchAuditEntriesQuery): Promise<Page<AuditEntry>> { return this.reader.search({ ...query.filter, tenantId: query.tenantId }, query.page); }}Whoever reads the trail leaves an entry in it. The handler depends on AuditReader of the
kernel, which application/ may import, and receives the store bound to it. It scopes the
filter to the tenant of the actor (an access scope computed by the authorizer), so one tenant
never lists another's entries.
In a multi-tenant project, bind new TenantAuditReader(store, executionScope) to
AuditReader instead of the store itself: every search is then confined to the tenant of the
work whatever its filter says (a filter naming another tenant or another chain finds nothing),
platform staff read across tenants only under an elevation (acrossTenants of the kernel, itself
recorded), and work that names neither is refused (NoCurrentTenantError).
Limits
Section titled “Limits”- PostgreSQL only for the SQL stores: row locks, row comparison for cursors,
jsonb, triggers. Another database is another adapter of the two ports, held to the contract suite. - Appends to one chain are serialized: two units of work of one tenant write their entries one after the other. Inside a unit of work the head is taken at the commit only, so the wait lasts a commit, not the work; in a transaction opened by hand outside of any unit of work, the head stays locked from the append to the end of that transaction.
- A rolled back unit of work frees its positions: the next entry reuses the sequence. There is never a gap, and never an entry for work that did not commit.
- A command sent from inside another unit of work (a consumer whose
consumeopened one) shares its fate: if that outer transaction rolls back, thefailedentry goes with it. - The chain proves integrity, not completeness of capture: a fact that never reached a
source (a script writing to the database, a route bypassing the bus) is not there. Keeping
every route on the bus is what
authz/declaredand the dependency rules are for. occurredAtis the clock of the instance that recorded; inside a chain, the order is the sequence.- Verification reads the range into memory, and trusts the entry before
from. - Archiving moves, it does not erase: how long the archive files are kept is a decision of the project, and so is the retention lock of the storage that keeps them. The search of the trail does not read the archives.
- drizzle wraps driver errors and prints the parameters of the failed statement in the
message of its error. The entry of an audit insert holds identifiers and codes only; still,
log the
codeof such an error, not its message.