
Documentation
Summary. This is the index of the long-form documentation of ddd-ts-kit. Four entries are normative, two short reference documents first: the architecture reference (the canonical tree, the rule ids, the tactical and clean code conventions, the test levels) and the configuration reference; then the pipeline README (the quality gates) and the README of each package. Everything else explains and teaches: the concepts behind the rules, the tool decisions with their comparisons and limits, and guides for working on such a project as a team and with coding agents. When a page here and the architecture reference disagree, the reference is right.
In French. Every page listed here has a French translation next to it (X.fr.md), reached
by the link on its first line; the French index is README.fr.md. Its diagrams
have French labels, and its code samples are compiled by the pipeline like the English ones.
On the web. These pages, the README of every package and the documents of the example are also published as a website, with search, in English and in French: https://ddd-ts-kit.github.io/ddd-ts-kit/. The Markdown files here stay its only source.
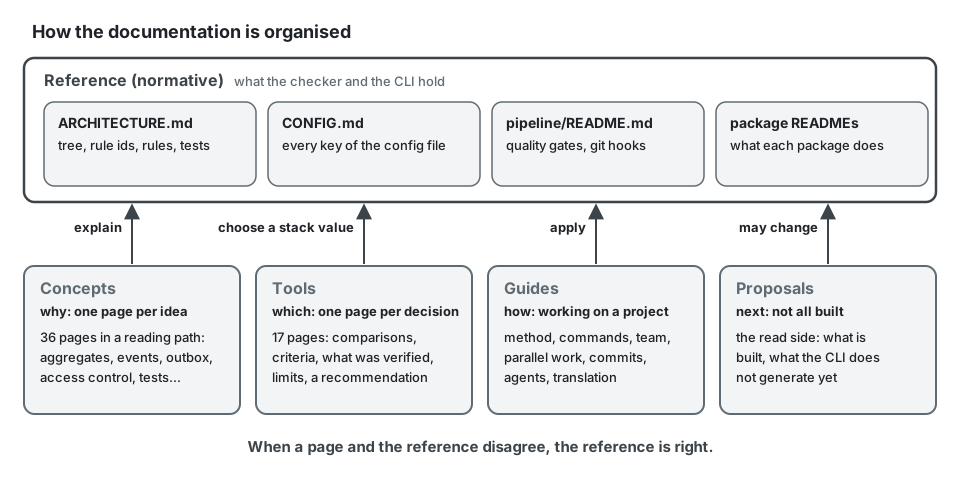
Reference (normative)
Section titled “Reference (normative)”| Page | What it holds |
|---|---|
| Architecture reference | the canonical tree, every rule id, the tactical rules, tests, clean code |
| Configuration | every key of ddd-ts-kit.config.json |
| Versions and stability | what a patch and a minor version may hold before 1.0, the ranges a project holds, upgrading, what 1.0 will guarantee |
| Lines left out of the coverage measure | the checks nothing can reach, why, and when each one goes |
| Cached entries per tenant | why cached files an entry under the tenant, throws without the scope, and skips an elevation |
| The in-memory tuple store refuses production | what createTupleStore allows, what an unset NODE_ENV does, and what reverses it |
| The regulated guard runs no program of the project | how the profile is read, why no denyWrite, and the checks the profile gives up |
| A refusal is an error at once before 1.0 | no transition, alias or shim before 1.0; a break ships with a To move line |
| The regulated guard runs git in its root only | the one repository the guard runs git in under the regulated profile, and what it leaves unread |
| The guard names the readers of VS Code | the tools of VS Code that write nothing, and why a list of readers and not of writers |
| A read model store on OpenSearch | each choice of @ddd-ts-kit/opensearch, and what reverses it |
| init wires OpenSearch | init --search opensearch: the tenancy, the provisioning of the declared stores, no generator yet, and what reverses each |
| Pipeline | the quality gates, the git hooks, GitHub and GitLab side by side |
Package READMEs under packages/ |
what each package does, its limits and what was verified |
Concepts: one page per idea
Section titled “Concepts: one page per idea”Ordered as a reading path in concepts/README.md.
| Page | In one line |
|---|---|
| Domain and subdomains | core, supporting, generic: how to classify and what it changes |
| Bounded context | what a boundary is, and the language, autonomy and consistency tests |
| Modules of the model | a context too large to read, divided into parts of one model (Evans), not into sub-contexts: the gains, the limits, how to adopt them |
| Ubiquitous language | the glossary-first rule and how a glossary is written |
| Context map | the relationship patterns, when each fits and what it costs |
| Context map: a worked example | the scheduling application, from a statement of needs to its map |
| Entities and value objects | identity versus value, and primitive obsession |
| Aggregates | consistency boundary, one transaction, reference by id, sizing |
| Domain building blocks | domain event, domain service, repository, factory |
| State machines | the lifecycle of an aggregate: states, transitions, guards, refusals, its diagram |
| Invariants, permissions, validation | three different things in three places |
| Anemic model | how to recognise one, and when a thin model is fine |
| Layers and the dependency rule | hexagonal, onion, clean: what they share, where they differ |
| Ports and composition | ports as abstract classes, the composition root, declared or explicit wiring |
| The presentation layer | one controller class per route, route groups, guards at the edge and permissions on the use case, mapper and serializer |
| Representations, field access and forms | one schema in JSON, XML or CSV by content negotiation, fields reserved to a permission, forms described by the server for each caller |
| CQRS | command and query buses, and event sourcing as a separate choice: what it buys and what it does not |
| Modular monolith | one deployable, contexts kept extractable |
| Domain and integration events | the two kinds of events and the translation between them |
| Transactional outbox | the dual write problem, the outbox, relay strategies |
| Delivery and idempotency | at-least-once, idempotent consumers, ordering |
| Eventual consistency | explained to a product person |
| Sagas and process managers | long-running processes: what the kit provides and what it does not |
| Event versioning | evolving a published event |
| Event sourcing, per aggregate | when to keep an aggregate as its events, what it costs, upcasters, crypto-shredding, projections fed by the store, migrating to it and back |
| Personal data in a generated project | what init --privacy on and generate repository --personal write, the erasure and the export of a person end to end, the two modes of erasure, the retention purged every night, the register generated by docs, the privacy/* rules, what stays out of reach and what the tool does not decide |
| Authentication and authorization | RBAC, ABAC, ReBAC compared, with a decision table |
| Authorization in practice | @Requires, the bus middleware, the Authorizer port and policies, followed through one command |
| Actor and execution scope | the explicit actor, and what every unit of work carries |
| Multitenancy | the tenant from the edge to the storage: isolation strategies, propagation, elevation of platform staff, the proof |
| Audit trail | tamper-evident history recorded around the use cases |
| Observability | tracing, logs, metrics, error reporting, the correlation id |
| Resilience | retry, timeout, circuit breaker, bulkhead, cache and their failure modes |
| HTTP caching | what to cache at which layer, cache policies, never a decision of authorization across actors |
| File storage | files in a storage, never in the database: staged before the transaction, moved to their key with the commit, served by short signed links |
| Scheduled jobs | jobs that trigger use cases, several instances, idempotence |
| Background jobs | work enqueued in the transaction of a command, run by a worker at least once, leases, checkpoints |
| File import and export | a design, not built: a large file read or written by a background job, batch by batch, between the queue and the file storage |
| Clean code | naming, small functions, stepdown, comments, with before and after |
| Testing strategy | fakes versus mocks, builders, contract tests, the four levels |
Tools: one page per decision
Section titled “Tools: one page per decision”Each page has a comparison table, selection criteria, what the kit supports and verified, the limits, and a recommendation by situation.
| Page | The decision |
|---|---|
| HTTP frameworks | Express, Fastify, Hono or NestJS, and what framework-agnostic routes cost with Nest |
| Validation | zod, class-validator, TypeBox or a Standard Schema library; shared schemas |
| Contract pairs | which framework with which validation library, by team: the four pairs proven end to end, measured; oRPC and tRPC as a second door, not a pair |
| Representations and forms | XML and CSV without a library, and why; JSON Forms renderers for React, Angular and Vue, and the alternatives |
| Dependency injection | the kit's declarations on tsyringe, InversifyJS or Awilix, NestJS, or manual wiring, compared and measured |
| Persistence | Drizzle, Knex, Prisma or TypeORM; PostgreSQL versus others; a read model on OpenSearch |
| Search read models | a read model on OpenSearch: what fits and what does not, init --search opensearch, the store of a context, its tests, its tenants, in production |
| Message brokers | in-process, RabbitMQ, Kafka, NATS JetStream or Redis Streams |
| Cache and coordination | Redis, Dragonfly or Valkey; what the lock does and does not guarantee |
| HTTP caches | Varnish, Souin, nginx, Fastly, Cloudflare or Bunny in front of the API: how each purges by tag, what the kit verified |
| File storage connectors | memory, local directory or S3 compatible (AWS, MinIO, OVHcloud, Scaleway, R2); how to write one for Google Cloud Storage or Azure |
| Identity | Keycloak or plain OIDC and JWT |
| Authorization engines | in-process models versus OpenFGA, SpiceDB, Cedar, OPA |
| Observability | OpenTelemetry with Jaeger or Tempo; loggers; Sentry or GlitchTip |
| Static analysis and pipeline | the checker, the ESLint plugin, dependency-cruiser, knip, TypeScript 6 and 7; GitHub or GitLab |
| Quality baseline | what every project gets and what each tool answers: type check, lint, format, dead code, import graph, architecture check, tests |
| Test runners | Vitest or Jest |
| Client SDK | openapi-typescript with openapi-fetch, hey-api or orval, measured on the example contract, against the client ddd-ts-kit sdk writes: typed error codes, no dependency; how it is checked and published |
| Import aliases | @/, declared once under tsconfig paths and rewritten into relative paths by the build; imports without an extension by default, and why the build writes the .js Node needs; why not a Node subpath import; what each tool reads |
Guides
Section titled “Guides”| Page | For |
|---|---|
| Methodology | the end-to-end path from a statement of needs to running code, step by step: the supported path |
| Which command, when | the command or skill for each moment of a project, a first feature from zero, and the reference of every command and flag |
| One slice, end to end | the request POST /orders through the four layers of a generated slice, and its domain and application code once filled |
| The plugin for coding agents | installing the plugin in Claude Code, Codex and Copilot, its twenty-six skills, six agents and hook, and what each host runs |
| Composing the kit with other tools | the kit inside an Nx workspace and beside Superpowers, from real sessions: one Nx project for the kit project, what to work around, which tool reports which import, two sets of agent instructions; which plugin conducts a feature, a plan, a test and a bug, and the section of AGENTS.md that decides it; Spec Kit and BMAD from a whole flow each, and the documents each writes beside those of the kit |
| Team workflow | ownership per context, the glossary, contracts first, review, decisions, onboarding |
| Parallel work | several people or agents at once: what is safe, what is sequenced, a concrete plan |
| Story workflow | one session per user story, one story per terminal: questions first, design review and acceptance tests before the code, a report of every provisional decision |
| Closing the loop | from a metric out of its band to the next story: the queries on the metrics the kit emits, a bands.yaml with three tiers, what a stateless run needs, the incident record a fix story starts from, what arrives from a chat channel |
| Commit discipline | commit and pull request size, generated files, what hooks and CI enforce |
| A handler with many dependencies | constructor over-injection read as a smell: an order of diagnosis, each remedy with its place in the tree, no limit |
| A cycle between two contexts | three questions before merging: one language or two, an event for one direction, a missing concept |
| When to extract microservices | the signals, the costs, a readiness checklist, the steps, when to merge back |
| Bootstrap with well-designed contexts | a generic context written whole with --preset identity: what it writes, what it asks of the stack, how it composes with each access model and with tenants |
| Choosing access control | five questions that pick roles, attributes or relationships (Zanzibar), worked presets for each, the combined model of the example, scopes and refusals at the edge |
| Token economy | spending fewer tokens with coding agents, and complementary tools |
| Sandboxing coding agents | what loads a machine and what the kit does about it; capping an agent, the sandbox of the agent, NVIDIA OpenShell for the security of a session |
| Deploy and rollback | what a project ships beyond its image, the order of a release, what a rollback of each piece means, three tiers of autonomy for an agent by environment, deploy, status and rollback as one script each, the rehearsal in staging |
| The French documentation | contributors: how every page keeps its French translation current, the glossary, the style of the diagrams, the code samples the pipeline compiles |
Proposals
Section titled “Proposals”| Page | Status |
|---|---|
| Which contexts deserve a preset | the criteria, then notification next, personal data requests as a guide; files (a capability of the platform), audit, billing and settings no |
| Modules inside a bounded context | built: sub-contexts are not a concept of the references, modules of the model are (Evans); the judgement of its gains and limits, and the spike that measured the cost on the example |
| The read side | criteria, representations, forms, read models and projections; the page says, part by part, what is built in the runtime packages, what the CLI does not generate yet and what is not built |
| Velocity of the build, the checks and the tests | studied, not built: where the time and the memory of this repository go, on a workstation and in the pipeline; the levers of Vitest, ESLint, Oxlint, the native compiler and the package managers measured on this tree; what other teams published about orchestrators, test selection and GitHub Actions; a plan in order of gain per cost, and why no orchestrator; the tools of the oxc-project (Oxlint, Oxfmt, tsdown, oxc-transform, the Oxc transform of Vitest) measured on 2026-10-26, with a verdict for each and the plan of their adoption |
| The families that generate projects | studied, one line built, then the levers the maintainer decided on 2026-10-26: what the pipeline jobs that generate projects cost per run and per day on a pull request, the trunk and at night (70 percent of a pull request run), what they repeat, nine levers with their gain and what a pull request would no longer prove, and a plan of pull requests in order of gain per effort |
| Privacy by design, beyond event sourcing | built, every part: why the kit, which erased the personal values of stored events alone, now declares the personal fields once and reads them in ports with an adapter per ORM (erasure, export, retention), generators, a register and privacy/* rules; the pull requests in merge order, the example adopting the ports; what a tool can never guarantee and the words to use |
| A second example, spend management on the most popular stack | specified, not built: NestJS, Prisma, Jest, Kafka, S3, ABAC on a business of money and workflows; first the four capabilities that stack switches off today (queue and processes on Nest, tenancy and audit on Prisma, the identity preset), then the example as the proof; MySQL left out, with what it would take |
| Where to take the kit next, from what neighbouring tools do | proposed, not built: sixteen neighbouring tools read on 2026-10-25 (agent methods, DDD plugins, import boundary tools, CQRS and event sourcing runtimes), nine proposals rated by value, cost and relevance, in tiers (now, next, later), and what the comparison suggests that the kit should not do, with the reason |
Start from a question
Section titled “Start from a question”| Your question | Where the answer is |
|---|---|
| Where does this file go, and what may it import? | the architecture reference, 2. Canonical tree and 3. Dependency rules |
| Why was this reported, and how do I fix it? | npx ddd-ts-kit explain <rule-id>, then When something is refused |
| Which command, or which skill, now? | Which command, when |
| Does this rule belong in the aggregate, the handler or the schema? | Invariants, permissions, validation |
| Why does the generator refuse my name? | Ubiquitous language: a name comes from the glossary of its context |
| How does one context react to another? | Domain and integration events, then Transactional outbox |
| How do I test a handler without a mock? | Testing strategy |
Which value for a stack key? |
the tools page of the decision, then Configuration |
| A rule does not fit this project | Deviations: a recorded decision, never a silent off |
| What changes after an upgrade of the kit? | Versions and stability, Migrate after a kit upgrade and a key left out of stack |
Part of the reference also answers in the terminal of a project, from the installed version of the kit, so it never disagrees with the code you run:
npx ddd-ts-kit rules # every rule id, its severity and what it holdsnpx ddd-ts-kit explain imports/alias-only # why a rule exists, a bad and a good example, how to suppress itnpx ddd-ts-kit generate --help # every kind of file the generator writes, and its flagsnpx ddd-ts-kit describe billing # one context as facts: use cases, routes, events, portsSuggested reading order
Section titled “Suggested reading order”New to DDD. Follow the reading path of concepts/README.md in order, at least sections 1 and 2, then:
- Layers and the dependency rule
- Domain and integration events and Eventual consistency
- Testing strategy
- Methodology, to see the ideas as steps
- the architecture reference, which will now read as a summary
Tech lead adopting the kit.
- the root README and the architecture reference
- Methodology
- the tools pages for the decisions you have to take, starting with Persistence, Message brokers and Static analysis and pipeline
- Modular monolith and When to extract microservices
- Team workflow, Parallel work, Commit discipline
- Token economy, if the team works with coding agents
- Configuration
- Personal data, before production: what is declared, erased, exported and purged, and what stays the decision of the controller
Contributor to the kit.
CONTRIBUTING.mdat the root, then the architecture reference: a change of rule starts there- Ports and composition and Layers and the dependency rule
- the README of the package you change, and of the CLI and the ESLint plugin, which hold the rules
- Static analysis and pipeline and Testing strategy
- the tools page of the area you touch: it states what was verified and what was not, which is where a contribution is most useful
- The French documentation, before changing a page: its French translation changes in the same pull request