
Persistence: Drizzle, Knex, Prisma, TypeORM, and which database
Summary. In this architecture an ORM is an implementation detail of
infrastructure/persistence/: rows never leave it, a mapper turns them into aggregates, and
transactions belong to the application through the UnitOfWork port. The kit ships the same
three pieces for four libraries (a unit of work with an ambient transaction, an outbox store, a
processed-event store), all held to the same contract suites. What differs is how each library
handles transactions, migrations, type safety and raw SQL, and how far each adapter was
actually tested: PostgreSQL is covered by the automated suites for all four, SQLite by those
of the Knex stores, MySQL 8 and SQLite were otherwise run by hand once for three of them, and
nothing else was run at all.
What the application asks of persistence
Section titled “What the application asks of persistence”The requirements come from the model, not from the library (aggregates, transactional outbox):
| Need | Why | Consequence for the tool |
|---|---|---|
| load and save one whole aggregate | Appointment is a consistency boundary |
a mapper, not an "entity" that is both row and model |
| one transaction per command, opened by a bus middleware | the handler never sees it | an ambient transaction the repository picks up |
optimistic concurrency on version |
two reschedules of one appointment | "update where version matches", count the rows |
| the outbox row in the same transaction | scheduling.appointment.booked exists if and only if the booking does |
the outbox store joins the unit of work |
| the processed-event mark with the consumer's change | notification handles a redelivery once |
same |
| a constraint the database enforces | no double booking, whatever any process believes | raw SQL in a migration (below) |
| one schema per context, no cross-context join | context/extractable in ARCHITECTURE.md |
schema-qualified tables |
The no-double-booking invariant shows what "raw SQL" means in practice. On PostgreSQL it is an
exclusion constraint over the calendar and the time an active appointment holds. None of the
four libraries expresses it in its schema language as far as this page could establish: it is
written by hand in a migration, and the repository adapter maps the violation to the refusal
SLOT_TAKEN of the domain (SlotTaken.forCalendar). The example application declares it
in create-scheduling-tables.schema.ts, after create extension if not exists btree_gist:
alter table scheduling.appointments add constraint appointments_slot_held_once exclude using gist (calendar_id with =, tstzrange(starts_at, held_until, '[)') with &&) where (status in ('requested', 'booked'));Two transactions that both read a free slot cannot both write it: the second one fails on the
constraint (SQLSTATE 23P01), whatever each believed when it checked.
The pieces, in one command
Section titled “The pieces, in one command”Four pieces do the work, and only the last one knows the library: the repository port of the domain, the unit of work the bus opens around each command, the repository adapter with its mapper, and the stores of the messaging (outbox, processed events). The sequence below follows one command, "pay an invoice", through them. Every statement runs in the transaction the unit of work opened, and the handler never touches it.
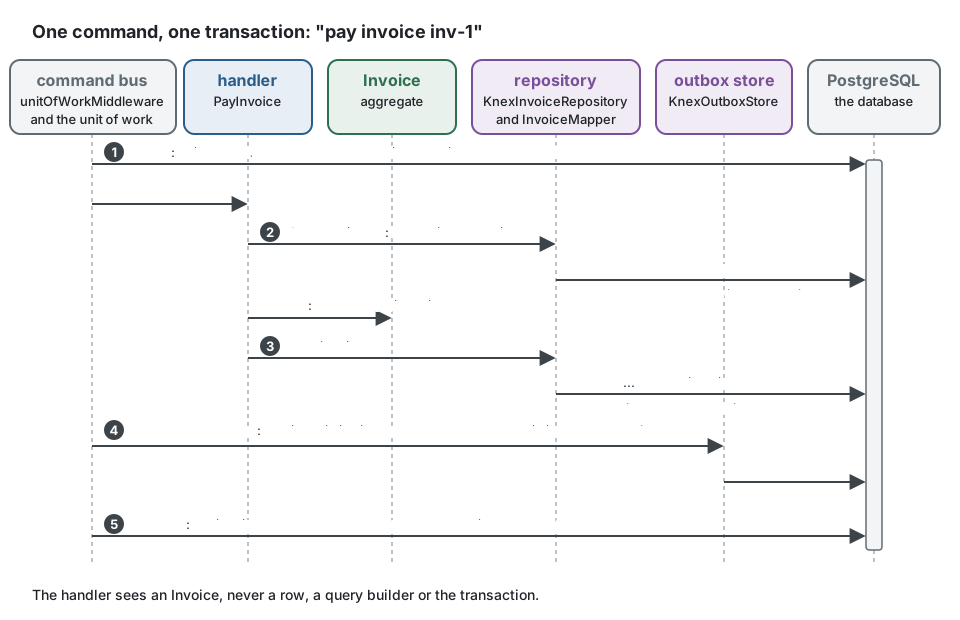
unitOfWorkMiddlewareof the kernel wraps every command of the bus inunitOfWork.run. The Knex unit of work opensknex.transactionand keeps it in anAsyncLocalStorage.- The adapter asks
KnexContext.executor()for its query handle: inside a run it is the transaction, outside it the pool. No method takes a transaction as a parameter. - The mapper turns the row into an
Invoiceand back. The aggregate carries theversionit was read at; theUPDATEonly matches that version. - When the handler has returned, the domain events the saves recorded are dispatched, still
inside the transaction. The handler of
InvoicePaidpublishes an integration event; theOutboxPublisherof@ddd-ts-kit/eventsonly appends it to the outbox store, which writes through the same executor. A relay sends it to the broker later. - The commit writes the invoice and the outbox row together; any failure rolls both back.
A repository adapter
Section titled “A repository adapter”The port is declared in the domain, the adapter and its mapper in
infrastructure/persistence/. The sample puts them in one module so that it compiles alone; in
a project each part is a file of its own, named in the comments. It follows KnexAppointmentRepository of the example
application.
import type { Knex } from 'knex';import { AggregateRoot, DomainRefusal, NamedDomainEvent, Repository } from '@ddd-ts-kit/kernel';import { type KnexContext, insertIgnoringConflict, optimisticUpdate } from '@ddd-ts-kit/knex';
// domain/events/invoice-paid.event.ts: the domain knows no row, no SQL, no library.export class InvoicePaid extends NamedDomainEvent('billing.invoice.paid') {  constructor(    readonly aggregateId: string,    readonly occurredAt: Date,  ) {    super();  }}
// billing.codes.tsexport const BillingCodes = { InvoiceAlreadyPaid: 'INVOICE_ALREADY_PAID' } as const;
// domain/errors/invoice-already-paid.error.tsexport class InvoiceAlreadyPaid extends DomainRefusal {  readonly code = BillingCodes.InvoiceAlreadyPaid;
  static forInvoice(invoiceId: string) {    return InvoiceAlreadyPaid.refusal(`Invoice ${invoiceId} is already paid.`, { invoiceId });  }}
// domain/aggregates/invoice.aggregate.tsexport class Invoice extends AggregateRoot {  private constructor(    id: string,    readonly amountInCents: number,    private paidOn: Date | null,  ) {    super(id);  }
  static issue(id: string, amountInCents: number): Invoice {    return new Invoice(id, amountInCents, null);  }
  /** Rebuilds a stored invoice: used by the mapper only. */  static rehydrate(id: string, amountInCents: number, paidOn: Date | null): Invoice {    return new Invoice(id, amountInCents, paidOn);  }
  get paidAt(): Date | null {    return this.paidOn;  }
  pay(on: Date): void {    if (this.paidOn !== null) {      throw InvoiceAlreadyPaid.forInvoice(this.id);    }
    this.paidOn = on;    this.record(new InvoicePaid(this.id, on));  }}
// domain/repositories/invoice.repository.ts: the port, findById and save come from Repository.export abstract class InvoiceRepository extends Repository<Invoice> {}
// infrastructure/persistence/invoice-row.schema.ts: the row never leaves infrastructure.type InvoiceRow = {  readonly id: string;  readonly amount_in_cents: number;  readonly paid_at: Date | null;  readonly version: number;};
// infrastructure/persistence/invoice.mapper.tsconst InvoiceMapper = {  toDomain(row: InvoiceRow): Invoice {    const loaded = Invoice.rehydrate(row.id, row.amount_in_cents, row.paid_at);
    loaded.version = row.version;
    return loaded;  },
  toRow(saved: Invoice, version: number): InvoiceRow {    return { id: saved.id, amount_in_cents: saved.amountInCents, paid_at: saved.paidAt, version };  },};
// infrastructure/persistence/knex-invoice.repository.tsexport class KnexInvoiceRepository implements InvoiceRepository {  constructor(private readonly database: KnexContext) {}
  async findById(id: string): Promise<Invoice | undefined> {    const row = await invoicesOf(this.database).where({ id }).first();
    return row === undefined ? undefined : InvoiceMapper.toDomain(row);  }
  /** No row written means another transaction saved it first: optimisticUpdate throws ConcurrencyError. */  async save(saved: Invoice): Promise<void> {    await optimisticUpdate(saved, async ({ expected, next }) => {      const row = InvoiceMapper.toRow(saved, next);
      if (expected === 0) {        const inserted = await insertIgnoringConflict(this.database.executor(), invoicesOf(this.database), {          row,          conflict: 'id',        });
        return inserted ? 1 : 0;      }
      return invoicesOf(this.database).where({ id: saved.id, version: expected }).update(row);    });  }}
/** The transaction of the running unit of work, or the pool outside one. */function invoicesOf(database: KnexContext): Knex.QueryBuilder<InvoiceRow, InvoiceRow[]> {  return database.executor()<InvoiceRow, InvoiceRow[]>('invoices').withSchema('billing');}
What each part holds:
| Part | Holds | Never holds |
|---|---|---|
Invoice |
the rules, the state, the events it records, and version (from AggregateRoot) |
a column name, a query |
InvoiceRepository |
what the application may ask: findById, save, the finders you add |
a type of the library |
InvoiceMapper |
the translation between the row and the aggregate, both ways | a query, a rule |
KnexInvoiceRepository |
the queries, the schema, the concurrency check, the mapping of a database error to a refusal | the transaction itself (executor() gives it) |
Instead of handing rows to the handler
Section titled “Instead of handing rows to the handler”The handler talks to the aggregate through the port; it never sees a row, a query builder or a transaction.
// Instead of: the handler edits a row, and the rule "an invoice is paid once" lives nowhere.const row = await db('billing.invoices').where({ id }).first();await db('billing.invoices').where({ id }).update({ paid_at: new Date() });
// Write: the handler loads the aggregate, asks it (it refuses a second payment), saves it.const invoice = await invoices.findById(id);if (invoice === undefined) throw new NotFoundError(`Invoice ${id} does not exist.`); // NotFoundError: @ddd-ts-kit/kernelinvoice.pay(clock.now());await invoices.save(invoice);
Composing the unit of work
Section titled “Composing the unit of work”One object answers both ports: the bus runs commands through UnitOfWork, the adapters and the
stores query through KnexContext. The example application composes it this way in
platform/database/persistence-over.ts.
import knex from 'knex';import { unitOfWorkMiddleware } from '@ddd-ts-kit/kernel';import { createKnexUnitOfWork, KnexOutboxStore, KnexProcessedEventStore } from '@ddd-ts-kit/knex';
const db = knex({ client: 'pg', connection: 'postgres://localhost:5432/app' });
// Bound to UnitOfWork (for the bus) and to KnexContext (for the adapters).export const unitOfWork = createKnexUnitOfWork(db);
// The stores write through it too: their rows commit or roll back with the command.export const outbox = new KnexOutboxStore(unitOfWork, { schema: 'messaging' });export const processedEvents = new KnexProcessedEventStore(unitOfWork, { schema: 'messaging' });
// The bus runs every command in unitOfWork.run; a query runs outside any transaction.export const transactional = unitOfWorkMiddleware(unitOfWork);
await unitOfWork.run(async () => {  // Here unitOfWork.executor() is the transaction and unitOfWork.inTransaction() is true.  await unitOfWork.run(async () => {    // A nested run joins the outer one: one commit, or one rollback, for both.  });});
The same pieces, under the name each package gives them:
| Knex | Drizzle (@ddd-ts-kit/drizzle/postgres) |
Prisma | TypeORM | |
|---|---|---|---|---|
| Unit of work | createKnexUnitOfWork |
createDrizzleUnitOfWork |
createPrismaUnitOfWork |
createTypeOrmUnitOfWork |
| What adapters query through | KnexContext |
DrizzleContext |
PrismaContext |
TypeOrmContext |
| Outbox store | KnexOutboxStore |
DrizzleOutboxStore |
PrismaOutboxStore |
TypeOrmOutboxStore |
| Processed-event store | KnexProcessedEventStore |
DrizzleProcessedEventStore |
PrismaProcessedEventStore |
TypeOrmProcessedEventStore |
Optimistic concurrency, and one contract for the fake and the adapter
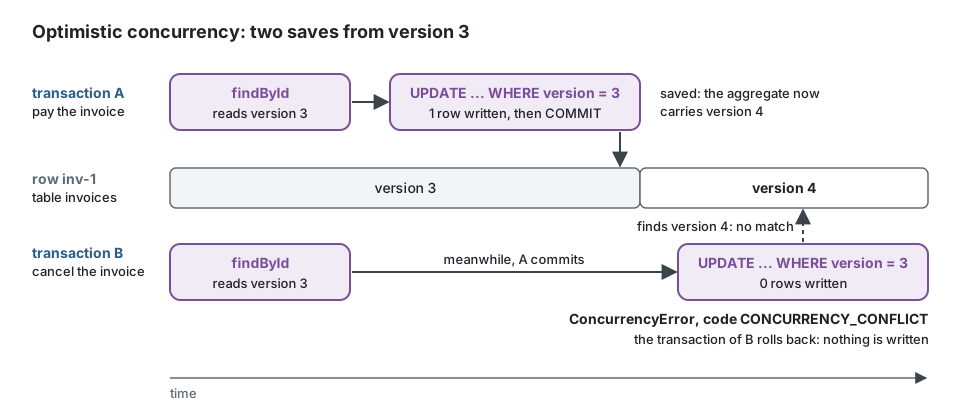
Section titled “Optimistic concurrency, and one contract for the fake and the adapter”Two commands may load the same invoice at the same version. The first save matches the
version and moves it on; the second matches no row, and optimisticUpdate throws
ConcurrencyError (code CONCURRENCY_CONFLICT), which rolls its transaction back. The four
units of work give the same answer when the database gives their transaction up for a
concurrent one, a deadlock (40P01) or a serialization failure (40001, Prisma P2034),
whichever statement it chose: TransactionConflictError, a ConcurrencyError whose cause is
the error of the driver, never an unexpected error.
A save that takes a value another row holds under a unique constraint (an email, a number) is
not a lost update: running it again is refused again. The four ORM answer it alike, on an
insert and on an update: UniqueViolationError, a ConflictError (code CONFLICT, 409) whose
cause is the error of the driver (23505, ER_DUP_ENTRY, SQLITE_CONSTRAINT_UNIQUE, SQLITE_CONSTRAINT_PRIMARYKEY, a raw SQLITE_CONSTRAINT whose message names a unique key,
P2002), raised by optimisticUpdate. The first save ignores a conflict on the id alone:
insertIgnoringConflict of Drizzle, Knex and TypeORM; on Prisma, whose skipDuplicates names
no target, rowsCreated looks the id up when nothing was written. Two first saves of one
aggregate made at once (a request delivered twice) are a lost update, on a table with a unique
column too: one writes the row and the other is answered ConcurrencyError, never a
UniqueViolationError for the value they both write. On PostgreSQL an insert whose conflict
target is the id alone would raise it, since the two inserts meet on the other unique index
first, so insertIgnoringConflict inserts with ON CONFLICT DO NOTHING, and only when that
wrote nothing with ON CONFLICT (id) DO NOTHING, which tells a taken id from a taken value. A handler that has a business answer
for the taken value (EMAIL_TAKEN) catches UniqueViolationError and raises its own refusal.
On MySQL, which has no conflict target and whose INSERT IGNORE skips that row too,
insertIgnoringConflict of Knex and of TypeORM asks whether a row holds the id when nothing was
written, and raises UniqueViolationError when none does, as rowsCreated does on Prisma.
A unit of work the database cannot serve in time is answered 503, not 500: Prisma bounds the
wait for a transaction (maxWait) and its run (timeout), Knex the wait for a connection
(acquireConnectionTimeout, 60 seconds), and beyond them the unit of work rejects with
TransactionTimeoutError (code SERVICE_UNAVAILABLE), nothing committed. A generated project on
Prisma reads both limits from DATABASE_TRANSACTION_WAIT_MS and
DATABASE_TRANSACTION_TIMEOUT_MS, 10 and 30 seconds by default (a caller gives up near 30
seconds, and a connection held longer sheds no load); Drizzle and TypeORM wait for a
connection of their pool and bound no transaction, so they have no such setting.
The fake of the unit specs and the real adapter keep that promise alike: the same
repositoryContract runs against both, the fake in memory and the adapter on PGlite or a real
server.
import { randomUUID } from 'node:crypto';import { afterEach, beforeEach, describe, expect, it } from 'vitest';import { AggregateRoot, type Repository } from '@ddd-ts-kit/kernel';import { InMemoryRepository } from '@ddd-ts-kit/testing';import { repositoryContract } from '@ddd-ts-kit/testing/contracts';
// From the sample above, and from the test database of the project.declare class Invoice extends AggregateRoot {  static issue(id: string, amountInCents: number): Invoice;  static rehydrate(id: string, amountInCents: number, paidOn: Date | null): Invoice;  readonly amountInCents: number;  readonly paidAt: Date | null;  pay(on: Date): void;}declare function knexInvoiceRepositoryOnAnEmptyDatabase(): Promise<Repository<Invoice>>;
const runner = { describe, it, expect, beforeEach, afterEach };
const expectations = {  createAggregate: () => Invoice.issue(randomUUID(), 12_000),  mutate: (invoice: Invoice) => invoice.pay(new Date('2026-10-01T09:00:00.000Z')),  idOf: (invoice: Invoice) => invoice.id,  stateOf: (invoice: Invoice) => ({ amountInCents: invoice.amountInCents, paidAt: invoice.paidAt }),};
// The fake the unit specs use: a Map that checks the version like the adapter.repositoryContract<Invoice>(runner, {  ...expectations,  name: 'InMemoryRepository<Invoice>',  createRepository: () =>    new InMemoryRepository<Invoice>({      clone: (invoice) => Invoice.rehydrate(invoice.id, invoice.amountInCents, invoice.paidAt),    }),});
// The adapter, on a database emptied before each test.repositoryContract<Invoice>(runner, {  ...expectations,  name: 'KnexInvoiceRepository',  createRepository: knexInvoiceRepositoryOnAnEmptyDatabase,});
The contract checks that a saved aggregate is found with its state, that two aggregates stay
apart, that later saves are stored, that a change not saved is not, and that a save over a
version it did not read is refused with CONCURRENCY_CONFLICT.
The stale-save case needs a mutate that records a change of state: the contract changes both
copies, so that a table adapter and an event store alike refuse the stale one. When mutate
records nothing, the case fails with mutate changed nothing: give the contract a change of state
instead of waiting for a conflict that never comes. mutate is optional: without it the case
stays pending (it.todo, with the reason give the contract a mutate that records a change of state), which is how a freshly generated contract spec starts. A save without a change is not
judged: a table adapter moves the version, an event store appends nothing.
A decision no version protects: a lock on a business key
Section titled “A decision no version protects: a lock on a business key”Optimistic concurrency compares the version of a row that exists. Counting the bookings of a
slot before inserting one, or giving the next number of a sequence per tenant, decides on rows
that are not there yet: two units of work read the same count and both write. The four ORM
packages give the same two helpers for it. advisoryLock(context, key, { tenant: scope })
waits until no other transaction holds the lock on key, then holds it until the unit of work
commits or rolls back (pg_advisory_xact_lock); tryAdvisoryLock answers false instead of
waiting. The key is a text PostgreSQL hashes into 64 bits (hashtextextended), prefixed with
the tenant of the work when tenant is given, so two tenants never wait for each other; two
keys of the same hash wait for each other and nothing else happens. Outside a unit of work the
lock would be released at once, and the helper refuses (AdvisoryLockOutsideUnitOfWorkError).
They are functions of the adapter, not a port of the kernel: a use case imports no ORM
package, so the lock sits in the repository method that needs it, or behind a port of the
context whose fake does nothing. Take it first in the unit of work and keep the default
isolation (read committed), under which the read that follows sees what the previous holder
committed. tenancy/scoped-statement accepts the helper and reports a raw
pg_advisory_xact_lock. PostgreSQL only; advisoryLockContract holds the four packages to it,
the wait itself on a real server, since PGlite is one session.
Comparison
Section titled “Comparison”Versions checked on 2026-10-10 against the npm registry.
| Drizzle | Knex | Prisma | TypeORM | |
|---|---|---|---|---|
| What it is | typed SQL builder with schema in TypeScript | SQL query builder | client generated from a schema file | ORM, data mapper or active record |
| Version | 0.45.4 stable; a 1.0 release candidate is published (rc tag) |
3.3.0 (June 2026) | 7.10.0 is the last 7.x; the npm latest tag pointed at 8.0.0-rc.22 on the day of the check |
1.1.2 (0.3.x kept under legacy) |
| Licence | Apache-2.0 | MIT | Apache-2.0 | MIT |
| Weekly downloads | about 27 million | about 6 million | about 19 million | about 5 million |
| Type safety of queries | inferred from the table definitions | weak: types are annotations you write | from the generated client | from entity definitions; query builder strings are unchecked |
| Transactions | callback; savepoints | callback or manual; savepoints | interactive transactions, bounded in time (5 s by default) and holding a connection | QueryRunner or callback |
| Row locking | in the builder | in the builder (forUpdate().skipLocked()) |
none in the client: raw SQL | in the query builder |
| Migrations | generated from the schema diff by drizzle-kit, SQL files | hand-written JavaScript, up and down | generated from the schema diff, SQL files | generated from entities, or hand-written |
| Raw SQL | sql template, table objects interpolated |
first class: it is a query builder | $queryRaw, typed SQL files |
query() |
| Runtime weight | library only | library only | generated client plus a driver adapter | library, reflect-metadata with decorated entities |
| Decorators | none | none | none | optional: the kit uses EntitySchema, no decorator |
Reading the table for this architecture: the ORM features that matter least are the ones ORMs advertise most. Lazy relations, identity maps, cascades and active records have no use when an aggregate is loaded whole and mapped by hand; what matters is honest SQL, a transaction that can be made ambient, row locks for the outbox relay and migrations you can read.
Selection criteria
Section titled “Selection criteria”- Team knowledge and existing schema. A running application on one of the four keeps it: the domain does not care.
- How much raw SQL you expect. Constraints, partial indexes, read models with window functions: Knex and Drizzle stay closest to SQL.
- Type safety of read models. Query handlers may bypass aggregates and read projections through a port; typed queries pay off there.
- Transaction length. Prisma's interactive transactions are bounded in time by default.
- What the kit generates for it. Tenant scoping is generated on the four; the SQL audit trail is not available for all four (below).
- Version currency. Prefer the current stable line; on the day of the check Prisma's npm
latesttag carried a release candidate, so pin the version you tested.
What this kit supports and verified
Section titled “What this kit supports and verified”Common to the four packages (drizzle,
knex, prisma,
typeorm): a unit of work whose transaction repositories
never see, where a nested run joins the outer transaction and the domain events are
dispatched at the end of the outermost run, before its commit; an outbox store whose
claimBatch leases due rows so several relays share the work and a dead relay's rows come
back; a processed-event store whose mark commits with the handler's effects; the standard
audit columns and tenant_id; cursor and offset pages. The units of work pass
unitOfWorkContract, the stores outboxStoreContract and processedEventStoreContract; your repositories are held to repositoryContract next to
their in-memory fake. Delivery through the outbox is at least once and unordered.
Tenant isolation is uneven across the four: shared tables on each of them (tenantTable,
tenantCondition, tenantWhere, read models with tenant, the outbox keeping the tenant of each
event), and beyond that Knex ships the three other strategies (row-level security, schema per
tenant, database per tenant), Drizzle row-level security, Prisma and TypeORM nothing more. The
table, and the tenantIsolationContract each strategy passes, are in
Multitenancy.
For the read side, each of the four also ships a translator of the kernel criteria into its
query (criteriaToDrizzle, criteriaToKnex, criteriaToPrisma, criteriaToTypeOrm) and a
read model store for projections, held to criteriaContract and readModelStoreContract on
PostgreSQL; neither was run on MySQL or SQLite. The CLI does not generate them yet: see the
read side proposal for the status per part.
For event-sourced aggregates, each of the four runs the PostgreSQL event store of the kernel
(createKnexEventSourcing, createDrizzleEventSourcing, createPrismaEventSourcing,
createTypeOrmEventSourcing): the streams, the snapshots, the checkpoints of the subscriptions
and the keys of the data subjects, with the tables declared the way each ORM migrates
(createEventStoreTables, eventStoreTables, the models of
prisma/event-store.postgresql.prisma, eventStoreEntities). Each is held to
eventStoreContract and eventStoreUnitOfWorkContract on PGlite in the unit run; knex, Prisma
and TypeORM also passed them on PostgreSQL 17 by hand. Not provided on MySQL or SQLite. When to
choose it: Event sourcing, per aggregate.
Per database
Section titled “Per database”| Drizzle | Knex | Prisma | TypeORM | |
|---|---|---|---|---|
| PostgreSQL | automated: contract suites on PGlite (in process); works with node-postgres, postgres-js, PGlite, Neon drivers | automated on PGlite over the wire protocol, and on a real server when a URL is given (last run: PostgreSQL 18): contracts, rollback, nested unit of work, concurrent claims | same as Knex, through @prisma/adapter-pg, both claim strategies |
same as Knex |
| MySQL 8 | not provided: the package is PostgreSQL only | by hand, once, against 8.4: outbox and processed-event contracts, rollback of append |
by hand, once, against 8.4 through @prisma/adapter-mariadb |
by hand, once, against 8.4 |
| SQLite | not provided | automated, in the unit run: outbox and processed-event contracts on an in-memory database (better-sqlite3); no SKIP LOCKED, no schemas |
by hand, once, outbox contract only; the processed-event store needs a custom delegate | by hand, once; no SKIP LOCKED, no schemas |
| MariaDB, CockroachDB, SQL Server, Oracle | not provided | never run | CockroachDB, SQL Server never run | never run |
| MongoDB | not provided | not applicable | never run | never run |
| Library version tested | not stated in the README | not stated | Prisma 7.10; the peer range admits 6, on which nothing was run | TypeORM 1.1; the peer range admits 0.3, on which nothing was run |
"By hand, once" is the READMEs' own wording: those suites are not in CI, so a regression on MySQL, or on SQLite outside the Knex stores, would not be caught by the kit.
What the generator and the other packages add
Section titled “What the generator and the other packages add”From packages/cli/README.md and
packages/audit/README.md:
- The generated persistence of the four ORMs is written for PostgreSQL.
customstarts on in-memory adapters held to the contract suites, for you to replace. generate repository --tenant-scoped, and every repository of a project initialised with--tenancy shared-table, is implemented for the four ORMs; withcustomor no ORM the regular adapter is written and a note says what to add, andinitrefuses the strategy.- The SQL audit trail exists for the four ORMs, on PostgreSQL only; the append-only guard is
created by the first migration on Knex, and on Drizzle, Prisma and TypeORM
npm run db:generateadds its statements to the migration that creates the audit tables, which the tool of the ORM cannot write (npm run db:audit-guardprints them for a migration written by hand). Withcustomor no ORM the generated project starts on an in-memory trail behind aTODO(platform). - Fast adapter specs run on PGlite; Docker Compose provides the real server.
- The erasure of a data subject from the tables declared with
personalFieldsexists on the four ORMs (KnexPersonalDataErasure,DrizzlePersonalDataErasure,PrismaPersonalDataErasure,TypeOrmPersonalDataErasure), under one contract suite; the generator does not write the declarations yet (privacy by design).
PostgreSQL versus the others
Section titled “PostgreSQL versus the others”| Database | Position in this kit | What you lose or must check |
|---|---|---|
| PostgreSQL | the default, and the only one in the automated suites of every adapter | nothing |
| MySQL 8 | stores run by hand once (Knex, Prisma, TypeORM) | no generated persistence, no SQL audit trail; DATETIME without time zone under Knex; no SKIP LOCKED on 5.7; one schema per context becomes one database or a table prefix |
| SQLite | Knex stores automated in the unit run, the others run by hand once | no schemas, compare-and-set claim, single writer: tests and tools, not several instances |
| MongoDB, others | no adapter | stack.orm: custom: your own unit of work (its run built on withinUnitOfWork of the kernel), outbox store and processed-event store, each passing the contract suites; without multi-document transactions the outbox guarantee is not available |
stack.database accepts postgres, mysql, sqlite, mongodb and none
(CONFIG.md). init refuses anything but postgres with one of the four
ORMs: the other values go with --orm custom, where they record a choice and select no
package. init --database mongodb is accepted with --orm custom although the usage line of
--help does not list it.
Limits and when not to use it
Section titled “Limits and when not to use it”- Ordering. No store orders events, not even per aggregate; see delivery and idempotency.
- Prisma. No row locking in the client (one raw
SELECT ... FOR UPDATE SKIP LOCKED, or the compare-and-set claim);claimmust be chosen by you because the client does not reveal its database; interactive transactions time out; no partial index in the schema language;stats()is three queries. - TypeORM. An
EntitySchemais static: column types follow thedialectyou pass.synchronize: trueis for tests only. Ajsonbfield of theColumnstype isJsonDocumentof@ddd-ts-kit/typeormor a named interface:Record<string, unknown>does not compile in the generatedinsertIgnoringConflictandupdate:QueryDeepPartialEntityof TypeORM refuses it. - Knex. The payload is serialized with
JSON.stringify; MariaDB would return it as text. The same goes for ajsonbcolumn of your own:pgwrites a JavaScript array as a PostgreSQL array literal and a string as it is, so an array or a string fails with22P02 invalid input syntax for type jsonwhere Drizzle, Prisma and TypeORM serialize it.jsonColumn(value)of@ddd-ts-kit/knexanswers the JSON text the column reads, whatever the value: the mapper writes it for such a value (an object passes either way). - Drizzle. Never name a table in raw SQL: interpolate the table object so the schema qualification follows (persistence skill). The audit package notes that Drizzle prints the parameters of a failed statement in its error message: log the code, not the message.
- All. Migrations are forward-only and compatible with the version still running (expand, migrate, contract). The kit provides table definitions for each tool's own migration tooling; it runs no migration of its own.
When not to use an ORM adapter at all: a context with no state (a pure translator), or a read model better served by a search engine (below) or a cache, behind a port of its own.
A read model in a search engine: OpenSearch
Section titled “A read model in a search engine: OpenSearch”A read model searched by many criteria over many rows, or one that several services read, may live
in OpenSearch rather than in a table: @ddd-ts-kit/opensearch implements the same
ReadModelStore port as the four ORM, so a projector does not know which one it writes to. The
criteria of the read port become the query DSL, a write is applied only if its event is newer and
only on the document it read, and the tenants are kept apart by an index each
(tenancy: { strategy: 'index' }) or by a tenant field and an alias per tenant that OpenSearch
filters itself ({ strategy: 'attribute' }). It speaks the REST API with no client library.
| A table of an ORM | OpenSearch | |
|---|---|---|
| Consistency | the row commits with the processed-event mark of the event | eventually consistent: a search sees a write after the next refresh (one second by default), refresh: 'wait_for' waits for it; the write is outside the transaction, and a redelivery is stale |
| Tenants | a tenant column, or a schema or a database per tenant | an index per tenant, or one index and a filtered alias per tenant |
| Rebuild | ProjectionRebuild, on PostgreSQL |
not built yet; each index carries a generation and every read goes through an alias, so that a rebuild can switch |
| Full-text search | the full-text search of PostgreSQL, by hand | not built: a string is a keyword, contains a case-sensitive wildcard |
| Operations | the database the project already runs | a cluster to run, size and upgrade |
init --search opensearch wires the package in the platform: what fits it and what does not, how
a context writes and tests its store and keeps its tenants apart are in
Search read models. Its
README shows the composition by hand, and
ADR-0008 records each choice and what
reverses it. It was run on OpenSearch 3 only; the endpoints it calls are the ones Elasticsearch
shares, which no spec has proven.
Migrations: names, merges and order
Section titled “Migrations: names, merges and order”Several people add migrations at the same time, on one context or on several. Every migration
a generated project writes is named <timestamp>_<what-it-does>, and npm run db:generate
refuses to run without the description: two branches never write the same file. It refuses a
description a migration of the folder already carries too, and names that migration, on the four
tools: two migrations of one name read as one in a review, and verify-merge knows a migration
by its description.
| Tool | db:generate |
Writes | A migration merged older than one already applied |
|---|---|---|---|
| drizzle-kit 0.31 | ddd-ts-kit drizzle-generate --name, which runs drizzle-kit generate --name (migrations.prefix: 'timestamp' in drizzle.config.ts) |
migrations/20261012093000_add-invoices.sql, its snapshot meta/20261012093000_snapshot.json, one entry of meta/_journal.json |
skipped without a word: the migrator applies the entries newer than the last one recorded |
| knex 3 | npm run build, then ddd-ts-kit knex-generate --name, which names the file with knex migrate:make and writes the difference between createTables and the migrations in it |
migrations/20261012093000_add-invoices.js |
applied: knex runs every file it has not recorded |
| Prisma 7 | ddd-ts-kit prisma-generate --name, which runs prisma migrate dev --create-only --name |
prisma/migrations/20261012093000_add_invoices/migration.sql (Prisma turns - into _) |
applied by migrate deploy, which runs every migration it has not recorded (its documentation; not measured here) |
| TypeORM 1.1 | ddd-ts-kit typeorm-generate, which runs typeorm migration:generate -d <data source>, given the path: npm run db:generate migrations/add-invoices |
migrations/1791829645467-add-invoices.ts (milliseconds, and a -: TypeORM fixes both) |
applied: TypeORM runs every migration it has not recorded |
With no DATABASE_URL in the environment, Prisma and TypeORM need no server: the command starts
PostgreSQL in process (PGlite over @electric-sql/pglite-socket, as openTestDatabase() does),
replays the migrations of the project on it (prisma migrate diff --from-migrations, with the
database as its shadow; typeorm migration:run), diffs the schema against it and writes the new
migration, audit guard included. A sandboxed agent therefore generates its own migrations. With
DATABASE_URL set, the tool uses that server as before. On TypeORM, npm run build comes first
(the data source reads the compiled migrations), and db:migrate runs it itself, so that it never
answers that nothing is pending with a migration not built yet; a Prisma project reads
SHADOW_DATABASE_URL in prisma.config.ts, which init writes.
Knex has no schema diff, and never needs a server to generate: ddd-ts-kit knex-generate starts
two PostgreSQL in process, runs the compiled createTables on one and the migrations on the other,
then each statement of createTables on the migrated side. A statement that answers that its object
exists is left out, the others are written in the migration, after an add column for a column
missing from a table the migrations created. The migration holds this SQL and calls nothing of the
application, so it builds the same tables whatever createTables becomes, and the history replays
on a fresh database. Nothing different, nothing is written, as on the other three. A column changed
or dropped, a table dropped, and an index, a constraint, a trigger, an enum, a function or a view
changed under its name are listed as a TODO(domain) of the migration, to write by hand: objects are
compared by the definition PostgreSQL gives of them. A statement of createTables that changes rows or
removes something is never written, since a migration runs on a database that holds data: it is a line
of the command and a TODO(domain) of the next migration. Any other statement, row security or a
comment, goes in with the table or the column it belongs to. npm run db:generate -- <name> --custom
(pnpm run db:generate <name> -- --custom too) writes the empty migration of knex, for a change of data
or a statement written by hand.
db:migrate finds DATABASE_URL in the shell, else in .env: knexfile.js, prisma.config.ts and
the TypeORM data source load the file, since those three CLIs do not, and drizzle-kit reads it itself.
The command takes the description after the script: npm run db:generate add-invoices
(npm run db:generate -- audit-guard --custom for a hand-written drizzle-kit migration). With
an audit trail, the commands of the kit add the statements of its append-only guard to the
migration that creates the audit tables, once: a project whose migrations hold them is left as it
is.
Two migrations kept apart. A tool that generates from the schema writes, in one migration,
the difference between the schema files and the last migration: two changes made before one
db:generate come out as one migration. When they have to stay two (a new table, then a
constraint once it is filled; a column added, then the old one dropped in a later deployment),
change the schema in two steps, with a db:generate after each: make the first change, run
npm run db:generate add-due-dates, then make the second and run
npm run db:generate require-due-dates. Already generated as one and not merged yet: delete it
(under drizzle-kit, its .sql file, its snapshot under meta/ and its journal entry), undo the
second change, and take the two steps.
Without a terminal. When a change of the schema could be a rename (a column or a table gone
and another one added), drizzle-kit asks on a terminal whether it is created or renamed.
Measured with drizzle-kit 0.31.11 (2026-10-15): without a terminal, as an agent or a pipeline
runs it, it prints Interactive prompts require a TTY terminal, writes nothing and exits 0;
under a pseudo-terminal (script -qec) it asks and waits for an answer nobody gives. It has no
option to answer in advance. So the script goes through ddd-ts-kit drizzle-generate: in a
terminal it is drizzle-kit generate as is; without one, that output, and the forked snapshot
below, become an error that names the fix (exit code 2). The fix is a change that cannot be
read two ways: add the new column in one migration and drop the old one in a later one, or
write the statements in a custom migration. Prisma 7 does not wait either: where
prisma migrate dev would ask (a warning of data loss), it stops with an error in a
non-interactive environment (read in its code, not measured); knex and TypeORM ask nothing.
A changed primary key. drizzle-kit can write the statement that adds the new primary key of a
table before the one that drops the old key, which fails on the database (a table has one primary
key), or drop a column of the old key before the statement that drops the key, which then fails
because the column took the key with it; not measured here. So ddd-ts-kit drizzle-generate
reads the SQL it has just written and warns, exit code unchanged, with the file, the two
statements and the fix: drop the old key first, by reordering the statements of that new
migration, which is still unapplied, or write the migration with --custom. It reads the
ALTER TABLE statements of PostgreSQL: a dropped constraint is a primary key when the snapshot
before the migration records it, or when its name ends in _pkey (the name PostgreSQL gives a
key) or _pk (the one drizzle-kit gives a composite key); the columns of a key come from that
snapshot, else from the name drizzle-kit gives a composite key. A key of another name that the
snapshot does not record, or a statement written in another form (DROP of a column without
COLUMN, a DO block), is not seen: read the SQL of such a migration before committing it.
The warning scrolls away with the output; the rule persistence/primary-key-order of
ddd-ts-kit check (a warning, as a new rule is) reads the same statements in every .sql file
of the migrations folder and reports the migration, on the line of the statement that runs too
early, with the same fix, until it is fixed (ddd-ts-kit check --rule persistence/primary-key-order
lists them).
Formatted as the project. drizzle-kit writes the snapshot and the journal under meta/ in
its own layout, which the format gate of a project can refuse. Once a migration is written,
ddd-ts-kit drizzle-generate formats the JSON files it wrote under meta/ with the formatter
the format script of package.json runs, Biome or Prettier, as installed in the project, given
those paths only (the script itself would format the whole project); the SQL stays as drizzle-kit
wrote it, and a path the configuration of the formatter ignores is passed over (the biome.json
that init writes ignores migrations/meta). It says what it formatted; without such a script,
or when the formatter fails, it says so, and the migration stays written.
init writes no knex migration: npm run db:generate initial writes the first one, as on the
other three. An older project keeps its 00000000000000_initial.js (0001_initial.js before 0.5),
since an applied migration is never renamed, and its content moves to SQL: the changelog says how.
Measured with drizzle-kit 0.31.11 and drizzle-orm 0.45.4 (2026-10-12), two copies of one project each generating a migration, as two branches would:
- with the former default (
prefix: 'index'), both write0001_<random words>.sqlandmeta/0001_snapshot.json: the snapshot conflicts as a file added twice; - with
prefix: 'timestamp', the files and the snapshots no longer collide, butmeta/_journal.jsonstill conflicts (each branch appends an entry at the same place), and once merged by hand two snapshots name the same parent:drizzle-kit checkexits 1 anddrizzle-kit generateprints the collision and writes nothing (with exit code 0, whichddd-ts-kit drizzle-generateturns into exit code 2); - worse, a database that applied the later migration first (the other branch was merged and
deployed before) skips the earlier one for good: drizzle-orm's migrator applies only the
entries whose
whenis newer than the last one it recorded. Measured on PGlite: afteradd-payments, then the merge ofadd-invoicesgenerated three seconds before it, the database hadaccounts, paymentsand noinvoices, without an error.
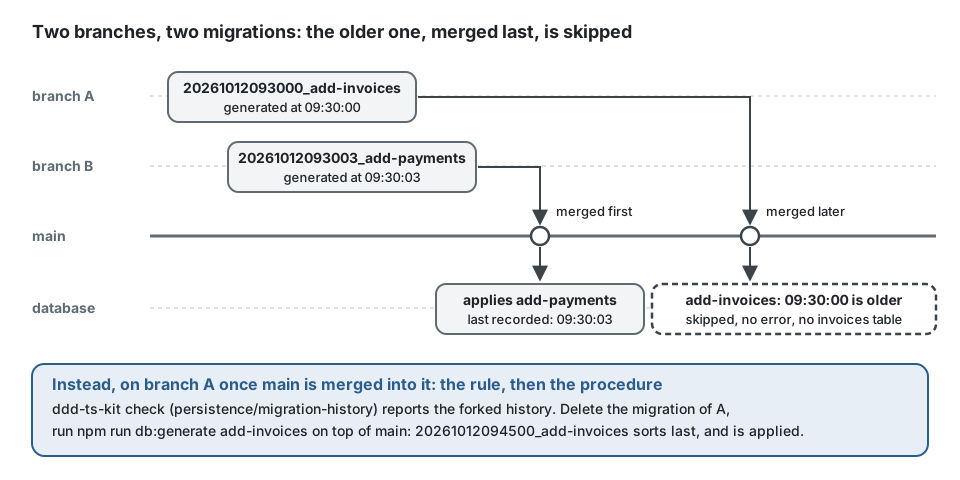
The kit's answer is the rule persistence/migration-history of ddd-ts-kit check (so
npm run check:arch, the guard of the plugin and the pipeline): every migration starts with the
number that orders it and no two share one; under drizzle-kit, the journal and the .sql files
match, the entries keep the order they were generated in, and each snapshot follows the one
before it. On the measured merge it reports the forked snapshot; on a journal merged in the
order of the branches it also reports the entry out of order.
After a merge or a rebase that brought a migration from the main branch, while yours is not merged yet:
- take the migrations of the main branch as they are (
.sqlfiles, snapshots, journal); - delete yours: its
.sqlfile, its snapshot undermeta/and its entry of the journal (drizzle-kit), or its file or directory (the other tools); - run
npm run db:generate <what-it-does>again: it is generated on top of the main branch, with a later timestamp; npm run check:archreports nothing, and the branch is merged before another migration lands, or the steps are repeated.
npx ddd-ts-kit merge-trunk does steps 2 and 3 as it brings the main branch in: when both
sides added a migration since its base, it takes the journal and snapshots of the main branch and
runs the replay below itself; a refusal of the replay stops the merge with its fix. With
--to-land, which the conductor runs just before the squash merge, the migrations of the branch
the main branch does not have get their real names: replayed under drizzle-kit (the working-
prefix goes, in the worktree of a worker too), renamed under knex, Prisma and TypeORM (a number
after the last one of the main branch, without working-, the content kept; TypeORM's class and
name follow, Prisma's folder). When a migration the main branch gained since the base and one
of the branch change the same table, their order is a decision: the merge stops and says to
generate the branch's again on the main branch (npm run db:generate <what-it-does>).
Under drizzle-kit, ddd-ts-kit drizzle-generate --replay does steps 2 and 3 on its own too,
on the branch once the main branch is merged into it without merge-trunk:
git merge origin/main # meta/_journal.json conflictsgit checkout origin/main -- migrations/meta/_journal.json # the journal of the main branchnpx ddd-ts-kit drizzle-generate --replay # --base <ref>, origin/main by defaultIt compares the .sql files of the migrations folder with those of --base: the ones the base
does not have are the branch's. When the history on disk does not fork (the journal lists every
file in the order they were generated, each snapshot from the one before, so the branch's
follow the last migration of the base), it generates nothing: it only renames a migration whose
name changes (working- dropped, below), its number, snapshot and statements kept, and says so.
Otherwise it deletes them, with their snapshots and their journal entries (the journal becomes
the one of the base, whose last snapshot is then the parent of what follows), generates each
again on top, in their order and under their names, and says what it deleted and generated. A
custom migration (its snapshot repeats the one before it) is generated again with --custom and
gets its statements back. It refuses, with the fix: a journal that still holds conflict markers
(take the one of the base, as above: the replay finds the migrations of the branch by their
files), a base with migrations the branch has not merged, and two migrations of the branch that
change the schema: drizzle-kit generates the difference between the schema files and the last
snapshot, so it cannot split the changes of a branch again into the steps they were, and one
migration in their place would join steps planned apart (a table, then a constraint once it is
filled, fails on a database that holds rows). The fix generates them again by hand, one at a
time and in their order, as "Two migrations kept apart" above says: delete
them, undo every change of the branch in the schema files but the first one's, run
npm run db:generate <its name>, bring back the next change and run it again (git show <commit>:<schema file> holds the schema of each step). It also refuses a generated
migration whose statements drizzle-kit now writes otherwise: its SQL was edited by hand (a key
reordered, an index added), or the base changed what it changes. Generating it again would lose
that, so it puts the migrations folder back as it found it and says which statement differs;
the fix is to generate that migration on top of the base by hand and write the edits again
(git show HEAD:<file> holds them), after which a replay finds nothing forked. The replay is
Drizzle's: under knex, Prisma and TypeORM, which keep no journal, merge-trunk --to-land renames
the migrations, and generating one again after an overlap stays by hand.
Measured with drizzle-kit 0.31.11, drizzle-orm 0.45.4 and PGlite 0.5.10 (2026-10-18), the
real drizzle-kit on a TypeScript schema: a branch adds a table while the main branch adds
another, the branch merges it and takes its journal, drizzle-generate --replay --base main
generates the branch's migration again on top with the same statements, and drizzle-kit migrate
applies the three migrations to an empty database; the same with each side adding a column to
one table. A second replay says nothing is forked. A migration of the branch with an index added
by hand is refused, and the folder is as before the replay.
npx ddd-ts-kit verify-merge, run after the merge, reports a migration of either side that the
result lost. It knows a migration by its description, its name without its number and without
working-: a migration generated again under another number, or without the prefix, is kept.
A migration that does not follow the trunk's fails verify-merge. A branch that lives more
than a day holds a migration generated before the last one the trunk gained meanwhile. Without a
<commit>, npx ddd-ts-kit verify-merge also reads the migrations of the working tree against
the trunk (the base of the worker, else origin/HEAD, else origin/main, as git knows them:
fetch first) and fails, naming the migration and the last one of the trunk. --warn, which the
pre-push hook passes, softens what a merge lost and never this: the push stops.
| Tool | What it reports | What brings the order right |
|---|---|---|
| drizzle-kit | an entry the branch adds to the journal whose when is not after the last entry of the trunk's journal, which the migrator would skip; a .sql file no entry of the journal lists and the trunk does not hold, as after a merge that kept the journal of one side (one the trunk holds too is the trunk's to list) |
npx ddd-ts-kit merge-trunk, which replays as it brings the trunk in. Once the trunk is merged otherwise: the meta/ of the trunk, then npx ddd-ts-kit drizzle-generate --replay --base <trunk> (or merge-trunk --to-land, which does it at the landing). The replay refuses a branch with two migrations that change the schema: they are generated again by hand, one at a time, as above |
| knex, Prisma, TypeORM | a migration the branch adds whose name sorts before the last migration of the trunk: the tool would run it after that one where it is applied, and before it on a new database | npx ddd-ts-kit merge-trunk --to-land, which renames it after the last of the trunk as it brings the trunk in. On a branch that already holds the trunk there is nothing to merge: it renames all the same, only the migrations that do not follow the trunk's already, in their order, and leaves the rename to commit. It stops, nothing renamed, when the migration and a later one of the trunk change one table: delete that migration first (git show HEAD:<file> keeps what was written by hand), then npm run db:generate <what-it-does>, which refuses a name while a migration carries it |
A working migration (working-<what-it-does>) is left out: its place is decided when the branch
lands, and persistence/migration-history already refuses it on the trunk. What is ordered is
what the tool itself takes for a migration, by what it orders it by: under knex every script of
migrations/, by its name (knex loads them all, whatever their name); under Prisma the folders
that hold a migration.sql, by their name; under TypeORM the classes whose name ends with 13
digits, by that number, however the file is named. verify-merge and merge-trunk --to-land
read the same order. Nothing is compared for a named commit, without the config of the kit, or
when no ref names a trunk.
A database that already applied the old name. A migration renamed or generated again is a new one for the tool, on a database of development, of a preview or shared that applied it under its old name. Reset that database, or correct what it recorded:
| Tool | What happens there | What to correct |
|---|---|---|
| drizzle-kit | the migrator runs the migration again | drizzle.__drizzle_migrations: add a row whose created_at is the when of the new entry of the journal, with any hash (the column is required and never compared) |
| knex | every migrate is refused: The migration directory is corrupt, the following files are missing |
knex_migrations: set name of the row to the new file name, extension included |
| Prisma | it still knows the migration by the old name | record the new name as applied: npx prisma migrate resolve --applied <new name> |
| TypeORM | it runs the migration again | migrations: correct timestamp, and name, the class |
The knex and TypeORM lines are read in the code of the two tools; the Prisma command is the one its CLI documents, and what Prisma then does with the old row was not verified here.
merge-trunk --to-land says so each time it renames or replays, and so does the fix of
verify-merge. --to-land --dry-run on a branch that already holds the trunk says which
migrations would move and moves nothing. A landing that stops there leaves the migrations folder
as it found it, under drizzle-kit too, whose replay deletes before it generates: the same command
runs again once the cause is fixed. A rename never takes a number a file of the folder carries
already: it takes the next free one, the order kept. When the last migration of the trunk carries
no number a migration can follow (a helpers.js in the folder of knex, which knex would load as a
migration and fail on), the landing stops and says to move that file: no rename can sort after it. Read in the code
of the four tools, and run here on git repositories with the files of each; not measured against
a database.
A migration already merged on the main branch is never edited or regenerated: a correction is a new migration.
In a parallel build, a worker whose slice changes the stored state generates a working
migration in its worktree, npm run db:generate working-<what-it-does>, so that the specs of its
branch run against the tables they need; the guard refuses it any other migration. The name is
the marker because every tool above keeps it after its number (20261015101500_working-add-claims.sql,
20261015101500_working_add_claims/ under Prisma, 1791829645467-working-add-claims.ts under
TypeORM): the migrator applies it like any other, and nothing in the configuration of the tool
changes. persistence/migration-history accepts it where the worker scope file
.ddd-ts-kit/worker.json exists, and reports it everywhere else. When the conductor merges the
branch under drizzle-kit, npx ddd-ts-kit drizzle-generate --replay (the trunk before the merge
as --base) deletes the working migration, with its snapshot and its journal entry, and
generates it again on the trunk, after the branches merged before it, under its name without
working-; the conductor commits the real migration with the merge. In the worktree of a worker,
which merges the trunk into its branch, the replay keeps the prefix. With pull requests merged by
squash, the conductor runs npx ddd-ts-kit merge-trunk --to-land --cwd <worktree> before the
squash instead: the migration gets its real name on the branch, under every tool (replayed under
drizzle-kit, renamed under the others), and lands with it; the guard refuses --to-land to a
sub-agent. A migration of the branch and one the trunk gained on the same table stop it: the
conductor generates that one again on the trunk with npm run db:generate <what-it-does>.
Not chosen: one migrations folder per context. drizzle-kit can run one config per context
(its own schema, out and migrations table), so it would work, but it solves the wrong half:
two people on one context still collide, the platform tables (outbox, audit trail) belong to no
context, and db:migrate would become an ordered list of commands to keep in step with the
config. The timestamp, the rule and the procedure above cover a single folder and a team
working on one context alike. A context extracted as a service takes its tables with it then
(generate service).
What a migration left undone, before a deployment. The order above is read from the files;
what the migrations make of the read model tables is read from a database. npm run db:read-models reads, on the database DATABASE_URL names, the read model tables the application
lists, each by its own store (-- --context <context>, once per context, for the tables of those
contexts alone, as a context run as a service checks them on its database): it prints the
database it read, those of its tables that cannot hold the trace of a deleted row, with the
migration each needs, and exits 1 (2 without a database to read, 3 when no table could be read,
4 when --context names a context no listed read model belongs to).
A table is read only when its store is listed: ddd-ts-kit check reports a store written by hand
that the list does not answer for (persistence/read-model-listed).
The application makes the same check when it starts, of the contexts it hosts, so a table an
upgrade left as it was stops the start and not the first event that reaches it
(Every table checked at the start, and before a deployment).
A large read model table: the second step apart
Section titled “A large read model table: the second step apart”The migration a refusal writes has two steps. The first changes the definition in one statement
and takes ACCESS EXCLUSIVE on the table, which stops its readers and its writers until the
transaction ends. The second validates the check constraint and empties the rows deleted before:
it reads the whole table. In the transaction of the first it runs under that lock; outside it,
under SHARE UPDATE EXCLUSIVE and ROW EXCLUSIVE, which stop neither readers nor writers. On a
small table, write both steps in one migration. On a large one, the second step goes in a
migration of its own, and what puts it outside the transaction of the first differs by tool. Each
line below was run on PostgreSQL 18 with the versions the kit installs, the locks read in
pg_locks while the second step ran:
| Tool | What it does with the pending migrations | The second step outside the transaction of the first |
|---|---|---|
knex 3 (knex migrate:latest) |
runs them all in one transaction: a second file still holds ACCESS EXCLUSIVE | the second migration ends with export const config = { transaction: false }; (exports.config in CommonJS): knex then runs the migrations one by one, and that one statement by statement. |
TypeORM (typeorm migration:run) |
one transaction for all (migrationsTransactionMode: 'all', the default) |
migrationsTransactionMode: 'each' in the data source (data-source.ts): each migration has its transaction, and the second step holds SHARE UPDATE EXCLUSIVE and ROW EXCLUSIVE alone. transaction = false on the migration class is refused under 'all' ("override the transaction mode") and works under 'each' |
Drizzle (drizzle-kit migrate) |
one transaction for every pending file, and no setting changes it (read on migrate() of drizzle-orm 0.45, which the command calls) |
the second file is applied by a later run: deploy the first migration, then add the second and migrate again; or run the second step by hand (psql) once the first is applied |
Prisma 7 (prisma migrate deploy) |
commits each statement of a file, except a file that holds a do block, which it sends in one piece: the first step holds one, so a file with both steps is one transaction |
two migrations: the second, plain statements, holds no lock on the table between them. A statement that fails in a file of plain statements leaves the statements before it applied and the command fails: the statements of the second step can be run again |
Recommendation by situation
Section titled “Recommendation by situation”| Situation | Choice |
|---|---|
| New project | Drizzle on PostgreSQL: the default, typed queries, SQL migrations, tenant scoping and SQL audit trail generated |
| SQL-first team, many hand-written queries, or an existing Knex code base | Knex on PostgreSQL: the "first-class stack" proven end to end by the CLI uses it |
| Existing Prisma schema | Prisma 7, with the limits above understood; plan the audit trail store yourself |
| Existing TypeORM application | TypeORM 1.x with EntitySchema; plan the audit trail store yourself |
| MySQL imposed | Knex or TypeORM, and run the contract suites against your server in your own CI |
| Another store | custom, behind the same ports, with a decision record |
| A read model searched by many criteria, or read by several services | @ddd-ts-kit/opensearch behind the read model port, beside the ORM of the write model |
Sources
Section titled “Sources”- Drizzle ORM documentation: https://orm.drizzle.team/docs/overview ; drizzle-kit configuration,
migrations.prefix: https://orm.drizzle.team/docs/drizzle-config-file - drizzle-kit 0.31.11 (
prepareMigrationMetadata) and drizzle-orm 0.45.4 (PgDialect.migrate), knex 3.3.0 (MigrationGenerator,getNewMigrations), Prisma 7.10.0 (migrate dev --name), TypeORM 1.1.2 (MigrationGenerateCommand,MigrationExecutor): read in their published code on 2026-10-12. - Knex documentation: https://knexjs.org/guide/
- Prisma documentation, transactions: https://www.prisma.io/docs/orm/prisma-client/queries/transactions
- Prisma documentation, migrations in development and production: https://www.prisma.io/docs/orm/prisma-migrate/workflows/development-and-production
- TypeORM documentation: https://typeorm.io
- PostgreSQL documentation,
SELECT ... FOR UPDATE SKIP LOCKEDand exclusion constraints: https://www.postgresql.org/docs/current/sql-select.html , https://www.postgresql.org/docs/current/ddl-constraints.html - PGlite: https://pglite.dev
- npm registry: versions, dist-tags, licences and weekly downloads read on 2026-10-10.
- Martin Fowler, Patterns of Enterprise Application Architecture, Addison-Wesley, 2002: Data Mapper, Unit of Work, Repository, Optimistic Offline Lock.
- Not verified: that no version of the four libraries can declare a PostgreSQL exclusion constraint in its schema language; the latest stable Drizzle 1.0 date.