
@ddd-ts-kit/typeorm
TypeORM adapters of the kernel and events ports: a unit of work that repositories never see,
the transactional outbox store, the processed-event store, the background jobs and the instances
of the process managers, their tables as EntitySchema
objects, and one database schema per bounded context. Same pieces as @ddd-ts-kit/drizzle, for
projects on TypeORM.
npm i @ddd-ts-kit/typeorm typeorm pgEverything here uses EntitySchema, not decorated classes: no reflect-metadata import, no
experimentalDecorators, and rows stay plain objects that a mapper turns into aggregates.
PostgreSQL first; see Dialect coverage for MySQL and SQLite.
Where it sits in an application
Section titled “Where it sits in an application”Nothing here is imported from domain/ or application/. A handler depends on the repository
port of its domain; the adapter of that port, in infrastructure/, runs its statements on the
TypeOrmContext; the platform builds the unit of work once and binds it.
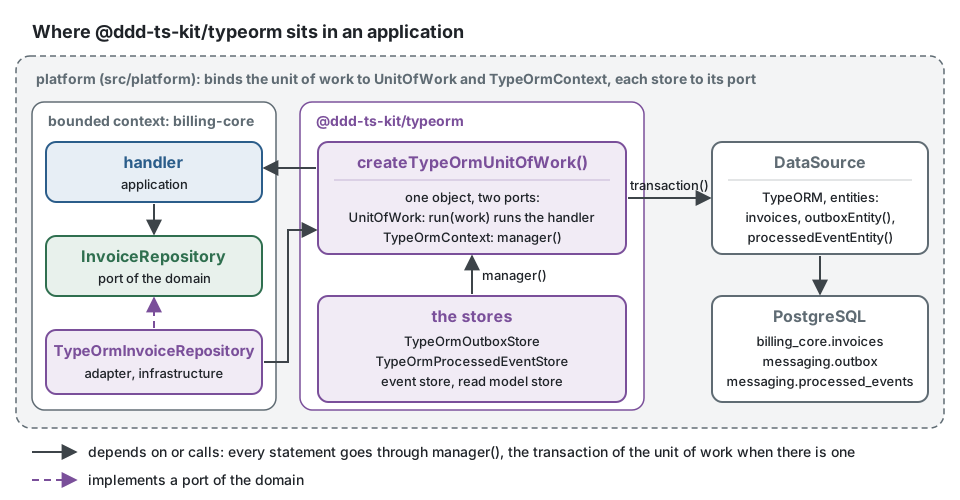
The one idea to keep: every statement goes through manager(). Inside a unit of work it
is the transactional EntityManager of that unit of work, so the row of the aggregate, the
outbox record of the event it published and the processed-event mark of a consumer commit or
roll back together. Outside one (a query, a script) it is dataSource.manager.
Schema
Section titled “Schema”The tables are EntitySchema objects: add them to the entities of the data source and
typeorm migration:generate writes their DDL into a migration of your project.
import { outboxEntity, processedEventEntity, schemaNameOf } from '@ddd-ts-kit/typeorm';
export const outbox = outboxEntity({ schema: 'messaging' }); // messaging.outboxexport const processedEvents = processedEventEntity({ schema: 'messaging' });
// contexts/billing-core/infrastructure/persistence/invoice-row.schema.tsimport { EntitySchema } from 'typeorm';
export interface InvoiceRow {  id: string;  amount: number;  status: 'draft' | 'issued';  version: number;}
export const invoices = new EntitySchema<InvoiceRow>({  name: 'Invoice',  tableName: 'invoices',  schema: schemaNameOf('billing-core'), // billing_core  columns: {    id: { type: 'text', primary: true },    amount: { type: 'int' },    status: { type: 'text' },    version: { type: 'int' },  },});
Options of both factories: schema (none: the default schema of the connection), dialect
(postgres by default, mysql, sqlite: it picks the JSON and timestamp column types),
tableName, and name, the entity name. The entity name defaults to OutboxRecord or
ProcessedEvent, suffixed with the schema (OutboxRecord_messaging), so each context can
register an outbox of its own in the same data source.
outbox is indexed for the relay (pending records by next attempt, partial index on
PostgreSQL and SQLite); processed_events has (consumer, event_id) as its primary key.
TypeORM does not create schemas: create them in the migration (CREATE SCHEMA IF NOT EXISTS).
Composition root
Section titled “Composition root”createTypeOrmUnitOfWork(dataSource) gives one object that is two ports: the kernel
UnitOfWork, and TypeOrmContext, the handle repositories and stores run their queries on.
Bind it to both:
import { DataSource } from 'typeorm';import { defineContextModule } from '@ddd-ts-kit/di';import { IntegrationEventPublisher, ProcessedEventStore, UnitOfWork } from '@ddd-ts-kit/kernel';import { OutboxPublisher, OutboxStore } from '@ddd-ts-kit/events';import {  createTypeOrmUnitOfWork,  TypeOrmContext,  TypeOrmOutboxStore,  TypeOrmProcessedEventStore,} from '@ddd-ts-kit/typeorm';
export const dataSource = new DataSource({  type: 'postgres',  url: process.env.DATABASE_URL,  entities: [outbox, processedEvents, invoices],});
const unitOfWork = createTypeOrmUnitOfWork(dataSource);
export const persistenceModule = defineContextModule({ name: 'persistence', register(builder) { builder.rebind(UnitOfWork).toValue(unitOfWork); builder.bind(TypeOrmContext).toValue(unitOfWork); builder .bind(OutboxStore) .toFactory((resolve) => new TypeOrmOutboxStore(resolve(TypeOrmContext), { entity: outbox })); builder .rebind(ProcessedEventStore) .toFactory((resolve) => new TypeOrmProcessedEventStore(resolve(TypeOrmContext), { entity: processedEvents })); builder.rebind(IntegrationEventPublisher).toClass(OutboxPublisher, [OutboxStore]); }, onStart: async () => { await dataSource.initialize(); }, onStop: () => dataSource.destroy(),});const app = createApplication({ modules: [kernelModule(), persistenceModule, contextModule('billing', billingDeclarations)] });
const relay = new OutboxRelay({ store: app.resolve(OutboxStore), publisher: broker, clock: app.resolve(Clock) });relay.start({ intervalMs: 500 });List the module after kernelModule(): rebind replaces its in-memory defaults. The command
bus of the kernel module runs every command in the bound UnitOfWork; handlers do not know it.
contextModule of @ddd-ts-kit/di turns the declared classes of a context into its module.
A project written by the CLI holds the same wiring in two files:
platform/database/persistence-over.ts builds the unit of work and the two stores once, and
platform/composition/platform.module.ts binds them, the outbox publisher being given to
kernelModule({ eventPublisher }).
Pass to a store the very entity the data source registers. Without entity, a store uses
outboxEntity() or processedEventEntity(), which TypeORM matches by name with the default
entity in the default schema; the class is then bound directly:
builder.bind(OutboxStore).toClass(TypeOrmOutboxStore, [TypeOrmContext]),
builder.rebind(ProcessedEventStore).toClass(TypeOrmProcessedEventStore, [TypeOrmContext]).
unitOfWork.run(work) opens dataSource.transaction and keeps the transactional
EntityManager in an AsyncLocalStorage; a nested run joins the outer transaction (no
savepoint). Because append uses the current manager, an event published by a handler that
then fails is rolled back with the business write: that is the whole point of the outbox.
createTypeOrmUnitOfWork(dataSource, 'REPEATABLE READ') sets the isolation level.
run is built on withinUnitOfWork of the kernel. The domain events of the aggregates saved
inside it wait until work has returned, then are dispatched inside the transaction, before
the commit: their handlers see every save, and what they write commits or rolls back with it.
If work, a handler or the commit fails, nothing is left: no row, no outbox record, no handler
run after the commit. Handlers declared after-commit run once the transaction has committed.
A nested run joins the unit of work in progress: one dispatch, at the end of the outermost.
A run called directly (a consumer, a script) has the same timing as a command.
unitOfWorkContract of @ddd-ts-kit/testing/contracts proves it, with a deferred constraint
for the commit that fails; on a real PostgreSQL (DDD_TS_KIT_TEST_DATABASE_URL) it also proves
that the rows of a before-commit handler are invisible from another connection and visible
to the after-commit handlers. The README of @ddd-ts-kit/kernel draws this timeline
(Domain events and the unit of work).
TypeOrmContext is an abstract class, so it is its own injection token. A project with two
data sources gives each a class of its own (export abstract class Ledger extends TypeOrmContext {}
in platform/database/) and binds each to its unit of work.
Repository
Section titled “Repository”The port lives in the domain, the adapter in infrastructure. A repository receives the context,
never a transaction: manager() is the transactional manager of the unit of work when there
is one and dataSource.manager otherwise.
import { Repository } from '@ddd-ts-kit/kernel';
export abstract class InvoiceRepository extends Repository<Invoice> {}import { Repository } from '@ddd-ts-kit/kernel/declarations';import { insertIgnoringConflict, optimisticUpdate, TypeOrmContext } from '@ddd-ts-kit/typeorm';
@Repository(InvoiceRepository)export class TypeOrmInvoiceRepository implements InvoiceRepository { constructor(private readonly context: TypeOrmContext) {}
async findById(id: string): Promise<Invoice | undefined> { const row = await this.context.manager().findOneBy(invoices, { id });
if (row === null) { return undefined; }
const invoice = Invoice.rehydrate(row); invoice.version = row.version;
return invoice; }
async save(invoice: Invoice): Promise<void> { const manager = this.context.manager();
await optimisticUpdate(invoice, async ({ expected, next }) => { const row = { ...invoice.state, version: next };
if (expected === 0) { return (await insertIgnoringConflict(manager, invoices, row)) ? 1 : 0; }
const updated = await manager.update(invoices, { id: invoice.id, version: expected }, row);
return updated.affected ?? 0; }); }}In the explicit style, without the decorator, the same binding is one line of
<context>.module.ts:
builder.bind(InvoiceRepository).toClass(TypeOrmInvoiceRepository, [TypeOrmContext]).
optimisticUpdate gives the version to expect and the version to write, raises a
ConcurrencyError (a DomainError with code CONCURRENCY_CONFLICT) when the guarded
statement wrote no row, and moves invoice.version on otherwise. insertIgnoringConflict
inserts unless the key exists and says whether it did; unlike a caught unique violation it
leaves the surrounding PostgreSQL transaction usable. It ignores a conflict on the primary key
alone (ON CONFLICT (id) DO NOTHING on PostgreSQL and SQLite, once a statement without a target wrote nothing): a row that takes a value
another row holds under a unique constraint (an email) is refused by the database, and
optimisticUpdate raises UniqueViolationError (code CONFLICT, 409), not a lost update; on MySQL, which has no conflict target and whose INSERT IGNORE skips that row too, the helper asks whether a row holds the key when nothing was written, and raises UniqueViolationError when none does. Two first saves of one aggregate made at once (a request delivered twice) are not refused for the unique value they both write: on PostgreSQL a conflict target on the key alone lets them meet on the other unique index first, so the helper inserts with a statement that skips on any unique value, and only when it wrote nothing with a second one that names the key. The one that lost writes no row, a ConcurrencyError. Do not use manager.save for an
aggregate: it reads before writing and decides by itself between insert and update, which
defeats the version guard. TypeORM's own @VersionColumn is not used for the same reason: the
version belongs to the aggregate.
// Instead of: a read, then an insert or an update chosen by TypeORM, with no version guardawait manager.save(invoices, { ...invoice.state, version: invoice.version + 1 });
// Write: the guarded statement, which writes no row when another transaction saved firstawait optimisticUpdate(invoice, async ({ expected, next }) => {  // a first save (expected 0) inserts with insertIgnoringConflict instead, as in the repository above  const updated = await manager.update(invoices, { id: invoice.id, version: expected }, { ...invoice.state, version: next });
  return updated.affected ?? 0;});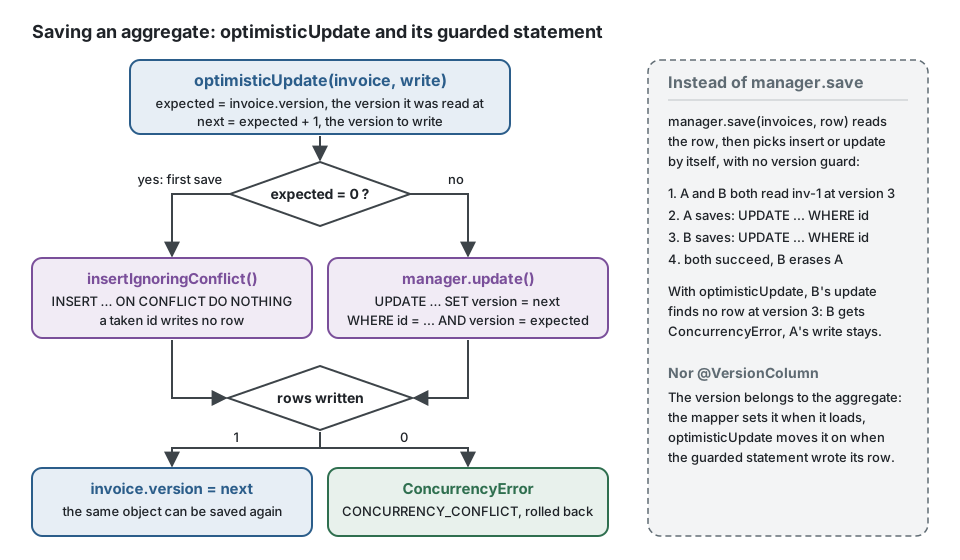
What optimisticUpdate does with the count the write answers, on its own:
import { ConcurrencyError, optimisticUpdate } from '@ddd-ts-kit/typeorm';
// What a repository hands to optimisticUpdate: the aggregate, and a write that answers how many rows it wrote.const invoice = { id: 'inv-1', version: 3 }; // read at version 3
await optimisticUpdate(invoice, async ({ expected, next }) => {  // expected = 3: the guard of the UPDATE (WHERE id = 'inv-1' AND version = 3)  // next = 4: the version the row is written with  return expected === 3 && next === 4 ? 1 : 0;});// invoice.version is now 4: the same aggregate can be saved again
try {  // Another transaction saved inv-1 in between: the guarded UPDATE matches no row.  await optimisticUpdate(invoice, async () => 0);} catch (error) {  if (error instanceof ConcurrencyError) {    console.log(error.code); // CONCURRENCY_CONFLICT; invoice.version is still 4  }}
The command that saved fails with that error and its unit of work rolls back: nothing it wrote stays, and the caller reads the aggregate again before it retries.
A lock on a business key
Section titled “A lock on a business key”Optimistic concurrency protects a row that exists. A decision taken on rows that do not exist
yet (count the bookings of a slot then insert one, give the next number of a sequence per
tenant) has no version to compare: two units of work read the same count and both write.
advisoryLock(context, key, { tenant }) serialises them: it waits until no other transaction
holds the lock on key, then holds it until the unit of work commits or rolls back
(pg_advisory_xact_lock). Nothing releases it by hand.
import { advisoryLock } from '@ddd-ts-kit/typeorm';
async next(): Promise<number> {  // First in the unit of work, before the read it protects.  await advisoryLock(this.context, 'invoice-number', { tenant: this.scope });
return (await this.lastNumber()) + 1;}- The key is a text, hashed by PostgreSQL into the 64-bit number it locks on
(
hashtextextended(text, 0)). Withtenant, anExecutionScope, the text istenant:<id>:<key>(tenantKeyof the kernel): two tenants never wait for each other, and work that names no tenant is refused. Two texts of the same hash, about one pair in 2^64, wait for each other as one key would: a wait, never a wrong answer. - Inside a unit of work only. Outside of one the lock would be released as its statement
ends:
AdvisoryLockOutsideUnitOfWorkError. Keep the default isolation,read committed: the read that follows the lock then sees what the previous holder committed, whererepeatable readandserializableread as of the moment the lock was asked. tryAdvisoryLock(context, key, { tenant })does not wait:truewhen it took the lock,falsewhen another transaction holds it (pg_try_advisory_xact_lock).- A use case imports no ORM package. The lock sits in the method of the repository that
needs it, or behind a port of the context (
InvoiceNumbering.reserve()) whose adapter is this one call and whose fake does nothing. - PostgreSQL only. In a tenant-scoped project,
tenancy/scoped-statementaccepts the helper and reports a rawpg_advisory_xact_lock, as any raw SQL. - Held to
advisoryLockContractof@ddd-ts-kit/testing/contracts. The wait of a second unit of work is proven on a real server: PGlite is one session, where the second one waits for the connection itself.
Audit columns, tenant scoping and pages
Section titled “Audit columns, tenant scoping and pages”The standard persistence shapes of the kernel, on TypeORM. auditColumns(dialect?) and
tenantColumn() are column options to spread into the columns of an EntitySchema: their
properties are those of the kernel AuditStamp and TenantScoped, so a stamp spreads into an
insert as it is, and the columns have the same names in every project (created_at,
created_by, updated_at, updated_by, tenant_id), which is what lets a dashboard, an
export or the audit package be written once.
import type { AuditStamp, TenantScoped } from '@ddd-ts-kit/kernel';import { auditColumns, schemaNameOf, tenantColumn } from '@ddd-ts-kit/typeorm';
interface InvoiceRow extends VersionedInvoice, TenantScoped, AuditStamp {}
export const invoices = new EntitySchema<InvoiceRow>({  name: 'Invoice',  tableName: 'invoices',  schema: schemaNameOf('billing-core'),  columns: {    id: { type: 'text', primary: true },    amount: { type: 'int' },    status: { type: 'text' },    version: { type: 'int' },    ...tenantColumn(),    ...auditColumns(),  },  indices: [{ name: 'invoices_tenant_amount_idx', columns: ['tenantId', 'amount', 'id'] }],});
The tenant reaches every statement through three helpers, which read it from the execution scope
and refuse work that names none (NoCurrentTenantError): tenantWhere(scope) is spread into
the where of a read, as find options or on a query builder (the tenant of the work, or the tenants
an elevation of platform staff reaches, In([...]) or nothing over every tenant),
ownTenantWhere(scope) into the criteria of an update or a delete (the one tenant of the work,
whatever an elevation widens) and tenantScopeOf(scope) of the kernel into an inserted row.
save and upsert are not used: they write by the key, which the tenant is never part of. The
spread stays at the top of the where: a where array is an or of its entries, so each one spreads
it, and a query builder groups its alternatives in new Brackets(...), never in an orWhere at
its top. The rule tenancy/scoped-statement of the CLI holds the adapters of a --tenancy shared-table
project to it, and generate repository writes them this way.
import { Clock, ExecutionScope, stampCreation, stampUpdate, tenantScopeOf } from '@ddd-ts-kit/kernel';import { Repository } from '@ddd-ts-kit/kernel/declarations';import { insertIgnoringConflict, optimisticUpdate, ownTenantWhere, tenantWhere } from '@ddd-ts-kit/typeorm';
@Repository(InvoiceRepository)export class TypeOrmInvoiceRepository implements InvoiceRepository {  constructor(    private readonly context: TypeOrmContext,    private readonly scope: ExecutionScope,    private readonly clock: Clock,  ) {}
  async findById(id: string): Promise<Invoice | undefined> {    const row = await this.context.manager().findOneBy(invoices, { id, ...tenantWhere(this.scope) });
    return row === null ? undefined : InvoiceMapper.toDomain(row);  }
  async save(invoice: Invoice): Promise<void> {    await optimisticUpdate(invoice, async ({ expected, next }) => {      const state = { ...InvoiceMapper.toRow(invoice), version: next };
      return expected === 0 ? this.insert(state) : this.update(state, expected);    });  }
  private async insert(state: VersionedInvoice): Promise<number> {    const row = { ...state, ...tenantScopeOf(this.scope), ...stampCreation(this.scope, this.clock) };
    return (await insertIgnoringConflict(this.context.manager(), invoices, row)) ? 1 : 0;  }
  private async update(state: VersionedInvoice, expected: number): Promise<number> {    const guarded = { id: state.id, version: expected, ...ownTenantWhere(this.scope) };    const row = { ...state, ...stampUpdate(this.scope, this.clock) };
    return (await this.context.manager().update(invoices, guarded, row)).affected ?? 0;  }}
TypeORM's @CreateDateColumn and @UpdateDateColumn are not used: they take the time of the
database server, not of the Clock, and know nothing of who acts.
A search query takes the kernel PageRequest and answers a Page, in both variants:
export abstract class InvoiceQueries { abstract search(request: PageRequest<'amount'>): Promise<Page<InvoiceSummary>>;}import { LessThan, MoreThan, type FindOptionsWhere } from 'typeorm';import { ExecutionScope, encodeCursor, pageOf } from '@ddd-ts-kit/kernel';import { Repository } from '@ddd-ts-kit/kernel/declarations';import { tenantWhere, type TenantWhere } from '@ddd-ts-kit/typeorm';
@Repository(InvoiceQueries)export class TypeOrmInvoiceQueries implements InvoiceQueries { constructor( private readonly context: TypeOrmContext, private readonly scope: ExecutionScope, ) {}
async search(request: PageRequest<'amount'>): Promise<Page<InvoiceSummary>> { return request.kind === 'offset' ? this.byOffset(request) : this.byCursor(request); }
private async byOffset(request: OffsetPageRequest<'amount'>): Promise<Page<InvoiceSummary>> { const [rows, total] = await this.context.manager().findAndCount(invoices, { where: tenantWhere(this.scope), order: totalOrder(directionOf(request)), take: request.limit, skip: request.offset, });
return pageOf(rows.map(toSummary), { total }); }
private async byCursor(request: CursorPageRequest<'amount'>): Promise<Page<InvoiceSummary>> { const direction = directionOf(request); const tenant = tenantWhere(this.scope); const rows = await this.context.manager().find(invoices, { where: request.cursor === undefined ? tenant : beyond(positionOf(request.cursor), direction, tenant), order: totalOrder(direction), take: request.limit + 1, }); const items = rows.slice(0, request.limit); const last = items.at(-1); const more = rows.length > request.limit && last !== undefined;
return pageOf(items.map(toSummary), more ? { nextCursor: encodeCursor({ amount: last.amount, id: last.id }) } : {}); }}
const directionOf = (request: PageRequest<'amount'>) => request.sort[0]?.direction ?? 'asc';
// The primary key follows the sort field, in the same direction: the order is total.const totalOrder = (direction: SortDirection) => ({ amount: direction, id: direction });
// The rows after a position, as a tuple comparison. A list of conditions is an OR in TypeORM,// so each alternative restates the tenant.function beyond( { amount, id }: { amount: number; id: string }, direction: SortDirection, tenant: TenantWhere,): FindOptionsWhere<InvoiceRow>[] { const past = direction === 'asc' ? MoreThan : LessThan;
return [ { ...tenant, amount: past(amount) }, { ...tenant, amount, id: past(id) }, ];}positionOf(cursor) decodes with decodeCursor and checks that amount is a number and id
a string, raising InvalidPageRequestError otherwise.
A read adapter over the database is declared with @Repository, as the ones the CLI
generates: its kind is repository. Declared with @Adapter it would be external, and a
generated platform puts a retry and a time limit around every external and gateway
adapter, which a statement of the unit of work must not get.
The rules these examples hold, and that the tests of this package check on a real database:
- Audit columns are filled by the adapter, never by the aggregate:
stampCreation(scope, clock)on insert,stampUpdate(scope, clock)on update, which leavescreated_atandcreated_byalone. The actor is the one of the execution scope: the user of the request, orsystem:<consumer>for a consumed event. - The tenant is part of every statement: written on insert (
tenantScopeOf), and in the condition of every read (tenantWhere) and every update (ownTenantWhere), the version guard included. A row of another tenant is not found, and an update aimed at it writes nothing, whichoptimisticUpdatereports as aConcurrencyError. An elevation of platform staff widens what a read reaches, never what a write touches. Work that names no tenant raisesNoCurrentTenantErrorbefore any SQL. The tenant isolation contract of@ddd-ts-kit/testingproves it on this repository. - A list has a total order. The primary key follows the sort field, in the same direction,
as a tie-breaker: rows equal on the sort field otherwise have no defined order, and a page
could repeat or skip one of them. The index covers
(tenant_id, <sort field>, id). - A cursor is a position, not a page number: the sort value and the id of the last row,
written by
encodeCursor, compared as a tuple (`amount > :amount OR (amount = :amount AND id:id)
). One row more thanlimitis fetched to know whether a page follows, so no count is needed, and a row inserted before the cursor does not shift the next page as it does with an offset. A cursor comes back from a client:decodeCursor` refuses what it did not write, and the adapter checks the types of the position before they reach a statement. - An offset page answers
total, a cursor pagenextCursor. Offer the offset form for small, browsable lists and the cursor form for anything that grows.
Criteria
Section titled “Criteria”criteriaToTypeOrm(builder, plan, { alias }) adds a criteria plan of the kernel to a
SelectQueryBuilder on the entity of a read model: the filters and the scope of the actor,
the keyset of a cursor page, the total order ended by the tie-breaker, the window.
predicateToTypeOrm(builder, predicate, { alias }) adds the filters alone, for a count. The
fields of the read model are the properties of the entity (properties renames those that
differ). Every value is a named parameter; the only text composed is alias.property with an
operator of a closed list, both from the adapter. A text search is LIKE :p ESCAPE :e with
%, _ and \ escaped. containsIgnoringCase and startsWithIgnoringCase are the same search as an ILIKE, which PostgreSQL folds with the locale of the database (the rule and its limits are in the README of the kernel, "What a criteria means"); no b-tree index serves it, a GIN index of pg_trgm on the column does.
async search(criteria: ScopedCriteria<AppointmentRow>): Promise<Page<AppointmentRow>> {  const plan = planCriteria(appointmentCriteria, criteria);
  if (plan.empty) {    return pageOfPlan(plan, []);  }
  const builder = this.context.manager().createQueryBuilder(appointmentList, 'row');
  return pageOfPlan(plan, await criteriaToTypeOrm(builder, plan, { alias: 'row' }).getMany());}
A cursor page is fetched one row longer than asked, which is how pageOfPlan knows whether
another follows; an offset page takes its total from predicateToTypeOrm(...).getCount(). A
field declared nullable is ordered NULLS LAST ascending and NULLS FIRST descending. Two
criteria in one query take distinct parameter names with the parameters option.
Strings. A text column is ordered and compared by range in the collation of the column;
criteria order strings by code point. Declare the text columns that are sorted or compared
with gt, lt or between with collation: 'C': the index then serves the sort, and the
order is the same as in the fake. Decimals are a numeric column and a string in the
row; they read back in the scale of the column. Instants are timestamptz and a Date.
An integer is integer: a bigint comes back as a string from the driver.
Read models
Section titled “Read models”export const appointmentList = new EntitySchema<AppointmentRow & ReadModelStamps>({ name: 'AppointmentRow', tableName: 'appointment_list', schema: 'scheduling', columns: { id: { type: 'text', primary: true }, status: { type: 'text', nullable: true }, // NULL in a deleted row, as every column of the row startsAt: { name: 'starts_at', type: 'timestamp with time zone', precision: 3, nullable: true }, ...readModelColumns(), // last_event_id, last_event_at, last_event_version, deleted },});
// infrastructure/persistence/type-orm-appointment-list.repository.ts@Repository(AppointmentList)export class TypeOrmAppointmentList extends TypeOrmReadModelStore<AppointmentRow> implements AppointmentList { constructor(context: TypeOrmContext) { super(context, { entity: appointmentList, definition: appointmentCriteria }); }}Every write goes through TableReadModelStore of the kernel: a row is written only if its
event is newer than the one it holds, on the executor of the unit of work, so the row and the
processed-event mark commit together. A removed row stays in the table as a trace, with deleted
set: its key and its stamp, and NULL in every other column, which is why every column of the row
is nullable. A deletion of a key the table does not hold yet leaves the same trace. A check
constraint keeps the live rows whole (check (deleted or (status is not null and starts_at is not null))), a query of your own on the table leaves the deleted rows out (deleted = false),
and a table whose columns refuse NULL is refused with ReadModelTableNotReadyError, when the store is built from its definition and, before the first
trace is written, from one read of the columns the database holds
(What a deleted row leaves). An application does not wait for that first trace: tableState() of a TypeOrmReadModelStore reads its table as the store does before its first trace, for the columns it maps and no other, and ReadModelTables of the kernel asks it of every store the application lists, then refuses with ReadModelTablesNotReadyError, which names each table that is not ready, what keeps it from it and the migration to write in two steps, and each table it could not read; a generated project keeps the list, checks at its start the tables of the contexts it hosts, and npm run db:read-models checks it before a deployment (Every table checked at the start, and before a deployment). store.table is what ProjectionRebuild takes; the rebuild is
PostgreSQL only (a copy <table>__rebuild made LIKE ... INCLUDING ALL, the keys written
meanwhile in <table>__touched, the swap by rename in one transaction) and its guarantees
and limits are in the README of @ddd-ts-kit/kernel (Rebuild). The store passes
criteriaContract and readModelStoreContract of @ddd-ts-kit/testing/contracts, on PGlite
and on PostgreSQL 18.
Criteria and read models were never run on MySQL or SQLite.
The table is written through its entity; the copy of a rebuild, which has none, is written by column through the same query builder.
A read model of tenant data takes tenant: { scope } (and property when the entity holds the
tenant other than in tenantId, which tenantColumn() declares): every row is written with the
tenant of the work in progress, every read, search and write is confined to it, an elevation of
platform staff widening the reads only, and the copy of a rebuild follows the same conditions.
The rows a read answers hold every column of the entity but the stamps, the tenant with them; when
the row of the port does not carry its tenant, declare the column select: false
(tenantId: { ...tenantColumn().tenantId, select: false }, the entity typed
Row & TenantScoped & ReadModelStamps): the store still writes it and filters on it, and leaves it
out of the rows.
Keys stay unique across tenants, as the conflict of an insert is on the key alone: a key two
tenants could share (a day, a slug) carries the tenant (acme:2026-03-01). A store built without
tenant in a --tenancy shared-table project is reported by tenancy/scoped-statement.
Personal data erasure
Section titled “Personal data erasure”The erasure of a data subject from the tables of a context, from the personalFields declarations
written next to its mappers (@ddd-ts-kit/kernel, "Personal data"): TypeOrmPersonalDataErasure implements
the PersonalDataErasure port over the entity manager of the unit of work. The port of the context extends the one of the kernel, and
its adapter extends this class.
// infrastructure/persistence/person.personal-fields.ts: the entity schema itself, the columns by the properties of the entityexport const personPersonalFields = personalFields<PersonRow, EntitySchema>(personEntity, {  subject: 'id',  fields: ['displayName', 'email'],  erasure: 'row',});
// infrastructure/persistence/type-orm-identity-erasure.repository.ts@Repository(IdentityErasure)export class TypeOrmIdentityErasure extends TypeOrmPersonalDataErasure implements IdentityErasure {  constructor(database: TypeOrmContext, scope: ExecutionScope, files: FileStorage) {    super(database, { name: 'identity.persons', declarations: [personPersonalFields], tenant: { scope }, files });  }}
erase(subject) deletes the files the rows name from the storage first, then deletes the rows of
the subject (row) or pseudonymises them (pseudonymise: a text column reads [erased], a column
of any other type reads nothing, a file column nothing), and answers how many rows it reached, none
the second time. With tenant, every statement is confined to the tenant of the work and never
widened by an elevation (the property tenantId, or tenant.property); without it, the table holds the rows of every tenant. A subject
that is not an opaque identifier is refused before any statement, and a declaration that names file
columns without a file storage is refused when the adapter is built. The types of the columns come from the metadata of the entity (String stands for a text), so that a text and a number are pseudonymised each its own way. A personal column
that is not a text has to accept null, or the rows are erased with row: a declaration that would
pseudonymise one that does not is refused before any file or row is touched
(NotNullablePersonalColumnError). The adapter passes
personalDataErasureContract of @ddd-ts-kit/testing, as the in-memory one does, on PGlite and
PostgreSQL. What an erasure does not reach, and the whole chain (eraseDataSubject: the key, every
copy in every tenant, the rebuilds), is in the README of the kernel ("Personal data").
TypeOrmPersonalDataExport answers the right of access and to portability from the same declarations:
exportOf(subject) hands over one PersonalDataRecord per row about the subject in every declared
table, under <name>.<table>, with each personal column and each file column (by its key) as plain
data, by the properties of the entity, no other column and nothing of anyone else; a row pseudonymised already
answers what it reads. The same tenant option confines every statement to the tenant of the work, a
subject that is not an opaque identifier is refused before any statement, and the adapter passes
personalDataExportContract. The port of the context extends PersonalDataExport of the kernel and
its adapter extends this class with name, declarations and tenant (TypeOrmPersonalDataExportOptions);
generate repository --personal writes both adapters, and exportDataSubject of the kernel gathers
every export into one dated document. Wrap the adapter with auditedPersonalDataExport of
@ddd-ts-kit/audit where it is bound, so that each handover leaves an entry.
The same declarations give the storage limitation (GDPR article 5(1)(e)): a declaration with
retention: { after: 'endedAt', months: 36 } says how long its rows keep the person, counted from a
date column of the row, and purgeExpired(now) of the erasure adapter erases, as the declaration
says, the rows whose date is older than the period; a row whose date is empty never expires, and a
second run reaches nothing. It confines itself to the tenant of the work when the work names one,
and reaches every tenant when it names none, as the nightly job of the platform does: a tenant left
out of a list would keep what it should not. The adapter implements PersonalDataRetention of the
kernel and passes personalDataRetentionContract; purgeExpiredPersonalData of the kernel runs
every copy, and auditedPersonalDataRetention of @ddd-ts-kit/audit records each purge.
Outbox and idempotency
Section titled “Outbox and idempotency”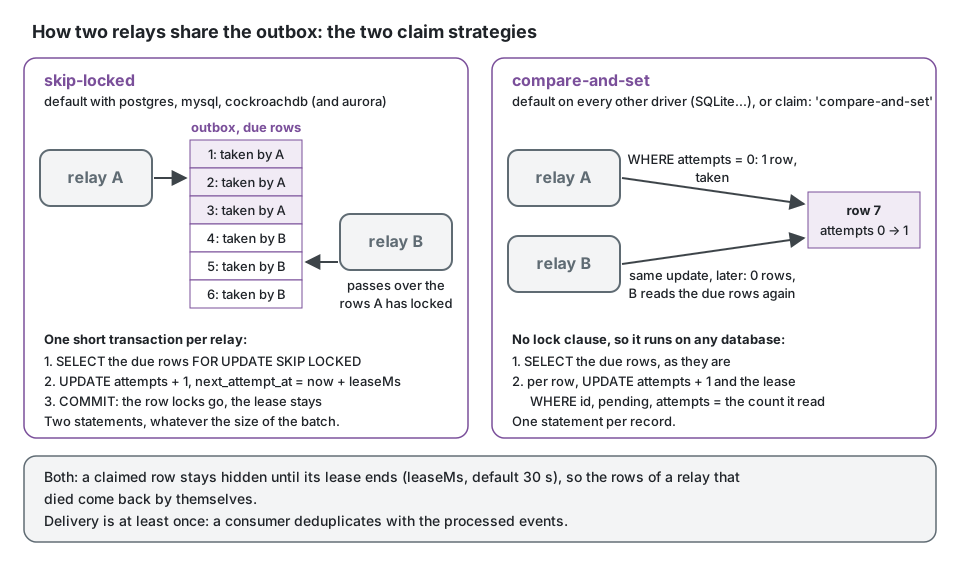
TypeOrmOutboxStore.claimBatchselects the due rowsFOR UPDATE SKIP LOCKED(setLock('pessimistic_write').setOnLocked('skip_locked')) and leases them in the same short transaction by pushingnext_attempt_atforward (leaseMs, default 30 s), so several relays share the work without waiting for each other, and the records of a relay that died come back when the lease expires. Delivery is at least once and, by default, unordered:ordering: 'per-key'ofOutboxRelay, given akeyOf(typically the aggregate id), keeps the records of one key in order, with a single relay (Ordering per key).- Where the database has no
SKIP LOCKED(SQLite), or when you passclaim: 'compare-and-set', the claim reads the due rows and takes each one with an update guarded by the attempt count it read: same guarantee, no lock clause, one statement per record. The default isskip-lockedfor thepostgres,aurora-postgres,cockroachdb,mysqlandaurora-mysqldrivers,compare-and-setfor every other one. TypeOrmProcessedEventStore.markProcessedis an insert ignoring the conflict on(consumer, event_id). Run the consumer inside the unit of work: the mark then commits with the effects of the handler, and disappears with them if it fails.outboxEntity({ tenant: true })addstenant_id, nullable, and the store writes the tenant of each event to it, so that its consumers run in that tenant: the outbox of a multi-tenant project. A project that becomes multi-tenant turns it on and generates the migration that adds the column; the events published before it belong to no tenant.
The options of the outbox store, and the relay that reads it:
import { OutboxRelay } from '@ddd-ts-kit/events';import type { Clock, IntegrationEventPublisher } from '@ddd-ts-kit/kernel';import { outboxEntity, TypeOrmOutboxStore, type TypeOrmUnitOfWork } from '@ddd-ts-kit/typeorm';
// From the composition root: createTypeOrmUnitOfWork(dataSource), the broker adapter, the clock.declare const unitOfWork: TypeOrmUnitOfWork;declare const broker: IntegrationEventPublisher;declare const clock: Clock;
export const outbox = outboxEntity({ schema: 'messaging' }); // the entity the data source registers
const store = new TypeOrmOutboxStore(unitOfWork, {  entity: outbox,  leaseMs: 60_000, // a record claimed by a relay that died is due again after one minute  claim: 'compare-and-set', // instead of the default of the driver, e.g. on MySQL 5.7});
const relay = new OutboxRelay({ store, publisher: broker, clock });
relay.start({ intervalMs: 500 });
A consumer on the processed-event store: consume of @ddd-ts-kit/events runs the mark and
the handler in one unit of work (Consume idempotently).
import { z } from 'zod';import { consume, defineIntegrationEvent } from '@ddd-ts-kit/events';import { zodSchema } from '@ddd-ts-kit/validation/zod';import { processedEventEntity, TypeOrmProcessedEventStore, type TypeOrmUnitOfWork } from '@ddd-ts-kit/typeorm';
// From the composition root and the context: the unit of work, and what the consumer does.declare const unitOfWork: TypeOrmUnitOfWork;declare function issueInvoice(orderId: string): Promise<void>;
// The declaration of the producer, in its published language.const orderPlaced = defineIntegrationEvent({  type: 'ordering.order.placed',  version: 1,  description: 'An order was placed by a customer.',  payload: zodSchema(z.object({ orderId: z.string() })),});
const processed = new TypeOrmProcessedEventStore(unitOfWork, {  entity: processedEventEntity({ schema: 'messaging' }),});
// The mark in messaging.processed_events and the writes of issueInvoice commit in one transaction:// a redelivery is skipped, and an event whose handler threw is handled again when it comes back.export const invoiceOnOrderPlaced = consume(  orderPlaced,  { consumer: 'billing.invoice-on-order-placed', processed, unitOfWork },  async (event) => {    await issueInvoice(event.payload.orderId);  },);
Background jobs and process instances
Section titled “Background jobs and process instances”jobEntity() and processEntity() are the two tables, on PostgreSQL, to register with the data
source next to the outbox (init --orm typeorm puts them in the messaging schema).
TypeOrmJobStoreis theJobStoreof@ddd-ts-kit/scheduling.addruns on the manager of the context: a job enqueued by a command exists if and only if the command committed. A claim takes the due rows of the queueFOR UPDATE SKIP LOCKEDand leases them in a short transaction, so several workers pass over each other's rows. An idempotency key is unique per job name and tenant; a duplicate is skipped by an insert that ignores the conflict, which leaves the transaction of the command usable.TypeOrmProcessStoreis theProcessStoreof the kernel: a step of a process manager saves its instance in the transaction of its unit of work, a first save skips the row a concurrent first save wrote, a next one updates the row at the previous version, and a save that changes no row is refused withConcurrencyError. Withtenant(theExecutionScope), the store keeps each instance in the tenant of the work that saves it: the table keys a row by its tenant too, the empty text outside any, so two tenants may use the same correlation key; an instance of another tenant is neither found nor changed, and work that names no tenant is refused withNoCurrentTenantError.
import {  jobEntity,  processEntity,  TypeOrmJobStore,  TypeOrmProcessStore,  type TypeOrmUnitOfWork,} from '@ddd-ts-kit/typeorm';
// From the composition root: `createTypeOrmUnitOfWork(dataSource)`.declare const unitOfWork: TypeOrmUnitOfWork;
// Registered in the `entities` of the data source, migrated like the other tables.export const jobs = jobEntity({ schema: 'messaging' });export const processes = processEntity({ schema: 'messaging' });
export const jobStore = new TypeOrmJobStore(unitOfWork, { entity: jobs });export const processStore = new TypeOrmProcessStore(unitOfWork, { entity: processes });
Event store
Section titled “Event store”const dataSource = new DataSource({ type: 'postgres', entities: [...eventStoreEntities({ schema: 'scheduling' })] });
const { events, snapshots, checkpoints, subjectKeys } = createTypeOrmEventSourcing(unitOfWork, { schema: 'scheduling' });eventStoreEntities declares the tables as EntitySchemas, so typeorm migration:generate
creates them with the columns of eventStoreTablesSql of the kernel. The stores never load them
as entities. The stores of createTypeOrmEventSourcing refuse a data source that is not
PostgreSQL: their first statement throws a TypeError that names its type.
Each statement runs on the executor of the context: an append joins the transaction of the
unit of work, so the stream and the outbox records its events publish commit together
(eventStoreUnitOfWorkContract). Appends take the head of the store, a row locked until their
transaction ends: positions are given in commit order, without gaps, and two appends never run
side by side, whatever their streams. PostgreSQL only. The stores are the ones of the kernel
(PostgresEventStore and its companions), held to eventStoreContract here; how an
event-sourced aggregate uses them: the README of @ddd-ts-kit/kernel, section
Event sourcing.
Dialect coverage
Section titled “Dialect coverage”What follows is about this package. The CLI generates for PostgreSQL only: init --orm typeorm
refuses --database mysql and --database sqlite.
| Database | Status |
|---|---|
| PostgreSQL | Covered by the automated suite: contract suites of @ddd-ts-kit/testing, repository contract, rollback, nested unit of work, concurrent claims, the job store and the process store (PostgreSQL only). It runs on PGlite served over the PostgreSQL wire protocol by default, and on a real server when DDD_TS_KIT_TEST_DATABASE_URL is set (last run: PostgreSQL 18). |
| MySQL 8 | Not in the automated suite. The outbox and processed-event contract suites and the rollback of append were run once by hand against MySQL 8.4 with mysql2, entities built with dialect: 'mysql', with skip-locked and compare-and-set. |
| SQLite | Not in the automated suite. The same suites were run once by hand with the better-sqlite3 driver, entities built with dialect: 'sqlite'. No SKIP LOCKED: the claim is compare-and-set. No schemas: leave schema out and name the tables per context. |
| MariaDB, CockroachDB, SQL Server, Oracle, MongoDB | Never run. |
Limits
Section titled “Limits”- Tested with TypeORM 1.1. The peer range is
^1.0.0: TypeORM 0.3 is not accepted. - An
EntitySchemais static: the column types depend on thedialectyou pass, not on the data source it is registered in. - A JSON
nullpayload is stored as SQLNULLand read back asnull. - On MySQL 5.7 there is no
SKIP LOCKED: passclaim: 'compare-and-set'. synchronize: trueis for tests. In production the tables come from your migrations.- By default ordering is not guaranteed, not even per aggregate: a failed event is retried
later while its successors go out.
ordering: 'per-key'ofOutboxRelay, given akeyOf, orders the records of one key, with a single relay running. WithoutkeyOfnothing is ordered.
Testing an adapter
Section titled “Testing an adapter”The unit of work of this package passes unitOfWorkContract, and its stores
outboxStoreContract, processedEventStoreContract, jobStoreContract and processStoreContract, of @ddd-ts-kit/testing/contracts. Hold your repositories to repositoryContract the same way,
next to their in-memory fake. The tests of this package need no container:
npx vitest run packages/typeormDDD_TS_KIT_TEST_DATABASE_URL=postgresql://user:password@localhost:5432/postgres npx vitest run packages/typeormWith the variable set, each spec file creates a database of its own on that server and drops it afterwards, and the tests that need two real connections (a relay passing over rows locked by another one) run instead of being skipped.
See also
Section titled “See also”- Persistence: choosing an ORM, and what each adapter package verified
- Aggregates: optimistic concurrency, seen from the domain
- The transactional outbox: why the outbox record commits with the business write
- Delivery and idempotency: at least once, and what a consumer does about it
@ddd-ts-kit/drizzle: the same pieces on Drizzle, the default persistence of the kit